
Report from October 7, 2026
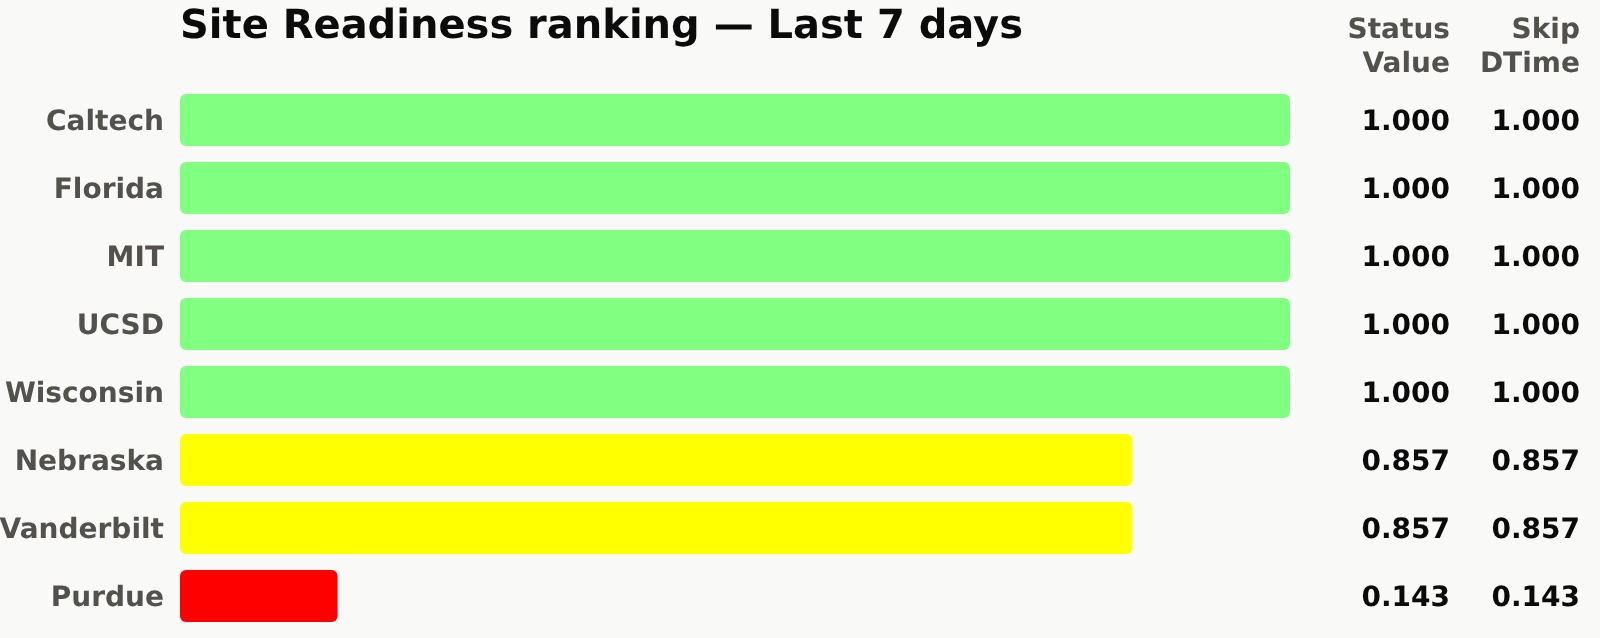
SiteReadiness: 100.0%
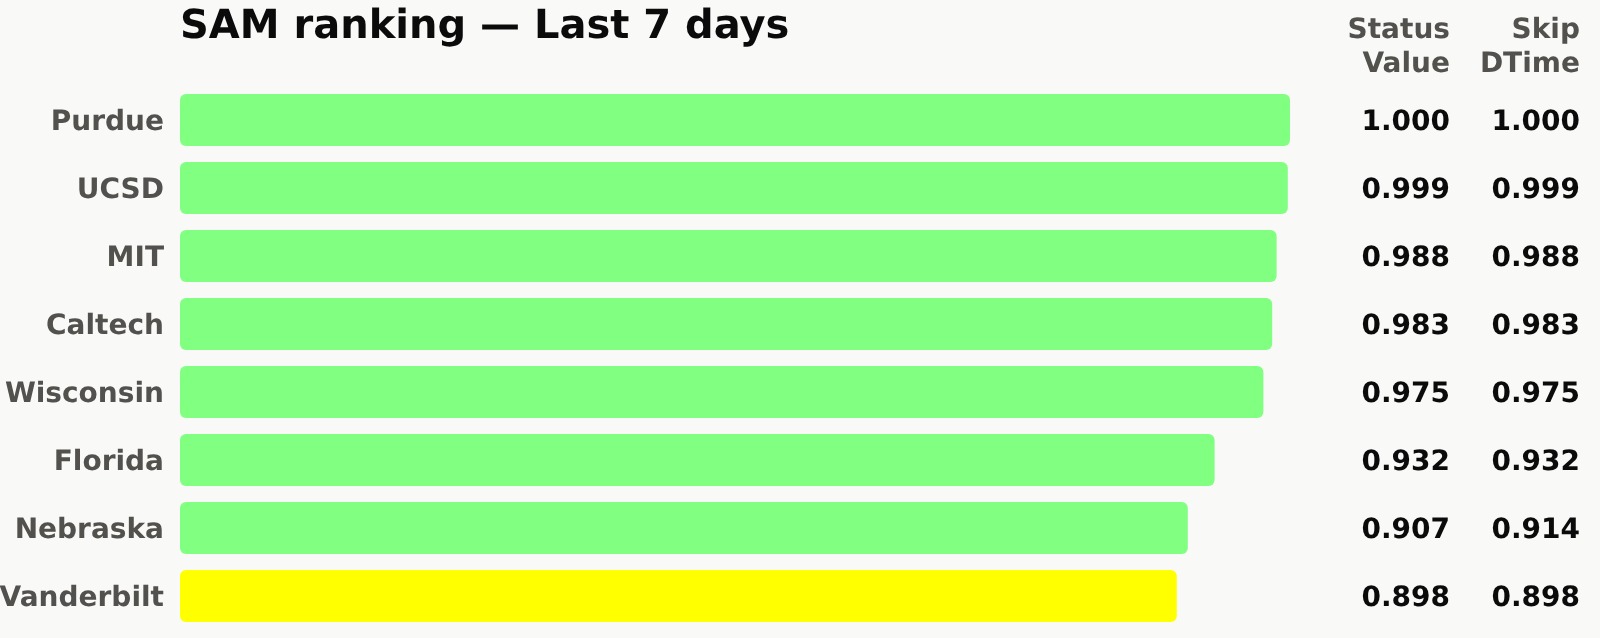
SAM tests: 98.8%
No significant problems over last week. Our focus was on repairing worker nodes and XRootD servers.
Report from Sep. 16, 2026
SiteReadiness: 100.0%
SAM tests: 99.6%
No significant problems over last week. While investigating XRootD/network problems last week we discovered that our disk end point is bombarded by calls that one would see for the tape end point, like requests to stage files.
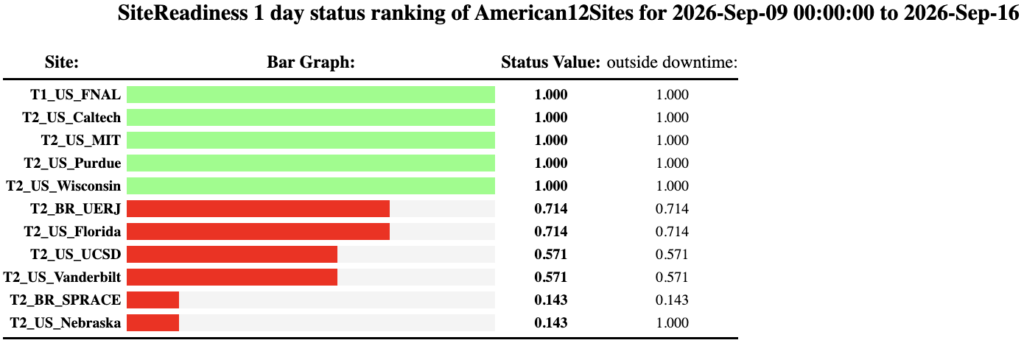
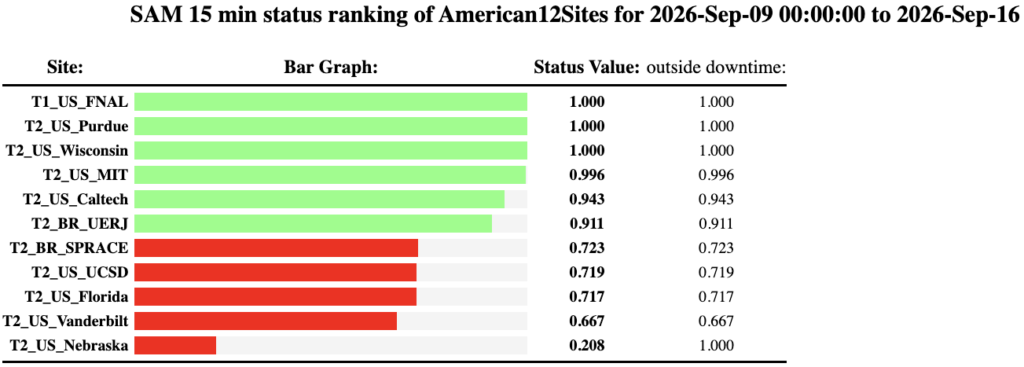
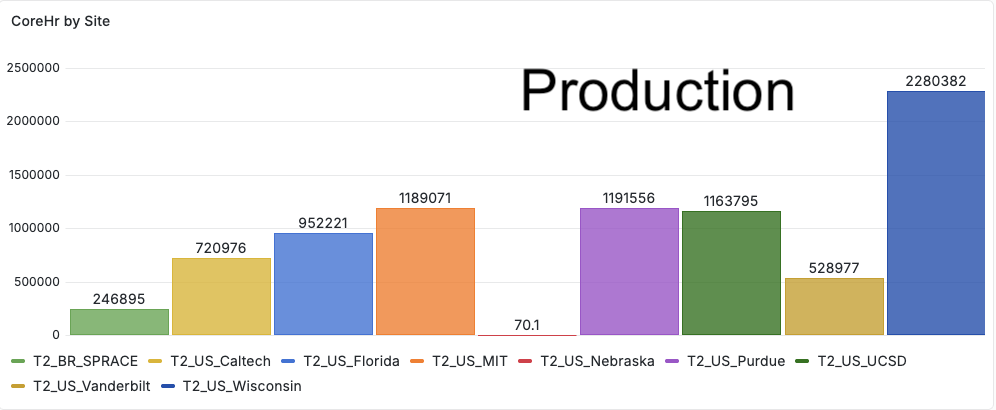
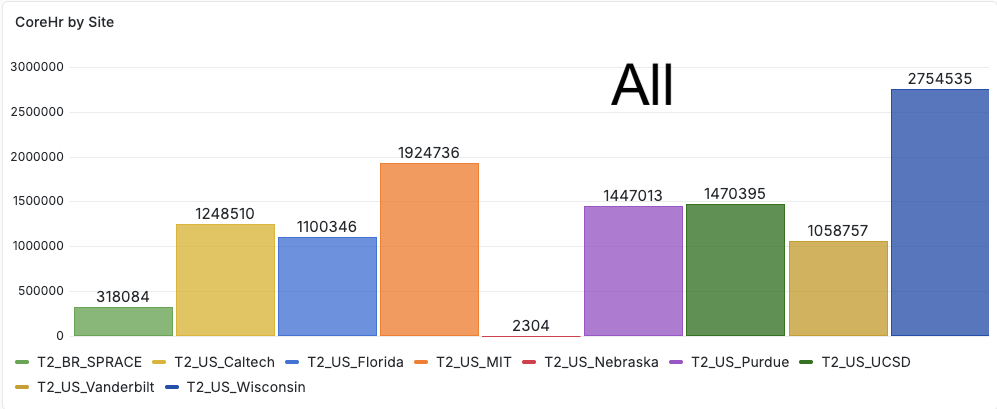
Report from Sep. 9, 2026
SiteReadiness: 57.1%
SAM tests: 82.1%
We had problems with XRootD SAM probes sporadically failing over the period of 4 days. At the same time we observed significantly increased incoming network traffic. We do not fully understand the root cause of a problem, investigating.
Report from Sep. 2, 2026
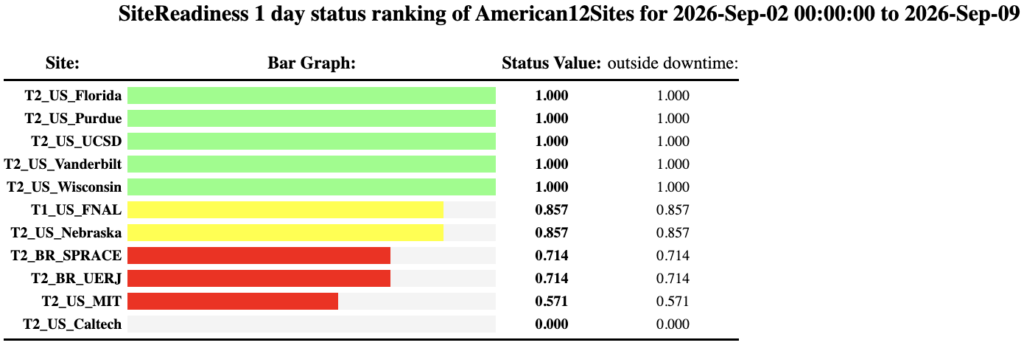
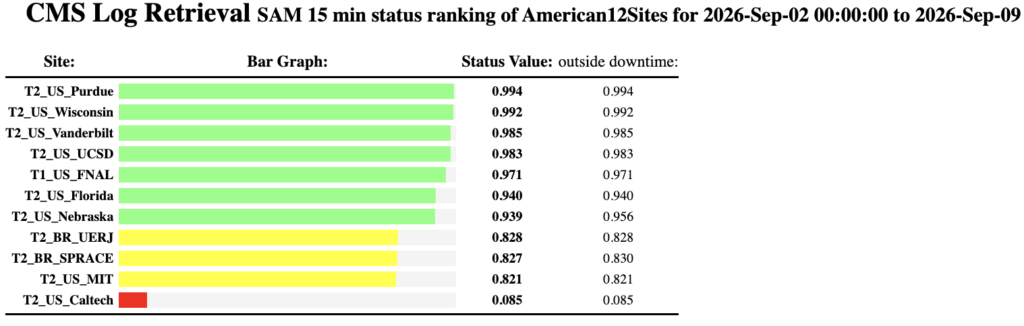
SiteReadiness: 100.0%
SAM tests: 91.5%
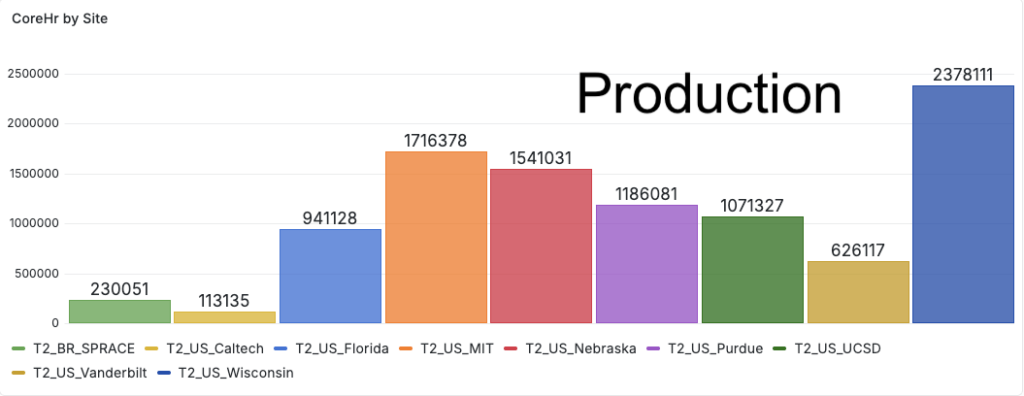
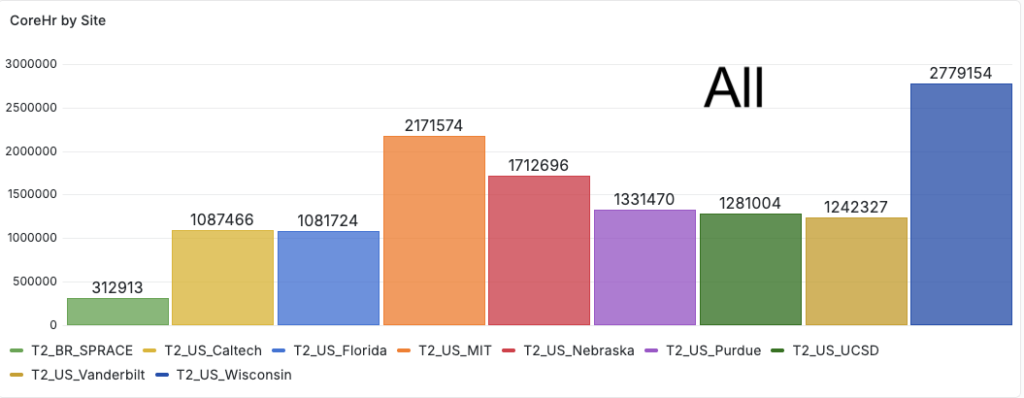
We upgraded one of our CEs to Alma9, and in the process of upgrading the second CE. Condor for some time remained in unbalanced state that affected average number of jobs running, as well as SAM test efficiency.
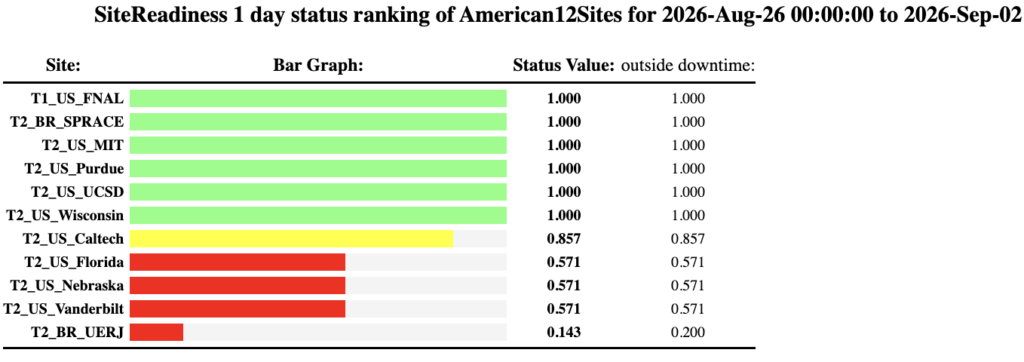
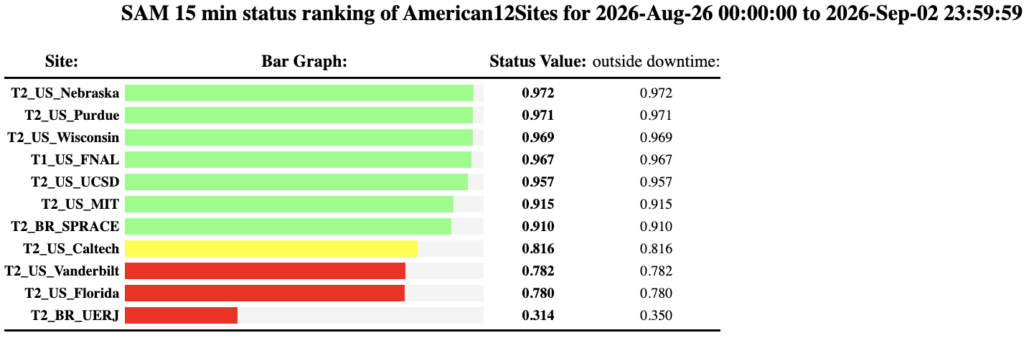
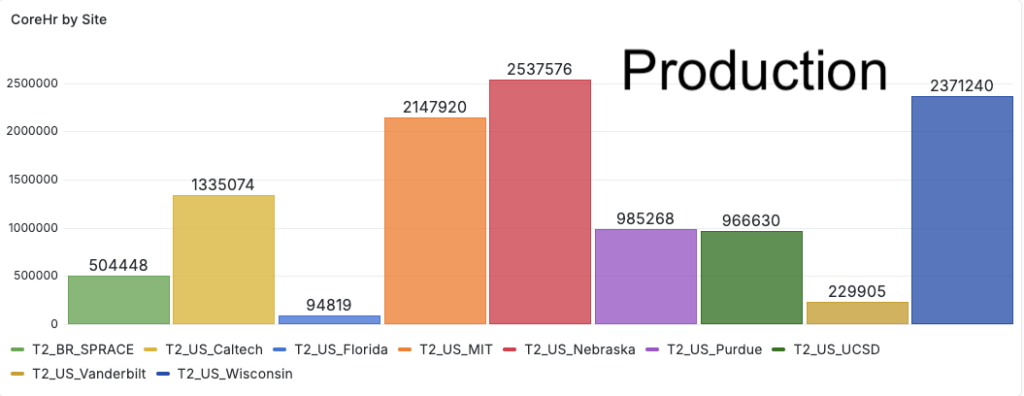
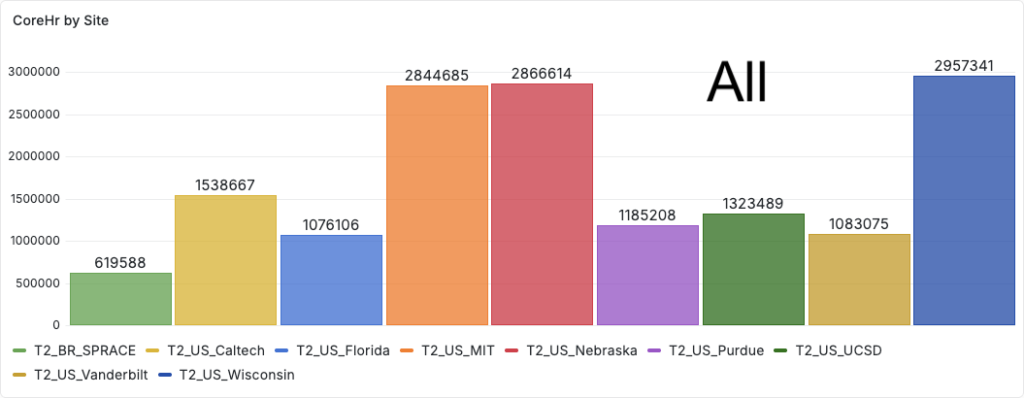
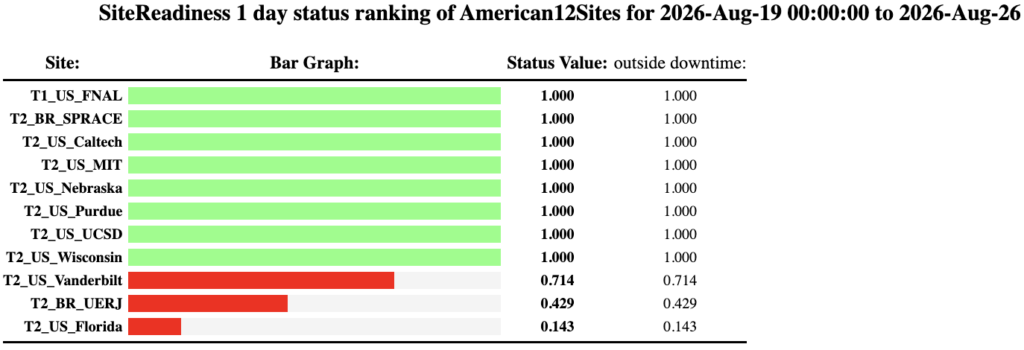
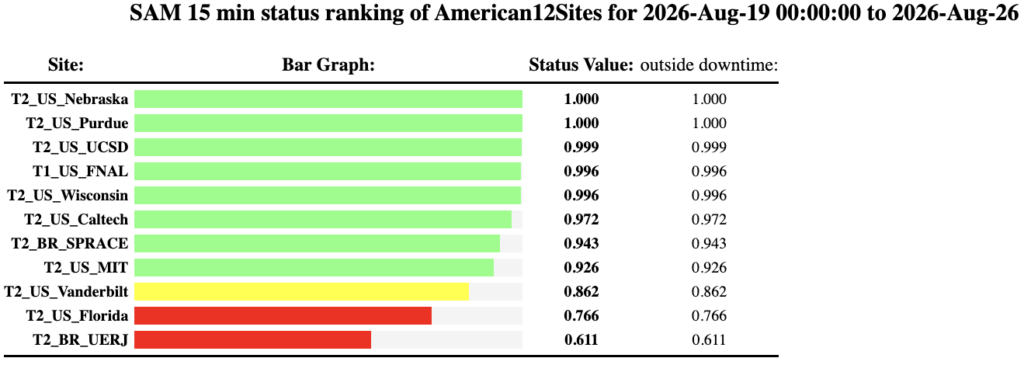
Report from Aug. 26, 2026
SiteReadiness: 100.0%
SAM tests: 92.6%
We continue upgrading worker nodes to Alma9. Condor seems to be unbalanced at the moment; jobs sometimes go into held state; SAM jobs periodically do not get scheduled promptly leading to the SAM test inefficiency.
Report from July 29, 2026
SiteReadiness: 100.0%
SAM tests: 93.8%
Quiet last seven days. One of our CEs is down as we are upgrading it to Alma9 and modern Condor version.
Report from July 15, 2026
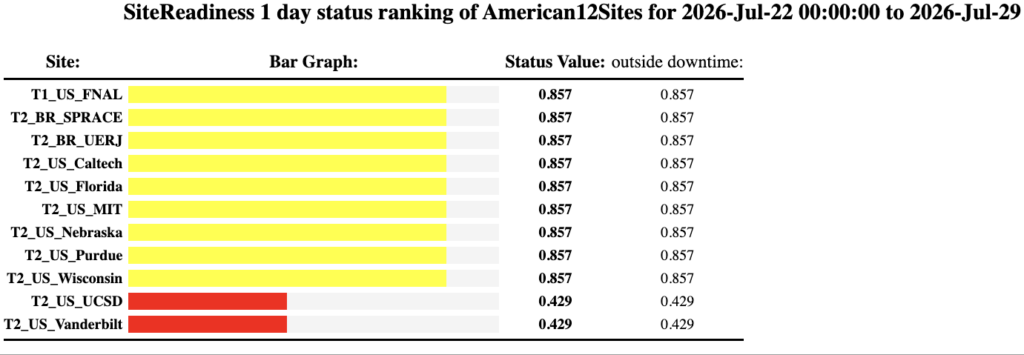
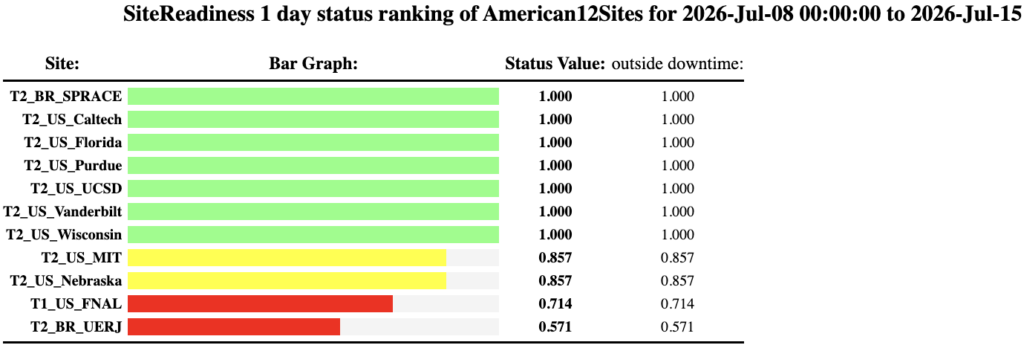
SiteReadiness: 85.7%
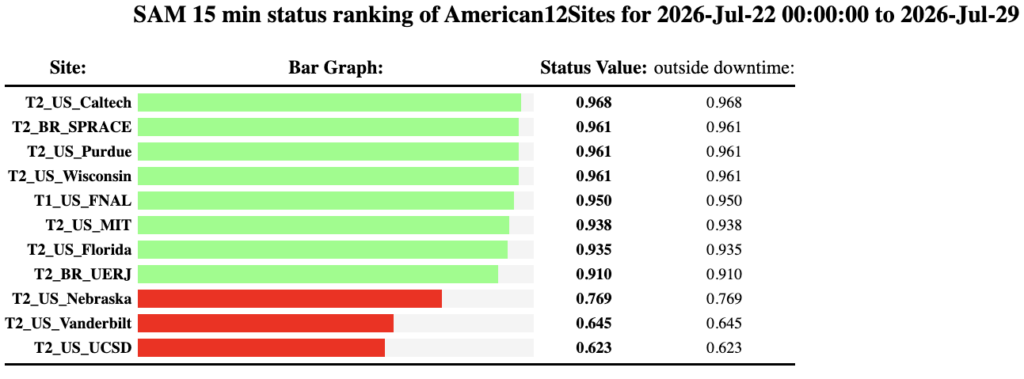
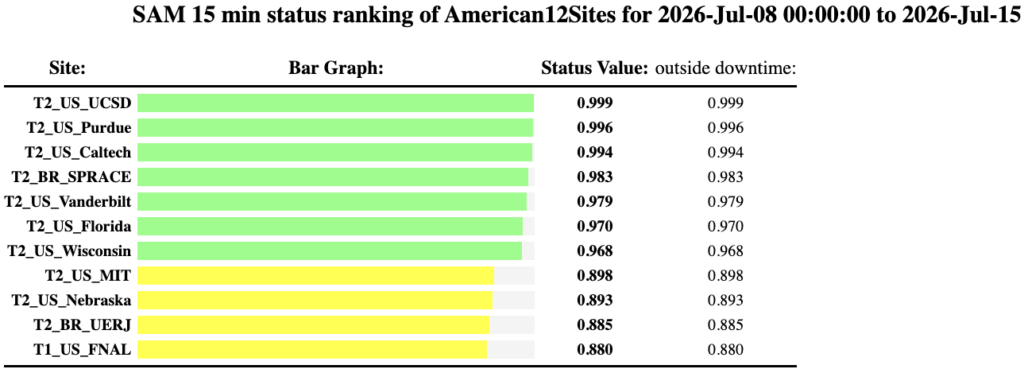
SAM tests: 89.8%
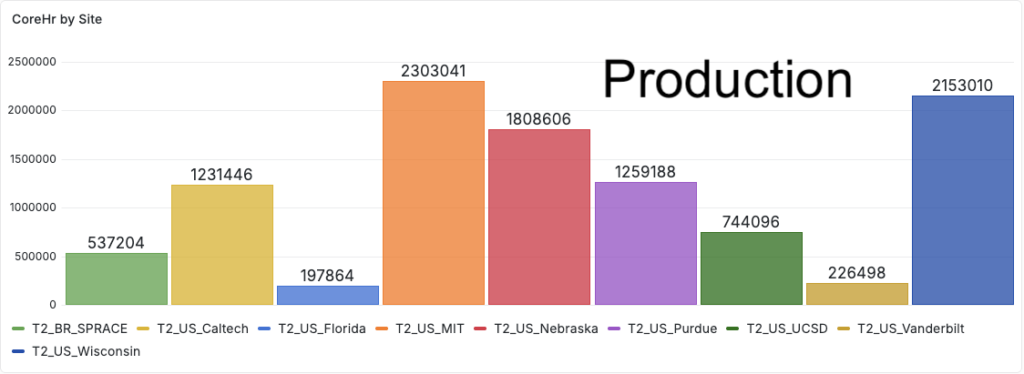
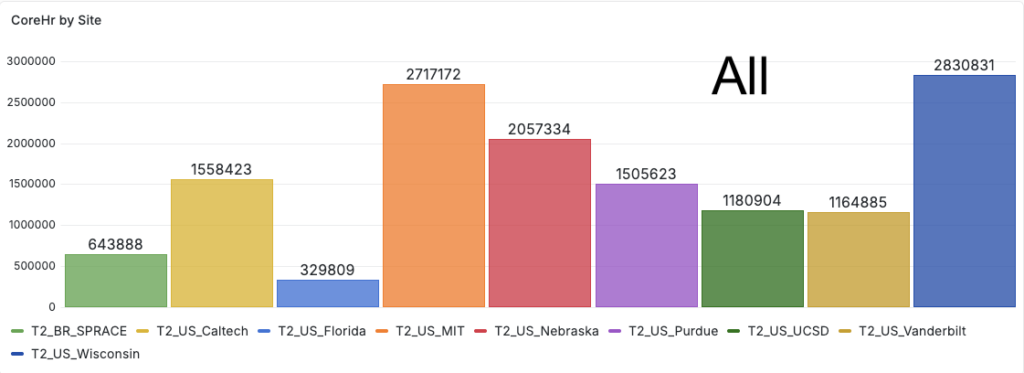
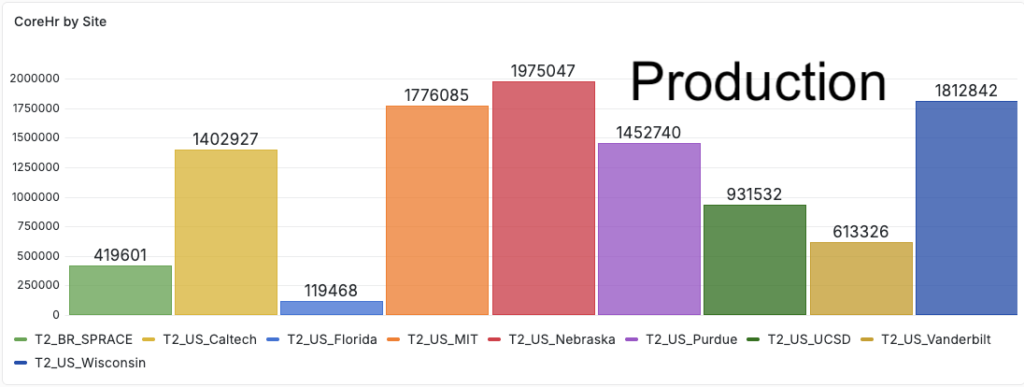
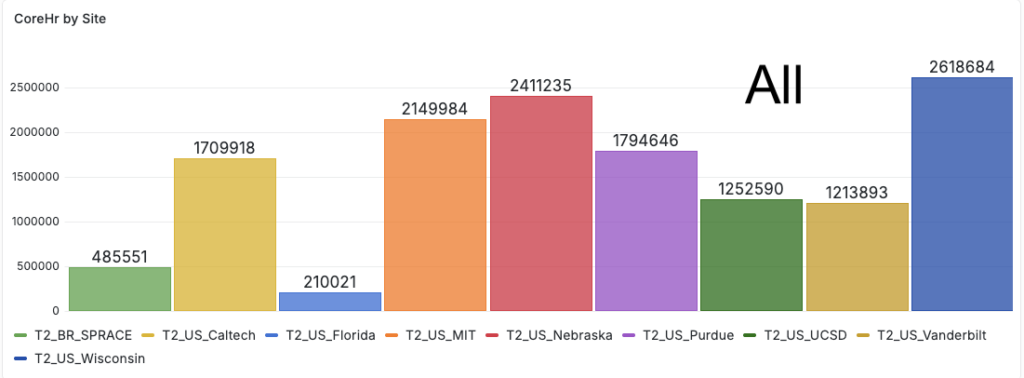
We had a downtime on Tuesday July 14. Host facility was upgrading electrical infrastructure. The cluster was brought offline at 6 am (ET), including storage and administrative servers. All services were fully back online at around 9 pm.
Report from July 8, 2026
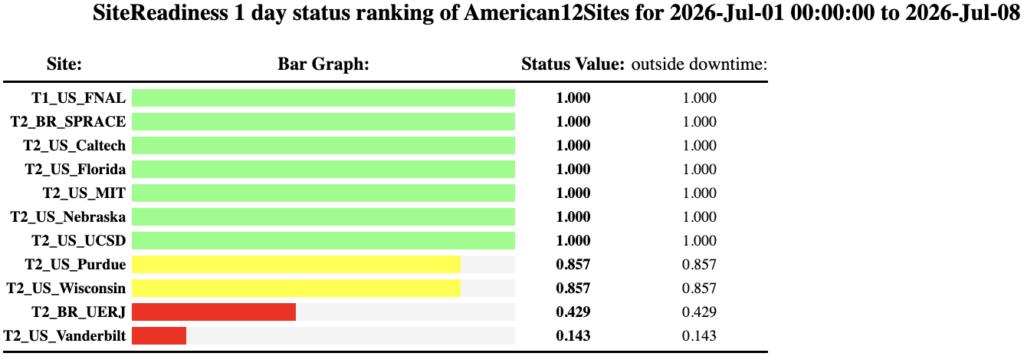
SiteReadiness: 100.0%
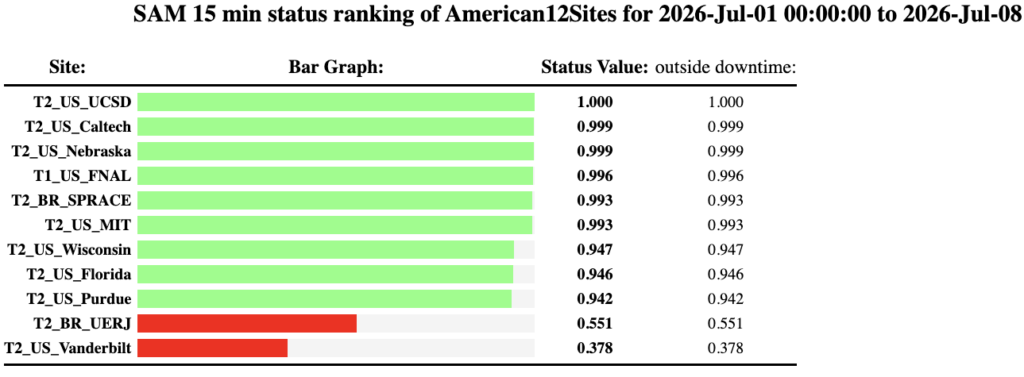
SAM tests: 99.3%
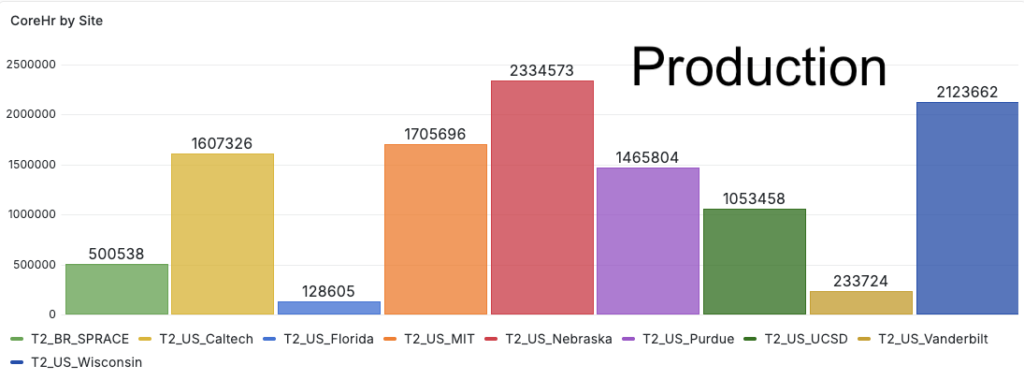
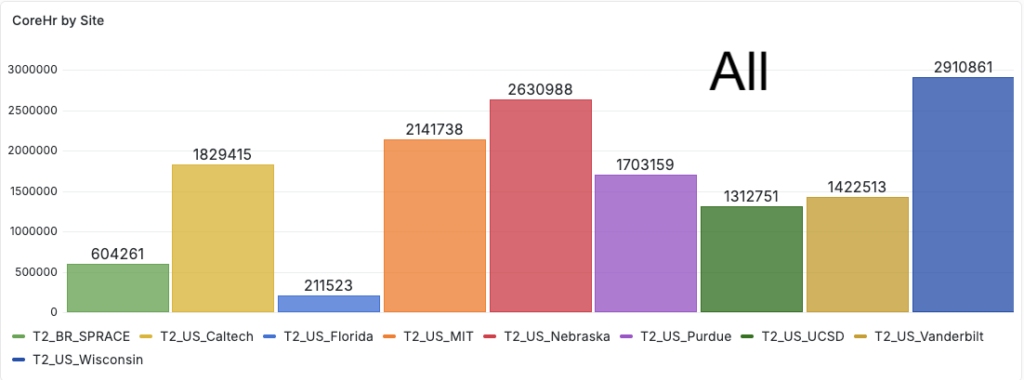
No significant problems over last week. We continue working with CMS submission infrastructure team in order to keep our cores fully busy. For various reasons we continue missing ~2.5K cores, some are down because of power outages, some are in the process of Alma9 installation, and some need OS disk replacement.
Report from June 24, 2026
SiteReadiness: 100.0%
SAM tests: 100.0%
No significant problems over last week. We reverted back to individual host certificates, as a result CMS restriction on certain types of production at our site was lifted. CERN factory started to require token support, as a result one of our CEs lost capability to schedule pilots from CERN; we reconfigured Condor settings to make full use of our cores. For various reasons we continue missing ~2.5K cores, some are down because of power outages, some are in the process of Alma9 installation, and some need OS disk replacement.
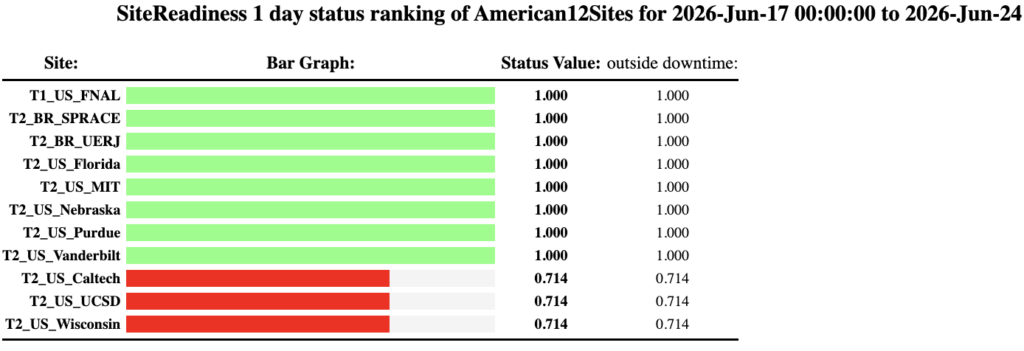
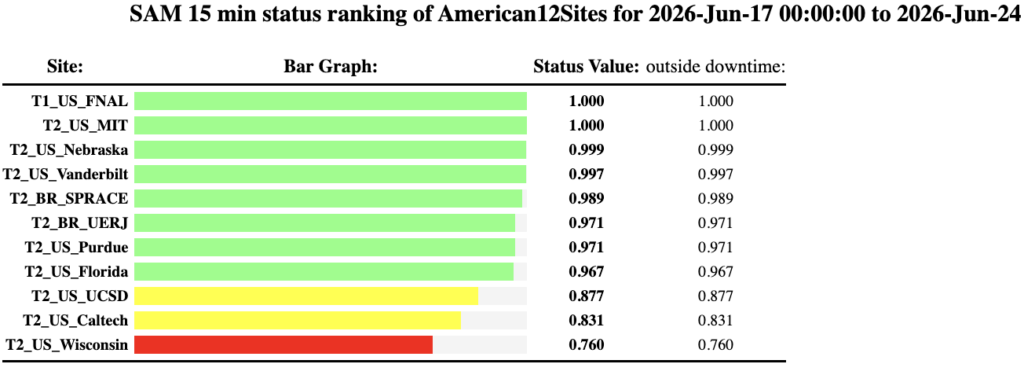
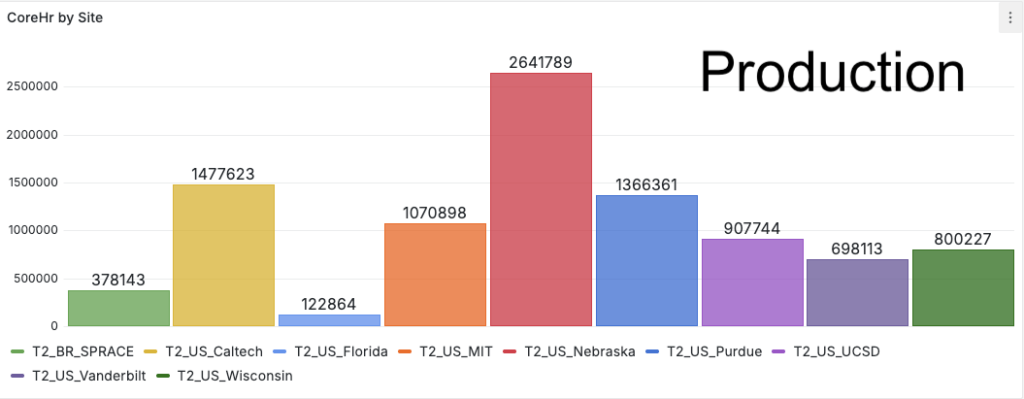
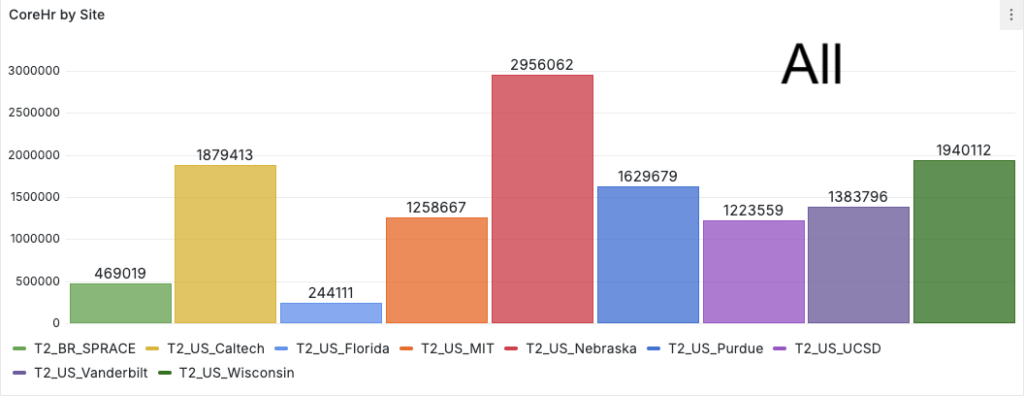
Report from June 17, 2026
SiteReadiness: 100.0%
SAM tests: 98.5%
No significant problems over last week. For various reasons we are temporarily missing ~2.5K cores, some are down because of power outages, some are in the process of Alma9 installation, and some have problematic Alma9 setup. Over the last week we see CMS under-utilizing our site by 2K-3K cores.
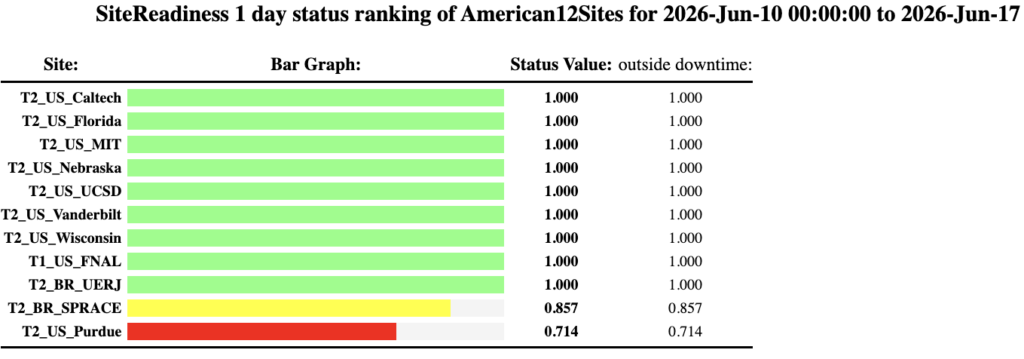
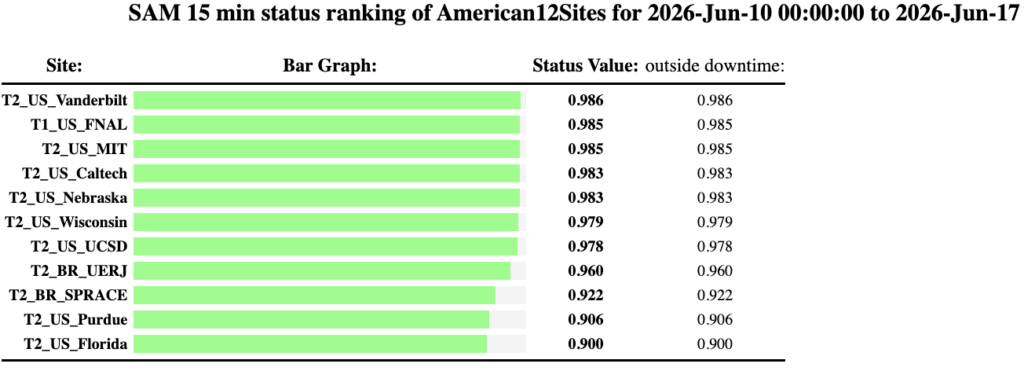
Report from June 10, 2026
SiteReadiness: 100.0%
SAM tests: 99.3%
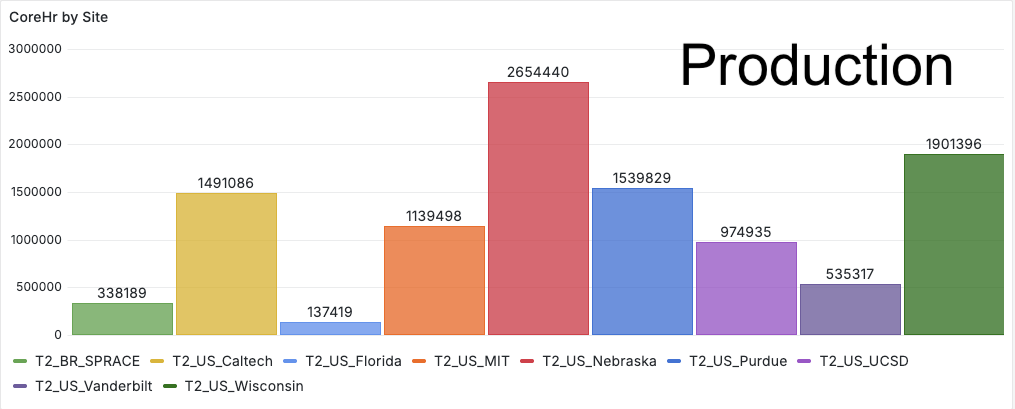
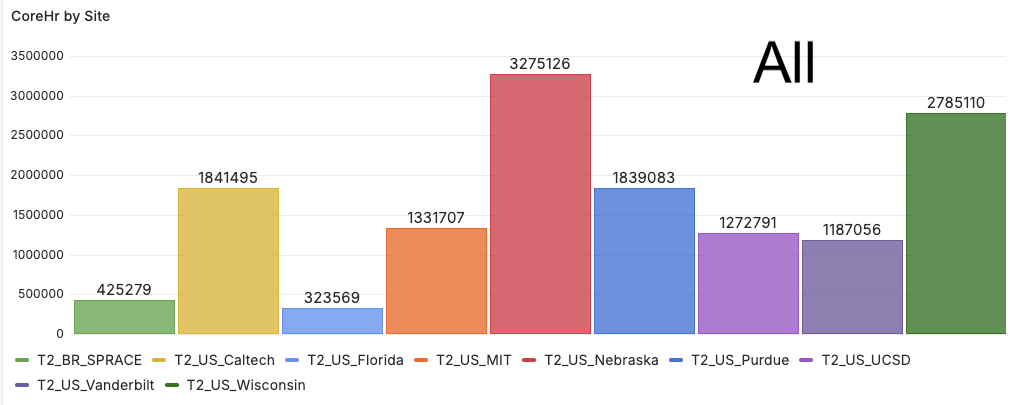
No significant problems over last week. For various reasons we are missing ~3K cores, some are down because of power outage last week, some are in the process of Alma9 installation, and some have problematic Alma9 setup. Additionally, we observe periods with lower than usual CMS jobs pressure.
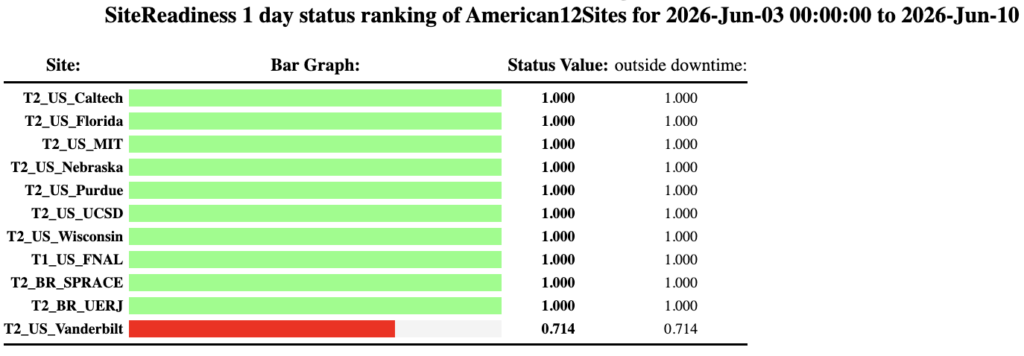
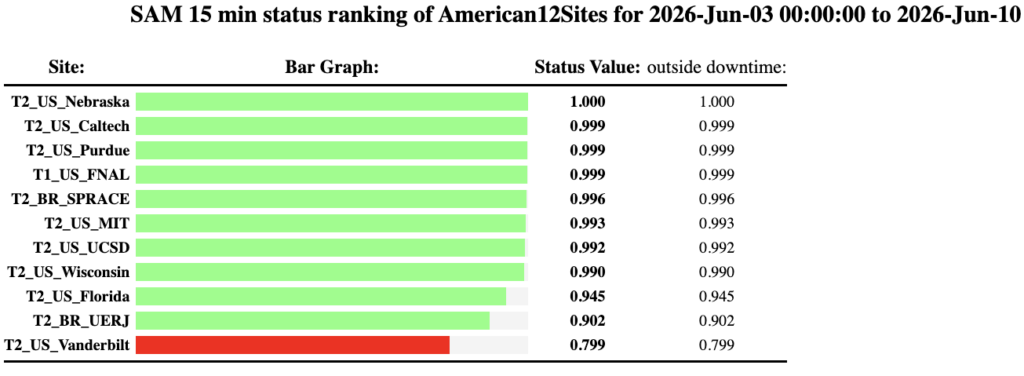
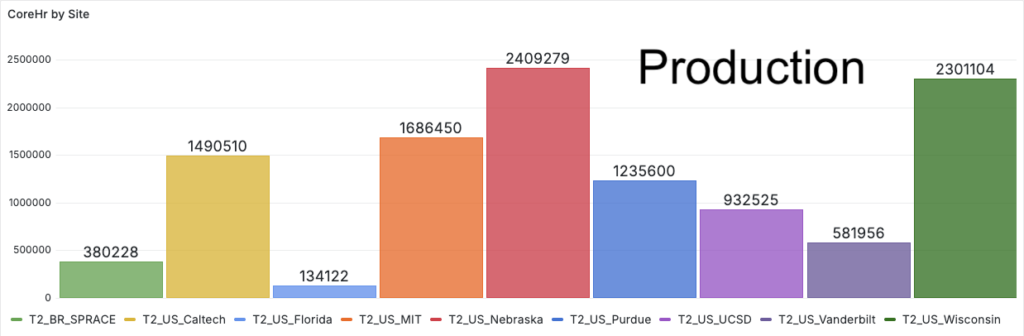
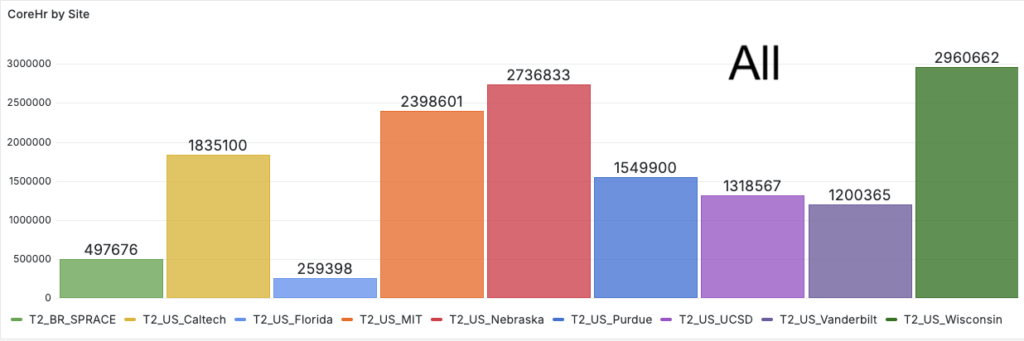
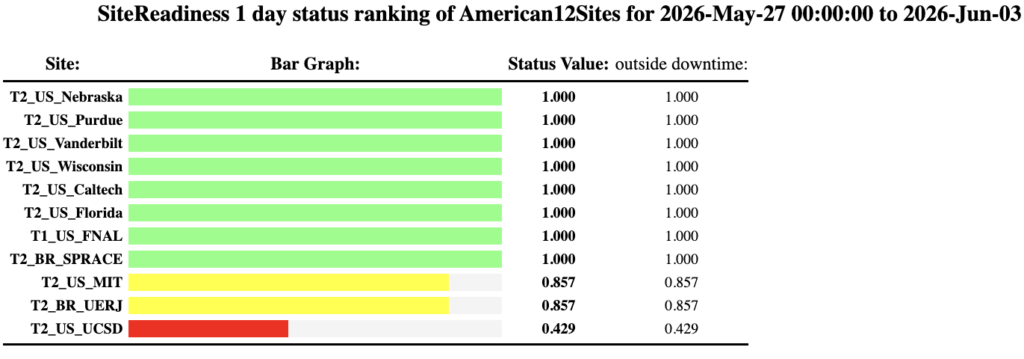
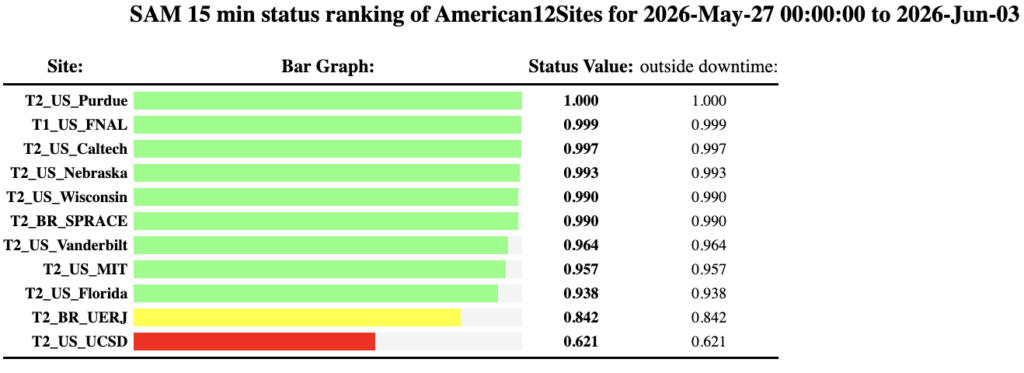
Report from June 3, 2026
SiteReadiness: 85.7%
SAM tests: 95.7%
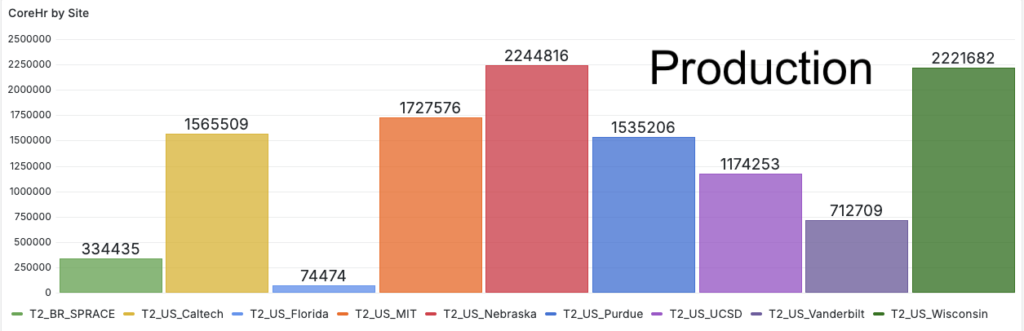
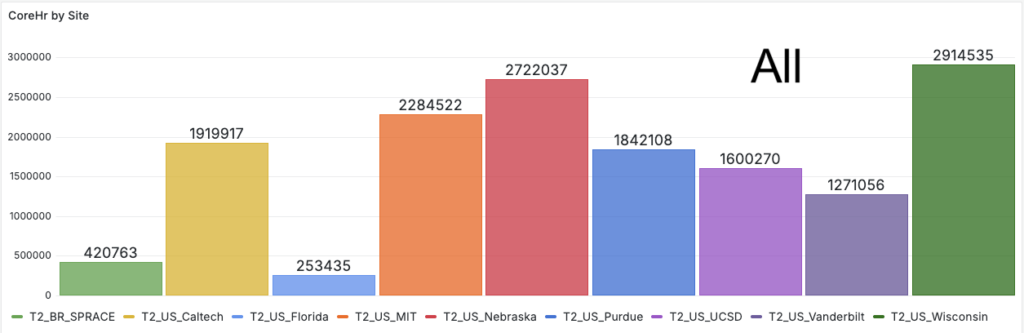
We had one red day in Site Readiness. I tried to fix problems in CephFS and provoked XRootD outage that lasted several hours. We had also two power outages. The first one was partial on May 31st, as a result we lost ~5K cores for ~18 hours. On June 2nd all our worker nodes went down for short period of time.
Report from May 27, 2026
SiteReadiness: 100.0%
SAM tests: 100.0%
Smooth running over the last week. Nothing outstanding to report.
Report from May 20, 2026
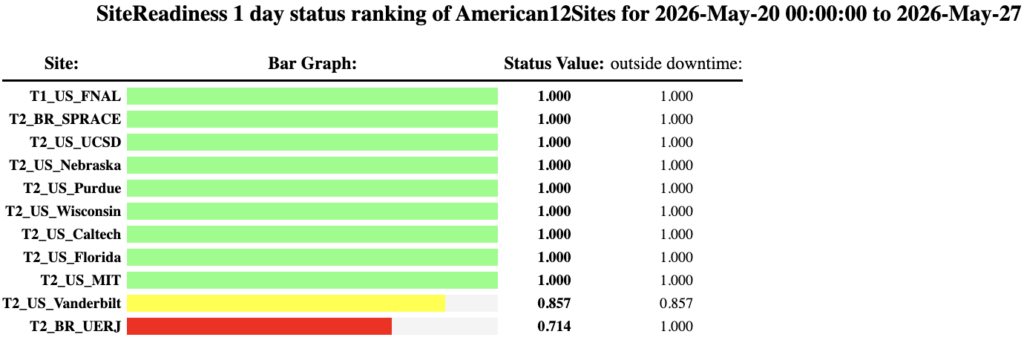
SiteReadiness: 100.0%
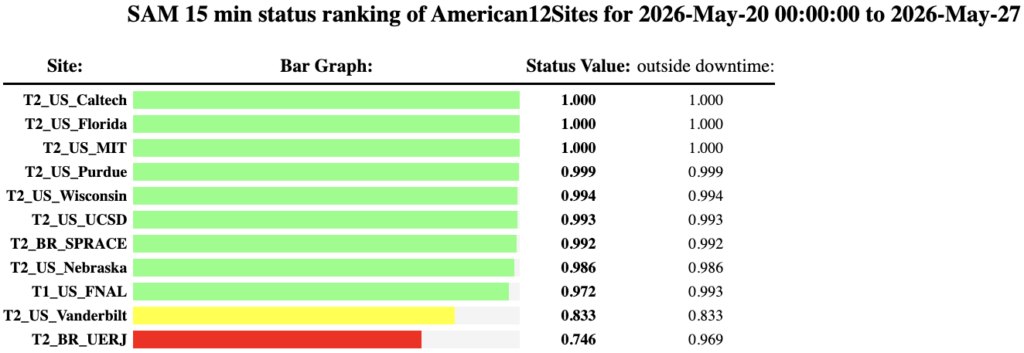
SAM tests: 97.6%
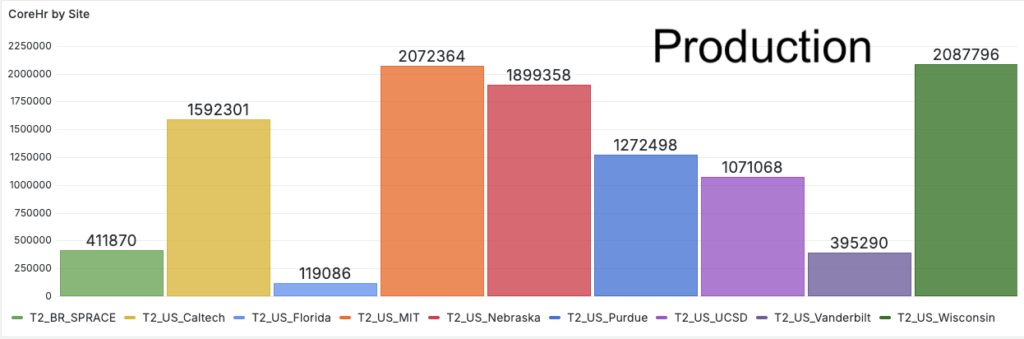
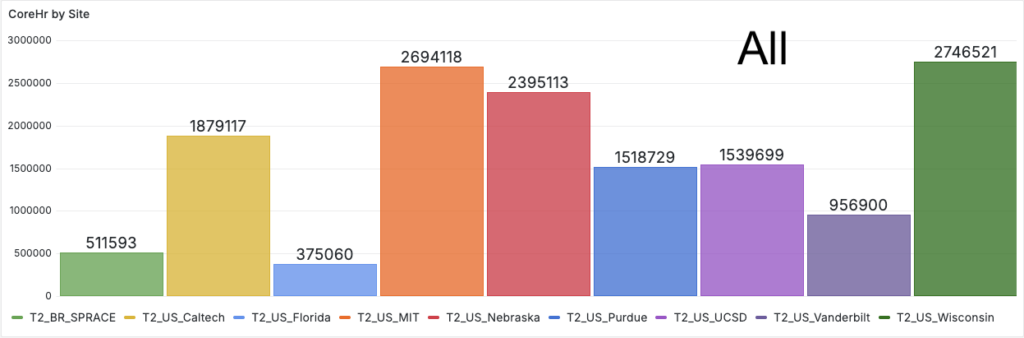
Normal operations during the last week. On Friday our XRootD was overloaded with requests, not clear what specific CMS activity was causing it. We continue using host certificate with a wildcard.
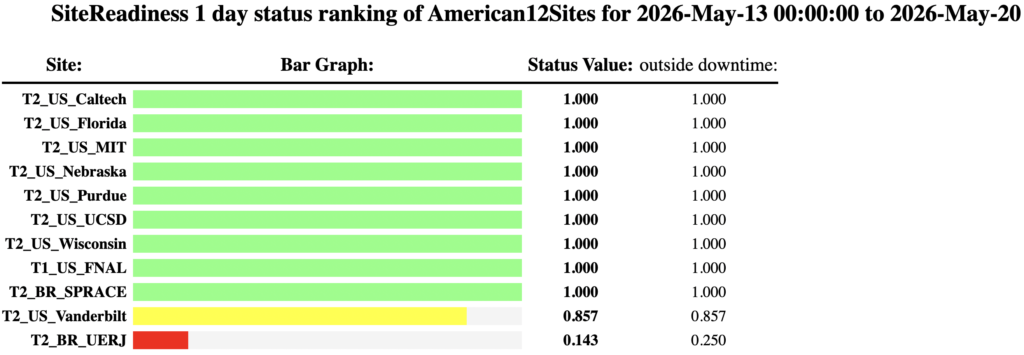
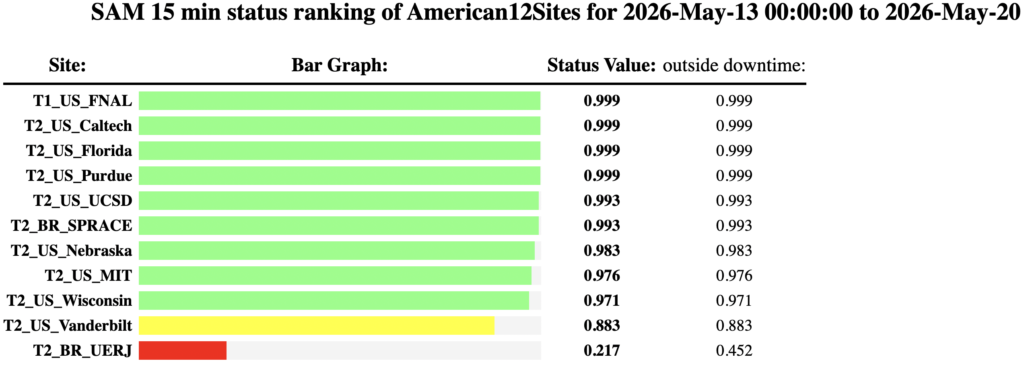
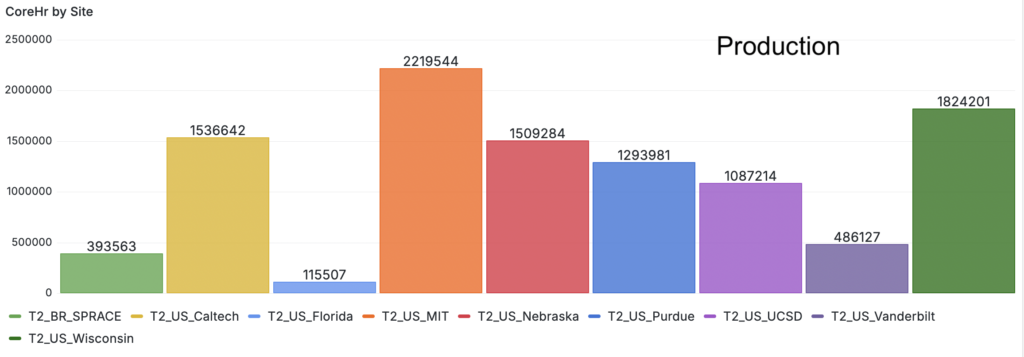
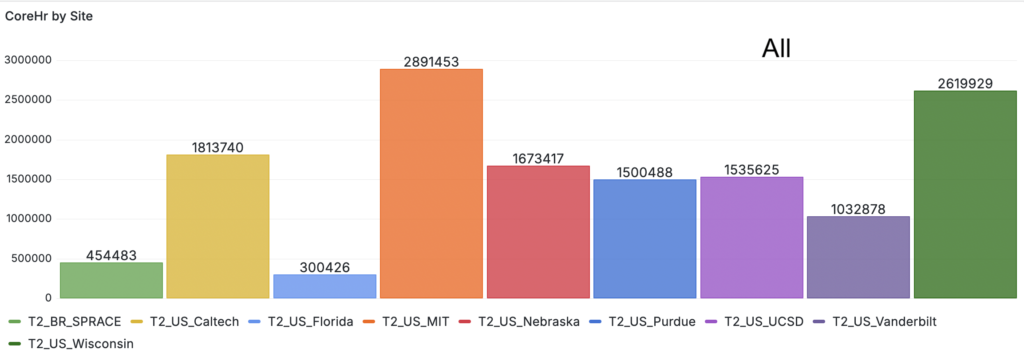
Report from May 13, 2026
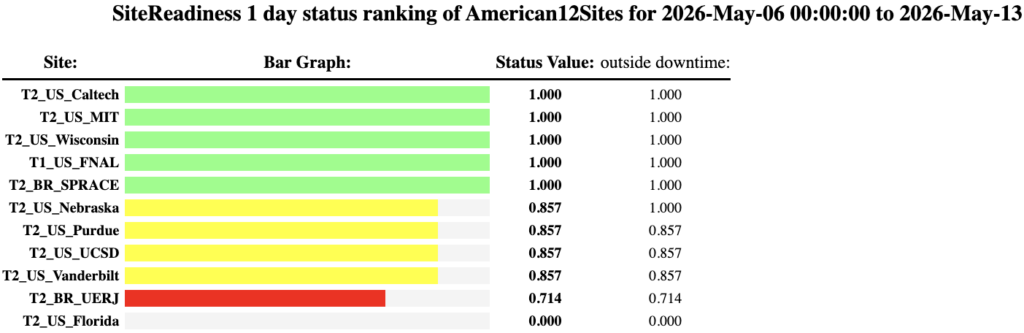
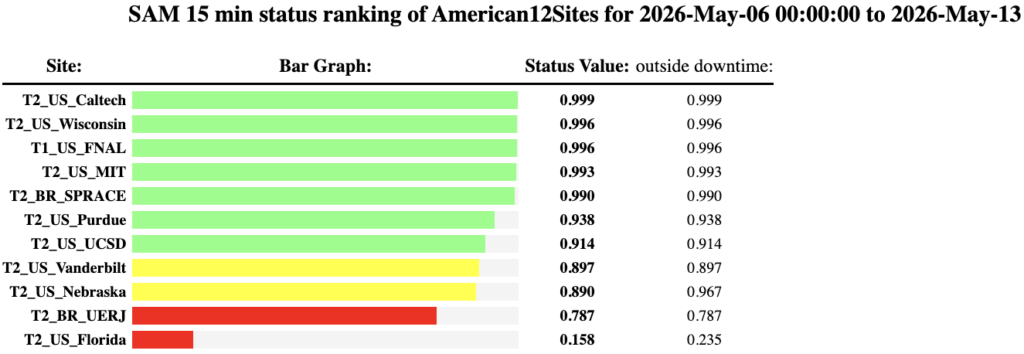
SiteReadiness: 100.0%
SAM tests: 99.3%
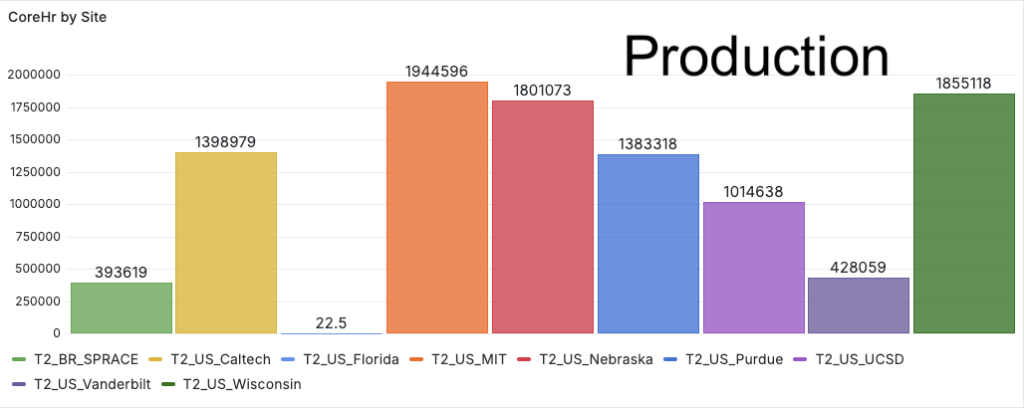
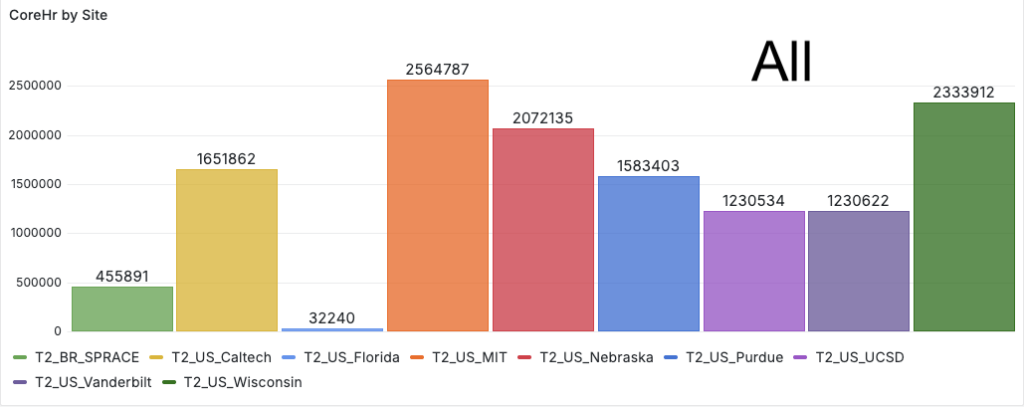
Normal operations during the last week. Started to use a host certificate with a wildcard; this means that cmssw version 9 and lower will not work when exchanging data with our site.
Report from Apr 29, 2026
SiteReadiness: 100.0%
SAM tests: 99.0%
Normal operations during the last week. Planning to test host certificate with a wildcard.
Report from Apr 22, 2026
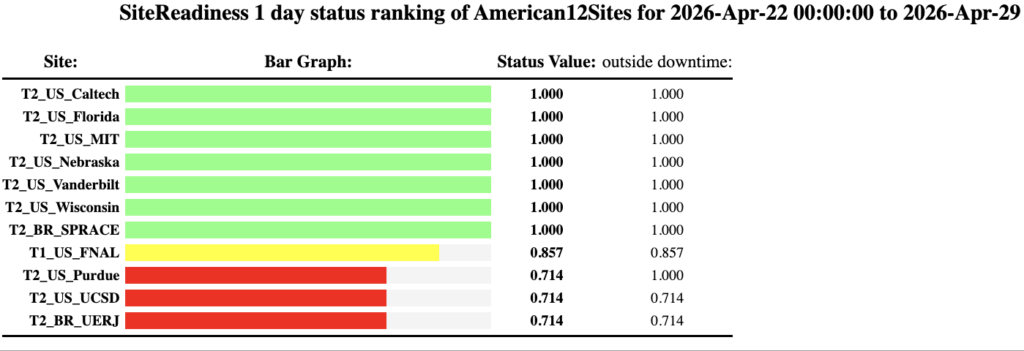
SiteReadiness: 100.0%
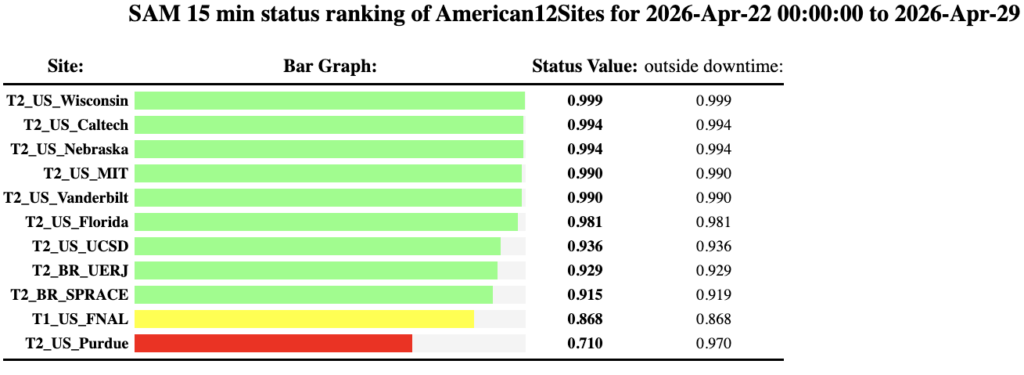
SAM tests: 98.5%
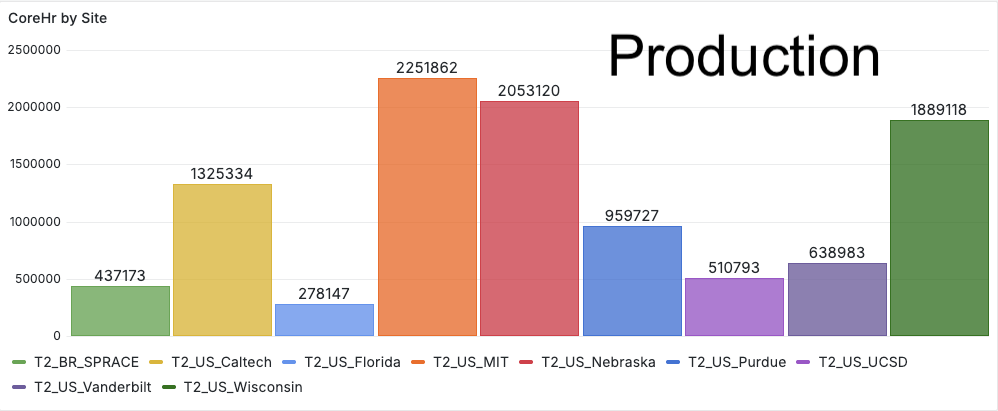
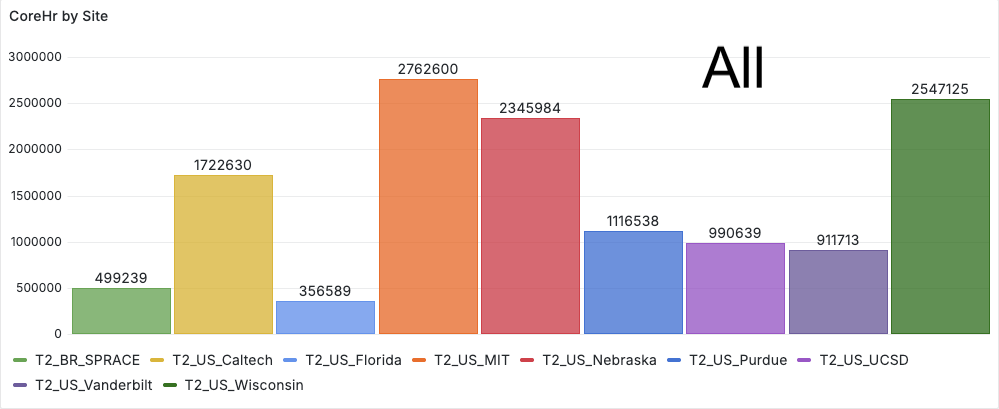
Normal operations during the last week. We were asked to reduce frequency of squid restarts and upgrade them to a newer version.
Report from Apr 15, 2026
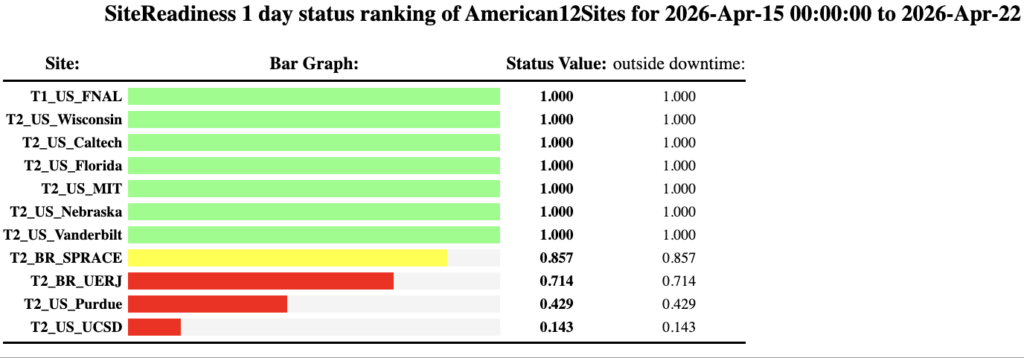
SiteReadiness: 100.0%
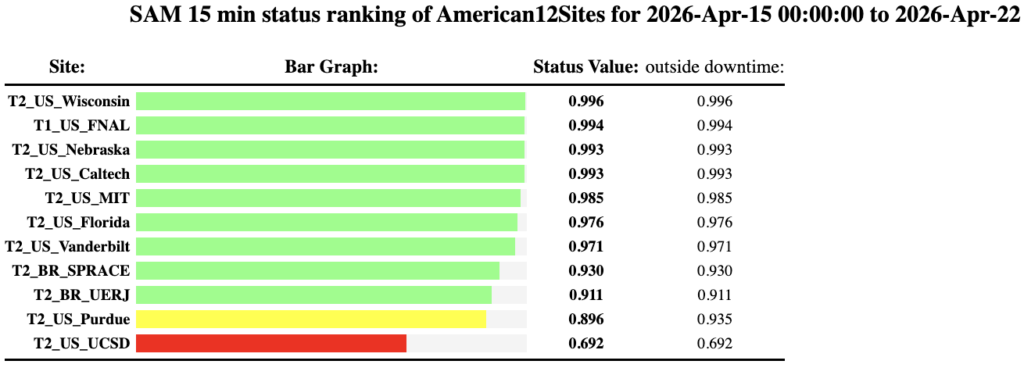
SAM tests: 96.2%
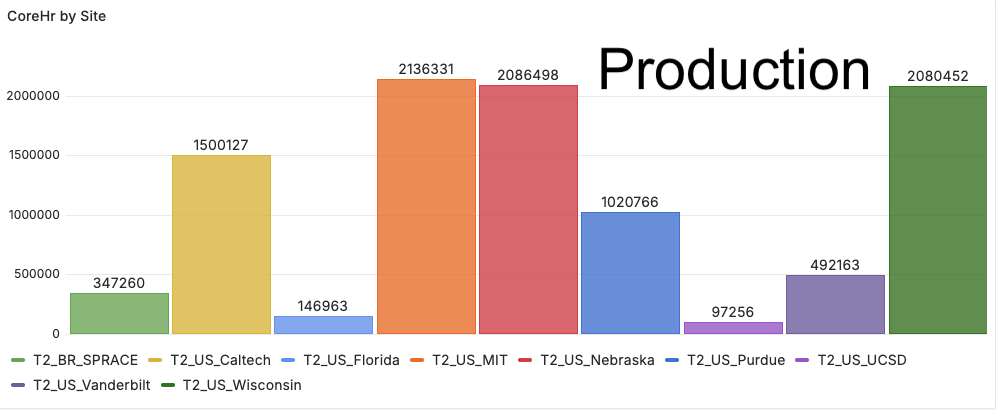
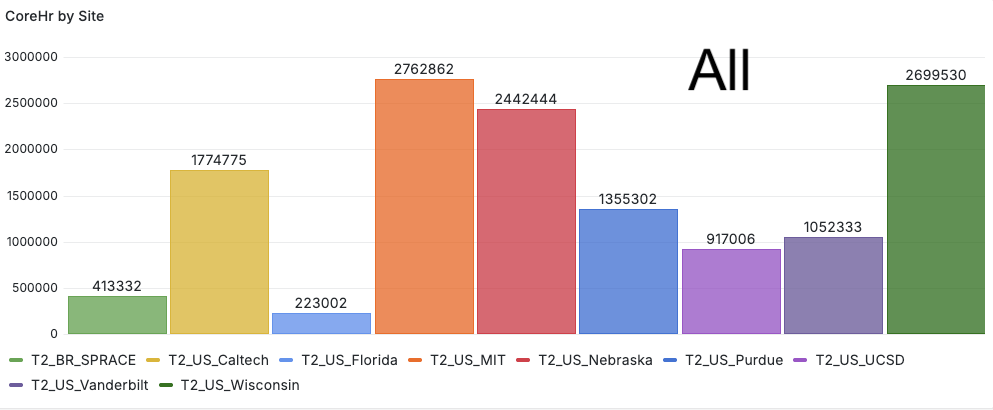
Normal operations during the last week.
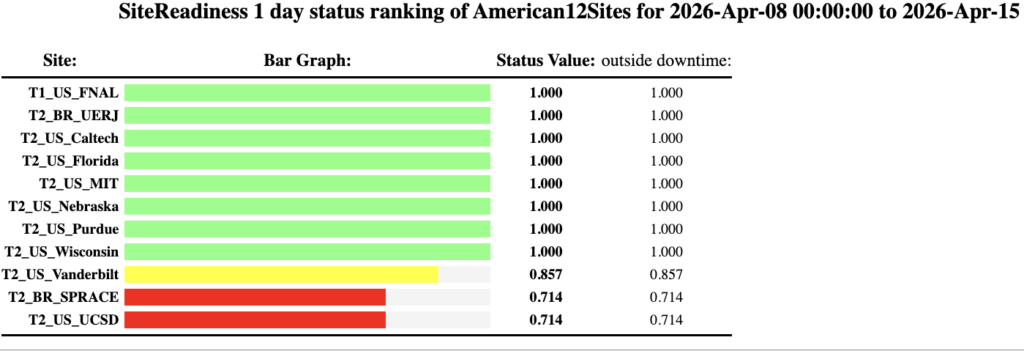
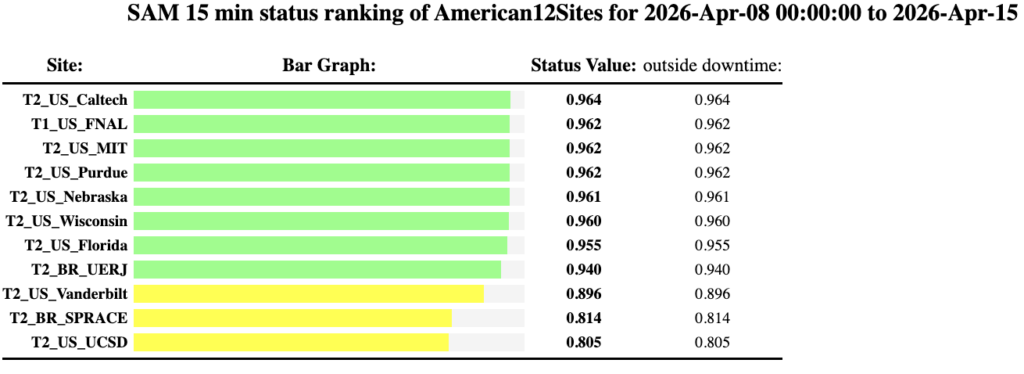
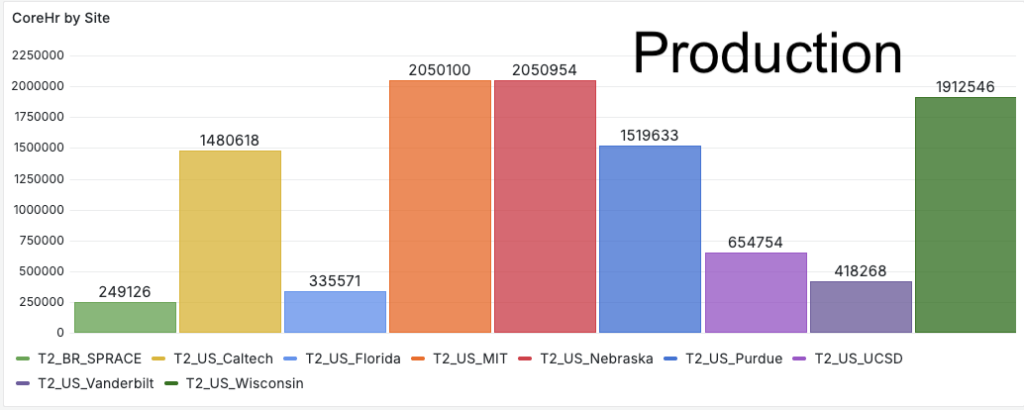
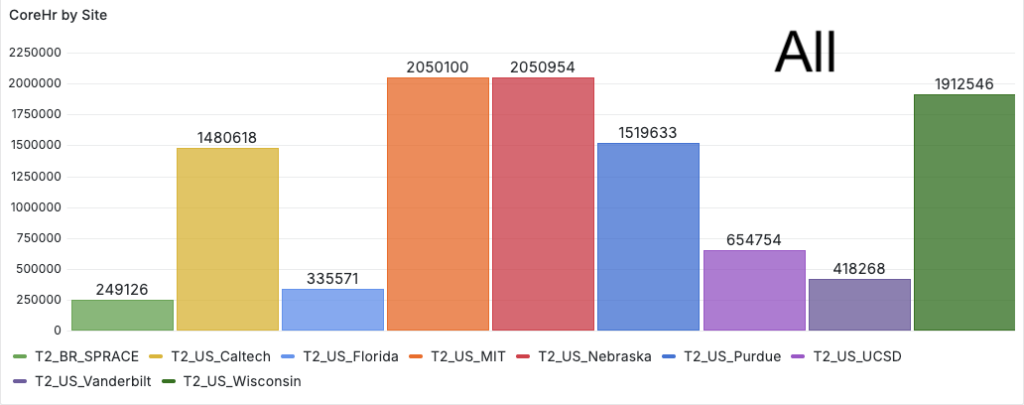
Report from Apr 8, 2026
SiteReadiness: 100.0%
SAM tests: 98.5%
Significant portion of cores were taken for Tier0 activities. It looks like reading data remotely from CERN like it is done now under-utilizes CPUs and puts pressure on XrooTD to the point that the servers start struggling.
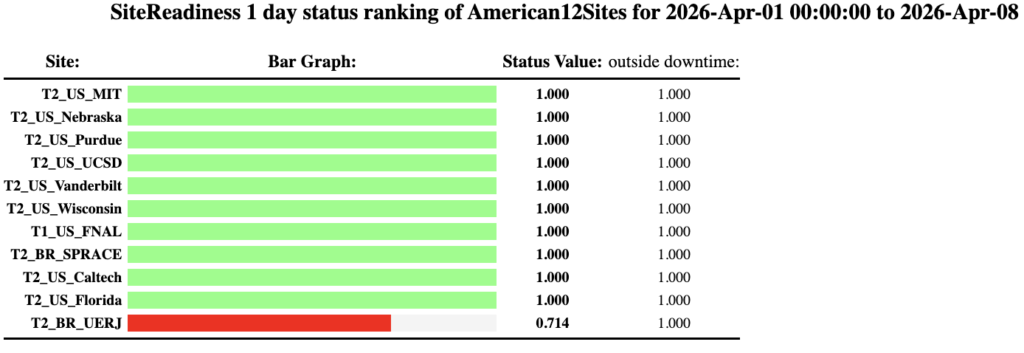
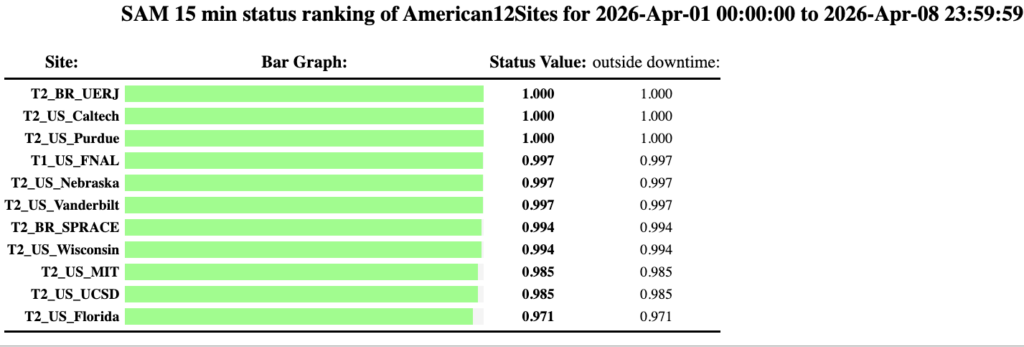
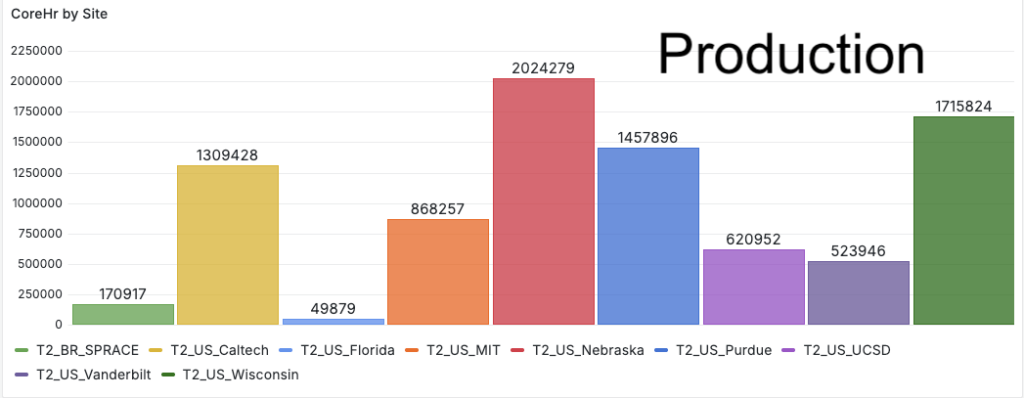
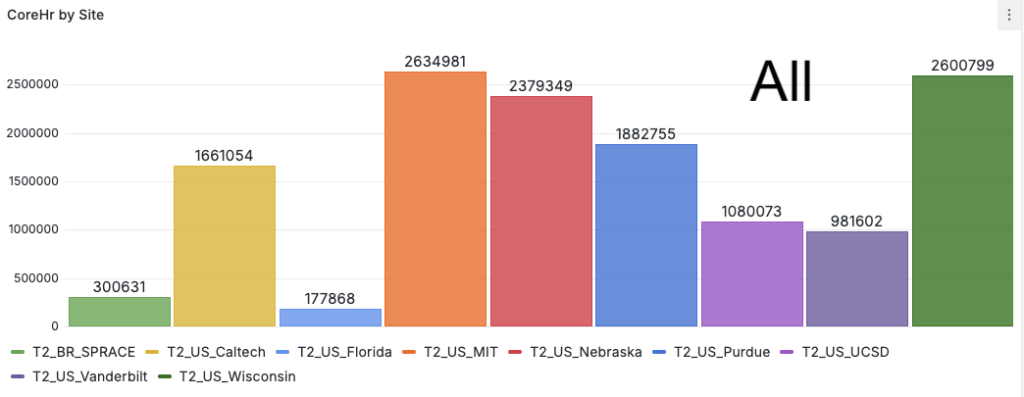
Report from Apr 1, 2026
SiteReadiness: 100.0%
SAM tests: 97.6%
Significant portion of cores were taken for Tier0 activities. It looks like reading data remotely from CERN like it is done now under-utilizes CPUs and puts pressure on XrooTD to the point that the servers start struggling.
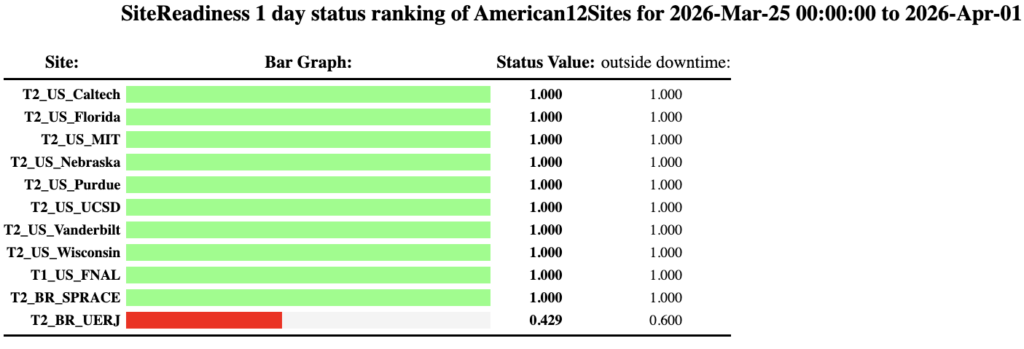
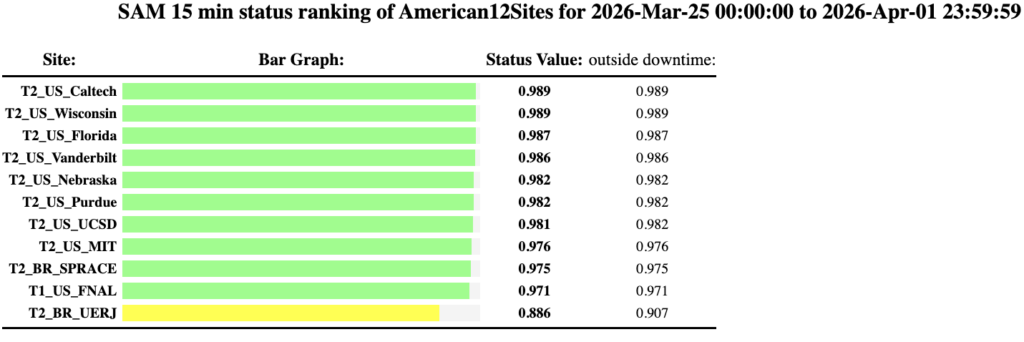
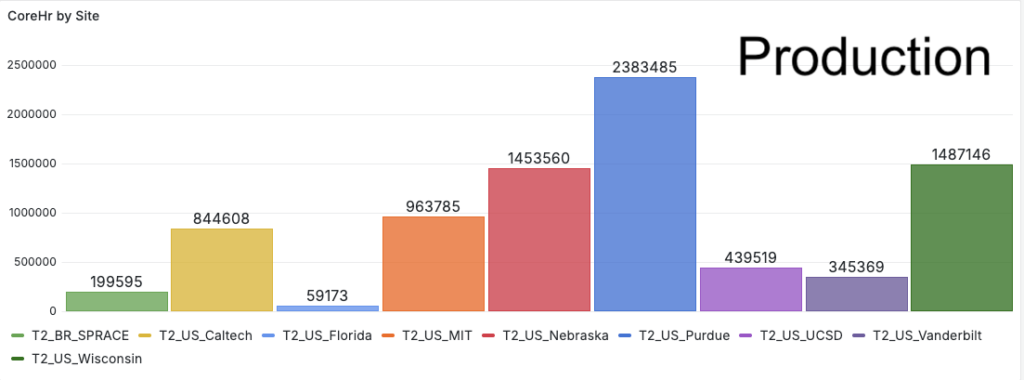
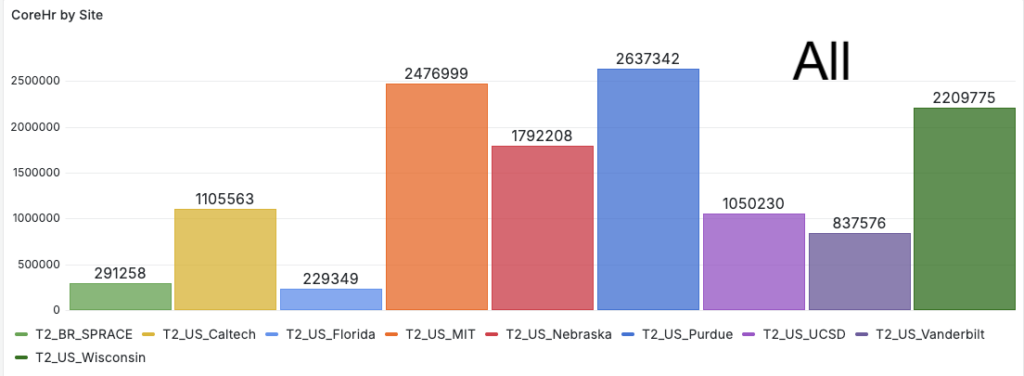
Report from Mar 25, 2026
SiteReadiness: 100.0%
SAM tests: 99.3%
Nothing special to report.
Report from Mar 18, 2026
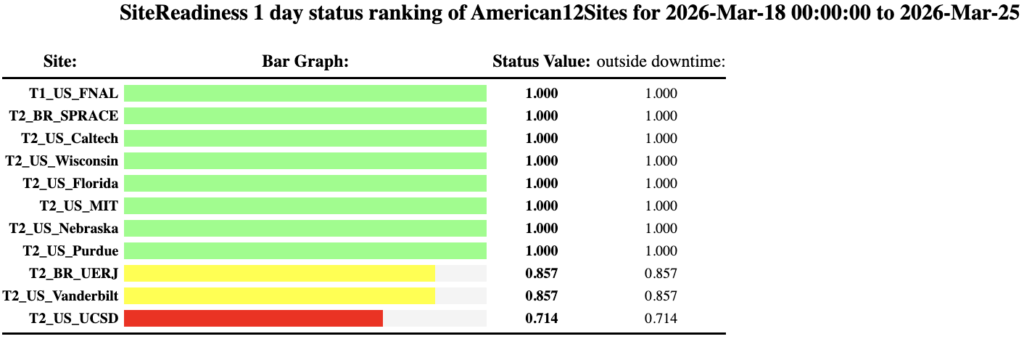
SiteReadiness: 100.0%
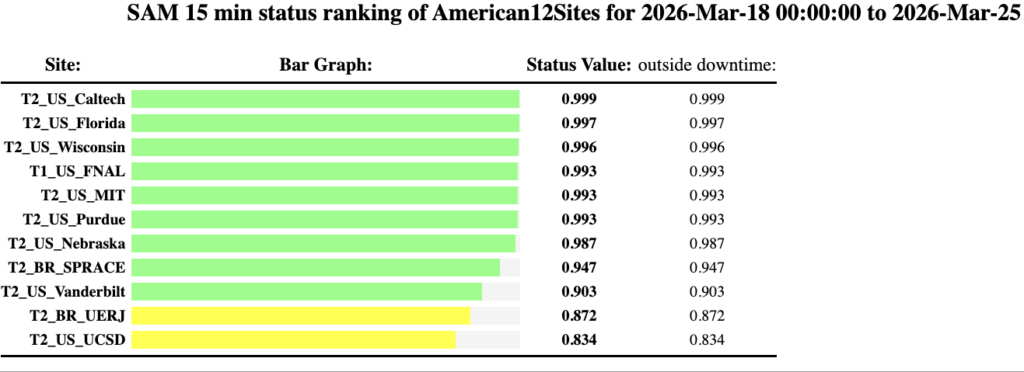
SAM tests: 99.7%
Quiet and smooth week.
Report from Mar 11, 2026
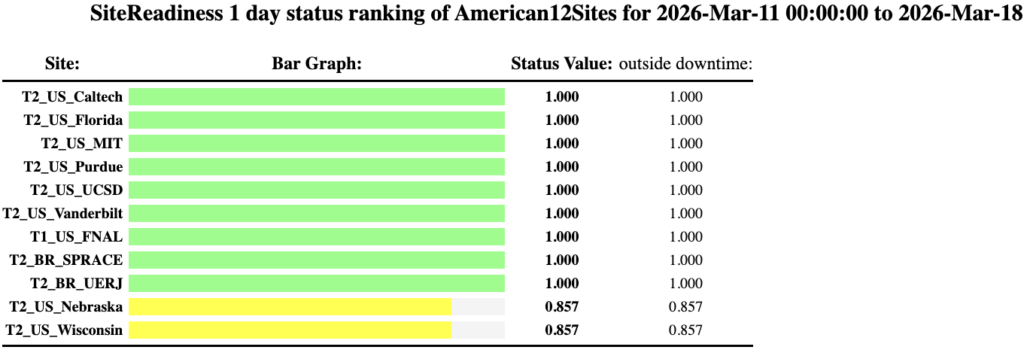
SiteReadiness: 100.0%
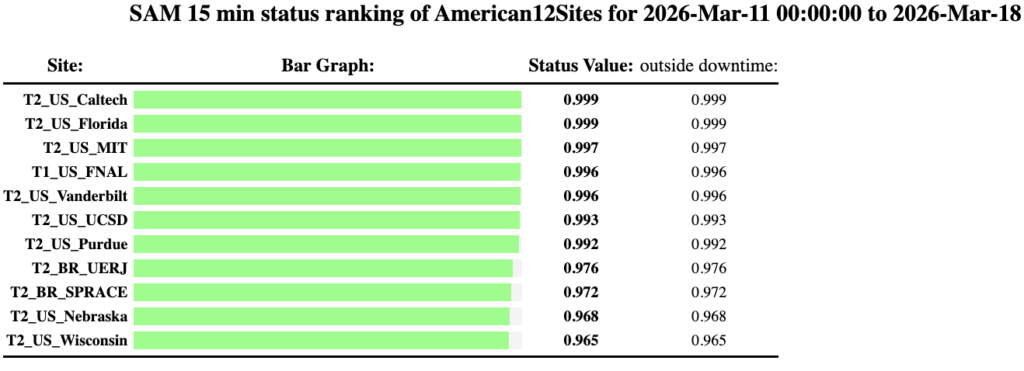
SAM tests: 95.0%
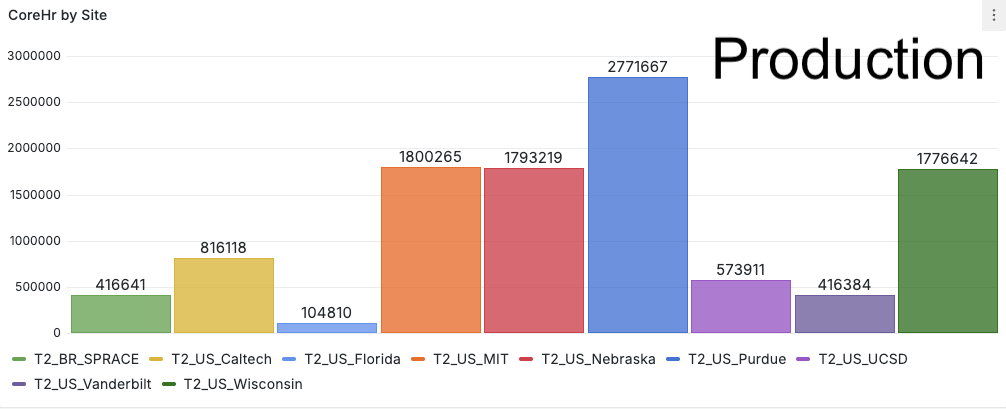
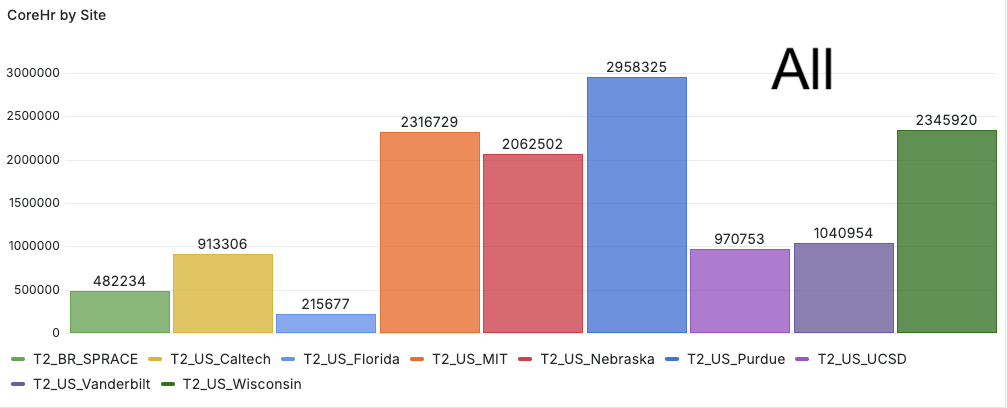
We did not have any problems over the last week. The only item worth mentioning is that we periodically do not get enough pilots on one of our CEs; as a result we have ~1K cores sitting idle.
Report from Mar 04, 2026
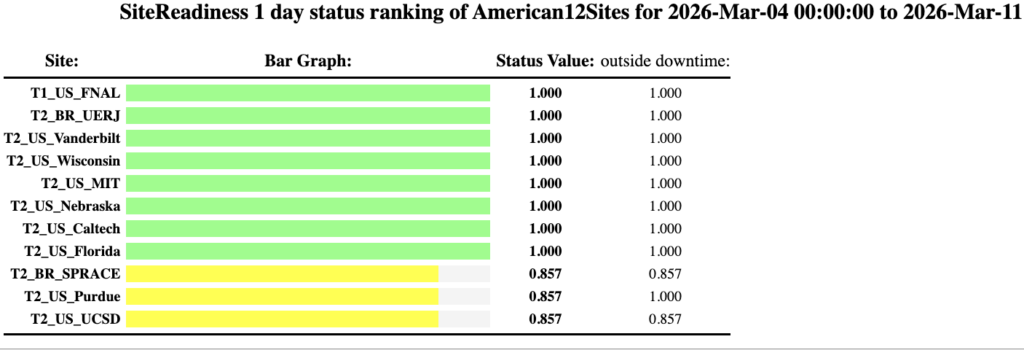
SiteReadiness: 100.0%
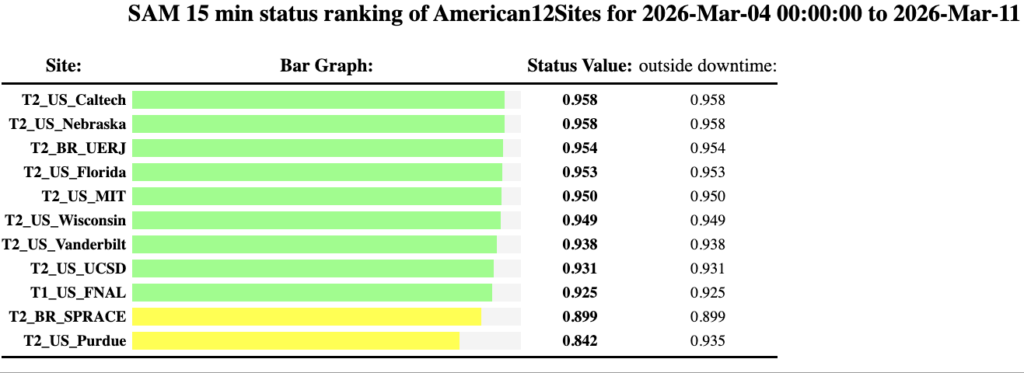
SAM tests: 98.6%
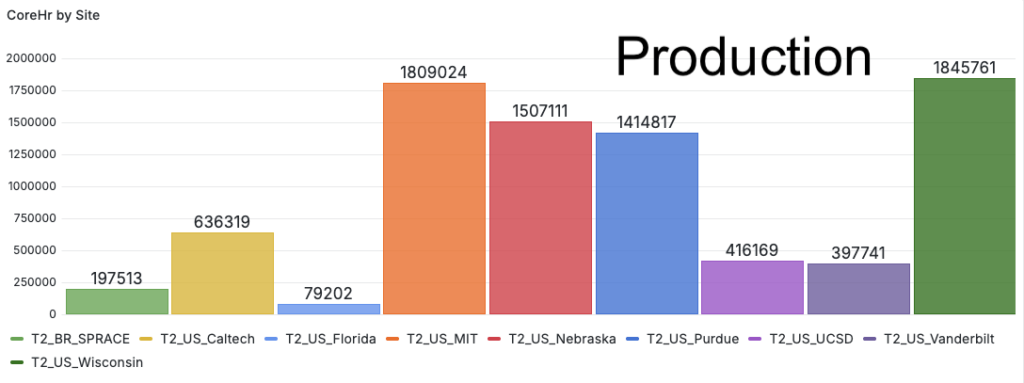
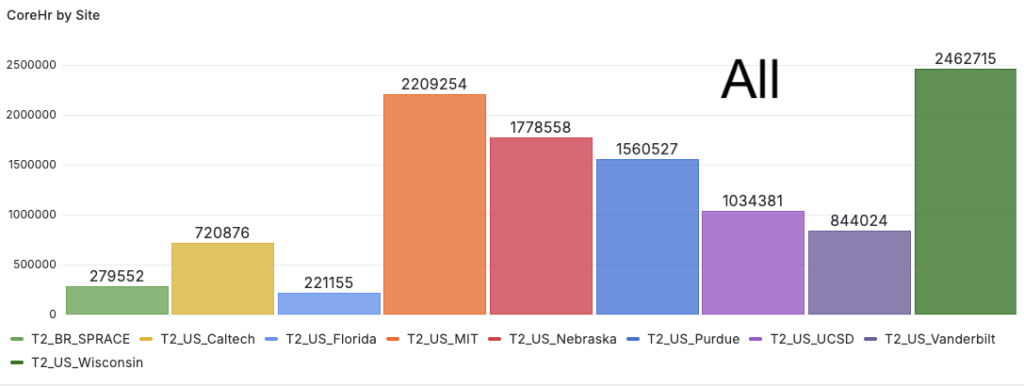
We did not have any problems over the last week. We initiated the process of buying hardware with 2025 funds.
Report from Feb 25, 2026
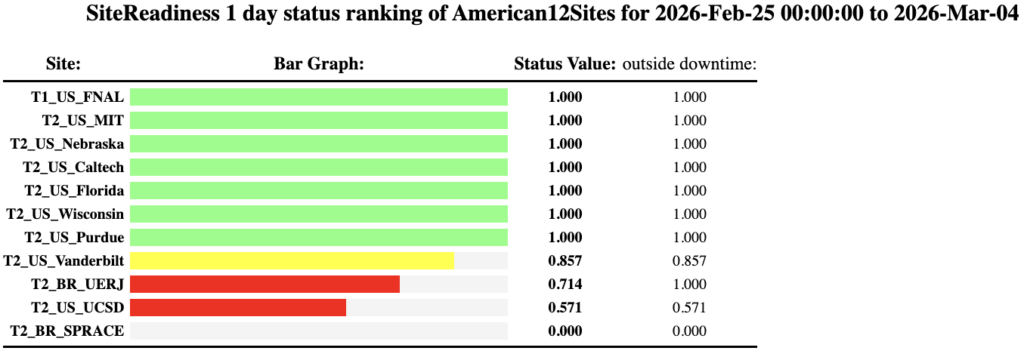
SiteReadiness: 100.0%
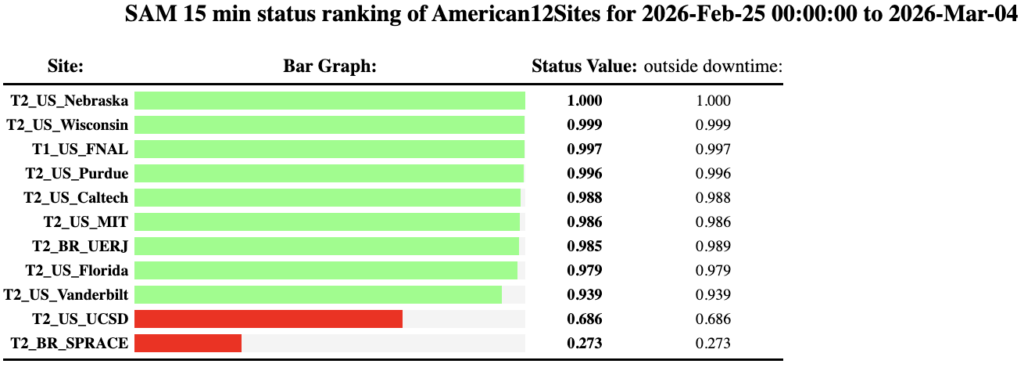
SAM tests: 99.7%
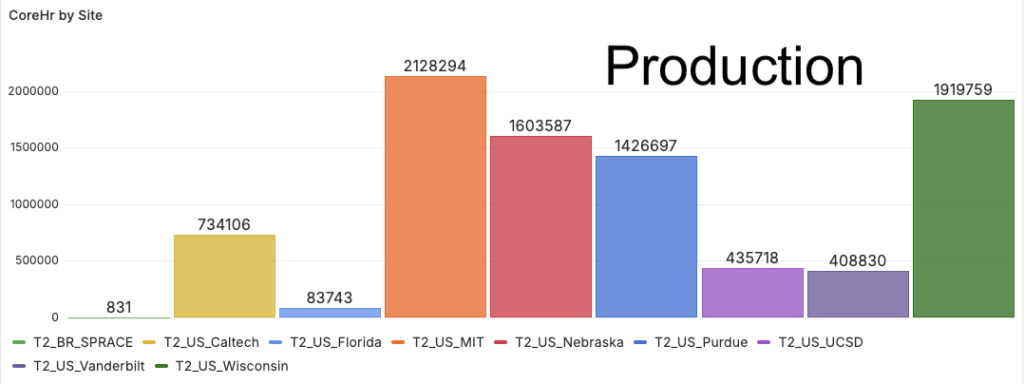
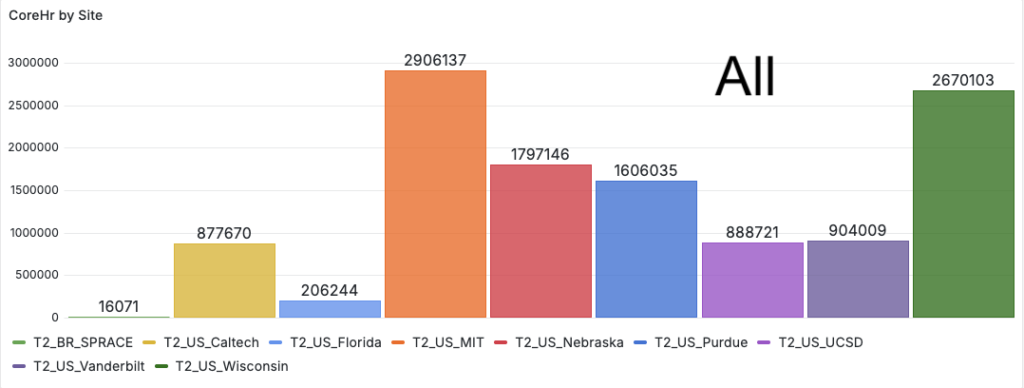
We did not have any problems over the last week. CMS job load went up after contacting submission infrastructure team; we do not have any cores idling any longer.
Report from Feb 18, 2026
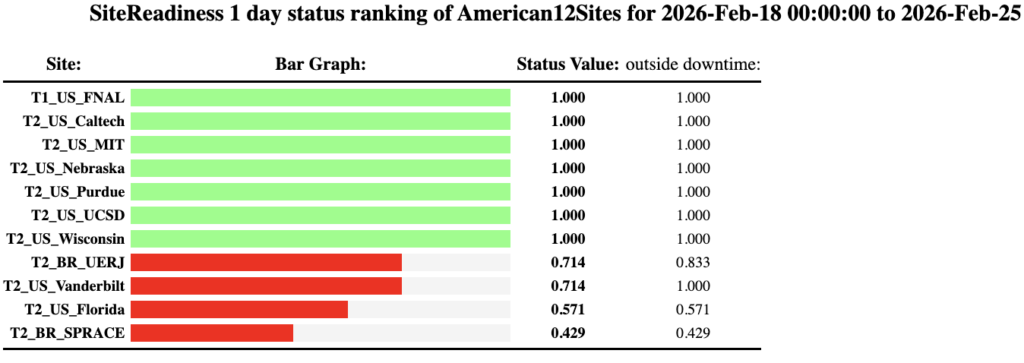
SiteReadiness: 100.0%
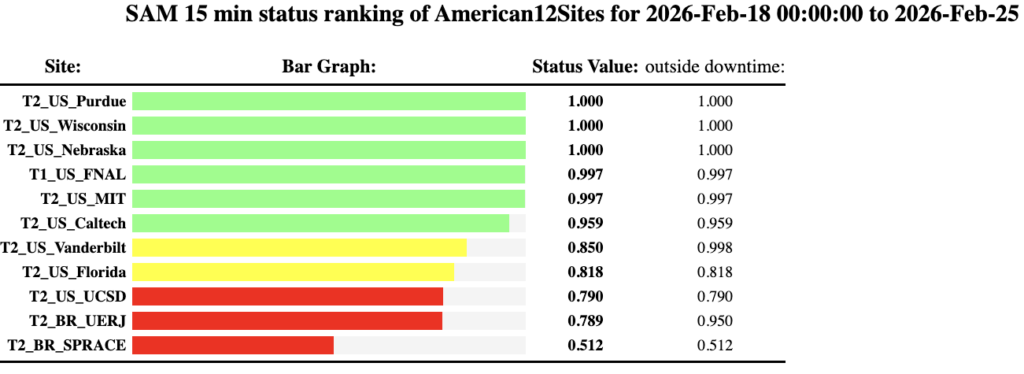
SAM tests: 100.0%
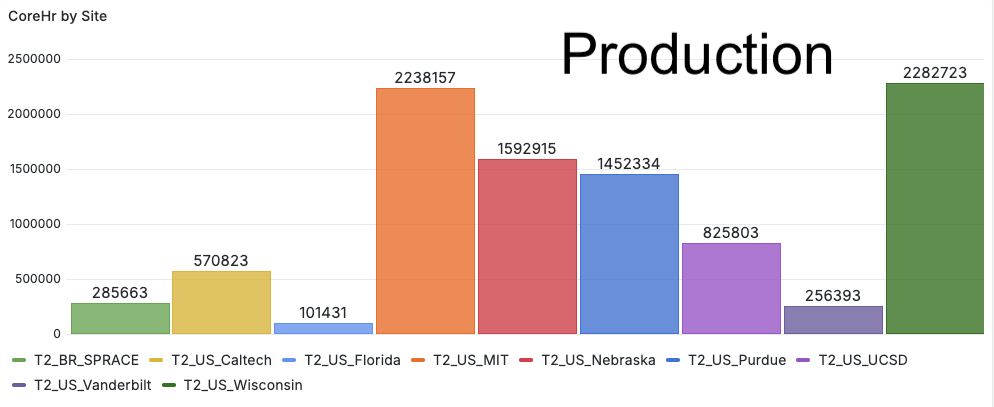
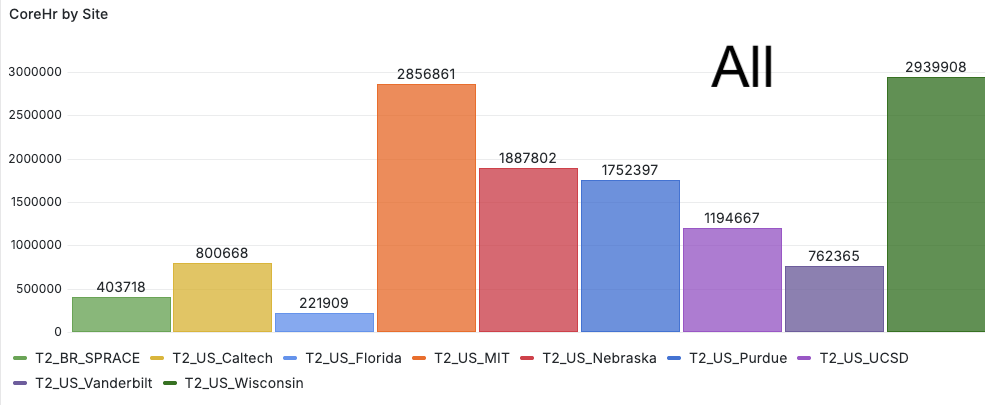
We did not have any problems over the last week. However, there are not many jobs coming from CMS, our site is used at ~50%. We contacted the job factory for an explanation.
Report from Jan 21, 2026
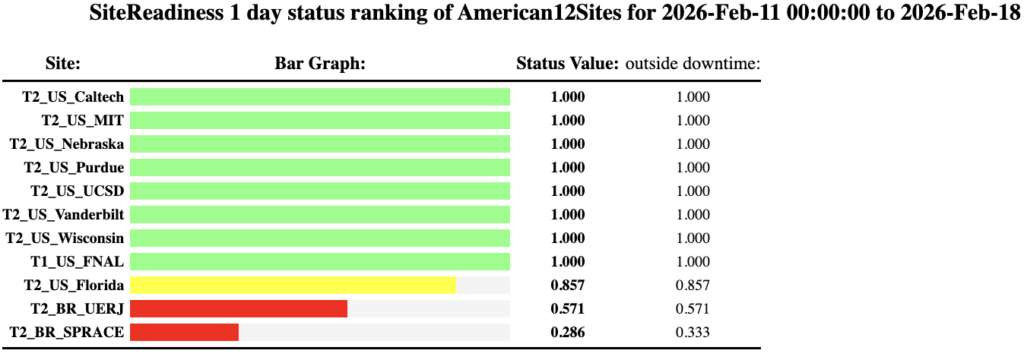
SiteReadiness: 100.0%
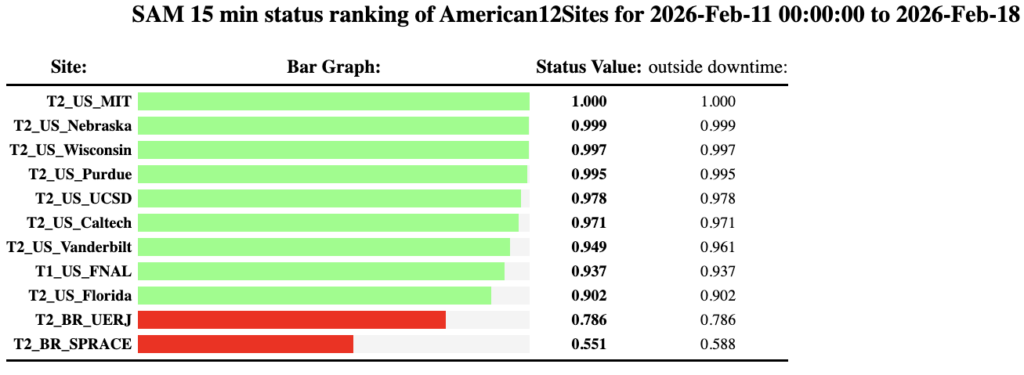
SAM tests: 87.7%
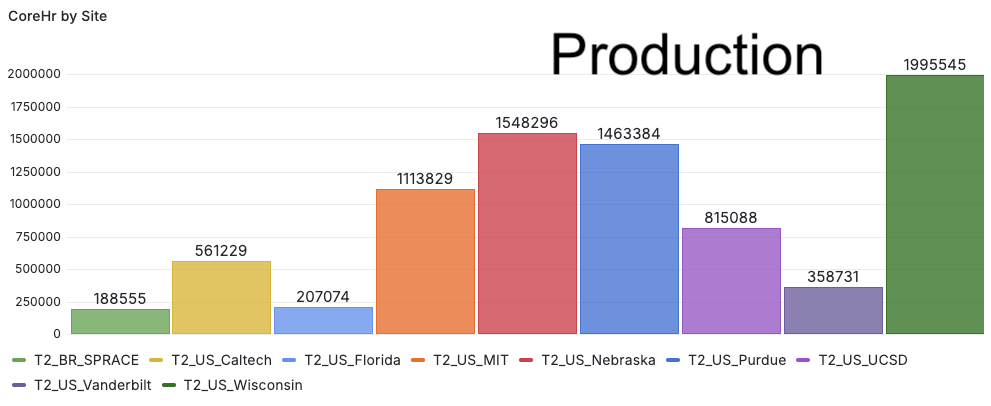
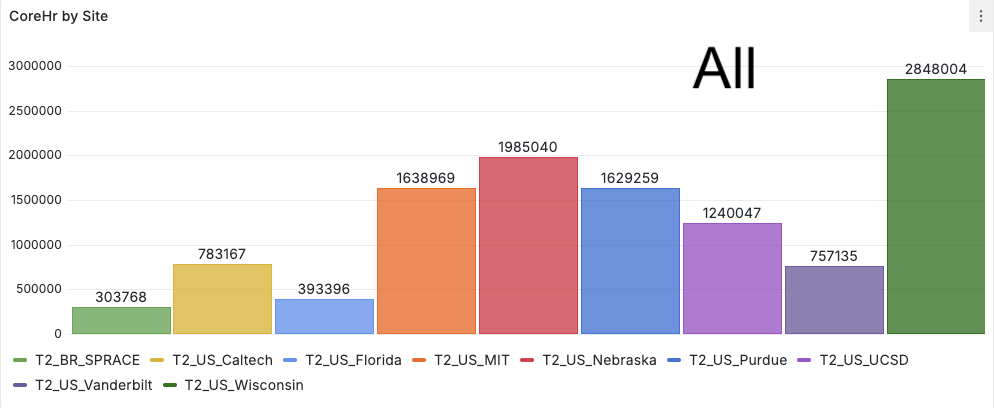
We did not have any problems over last week. I, however, do not understand availability plots.
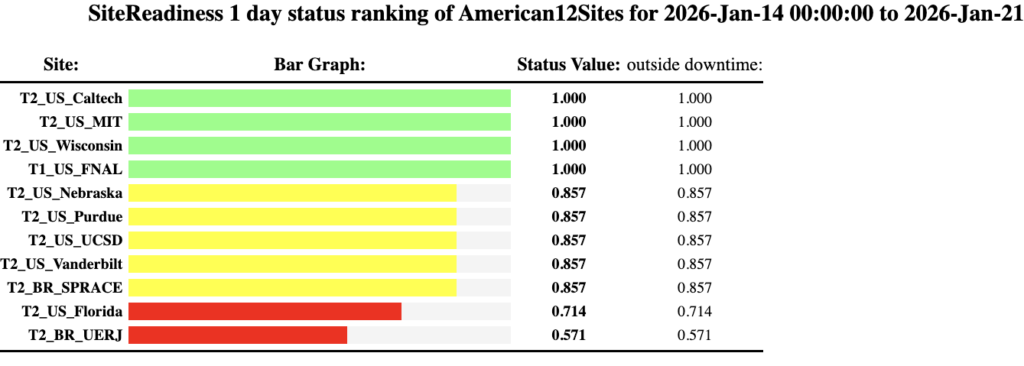
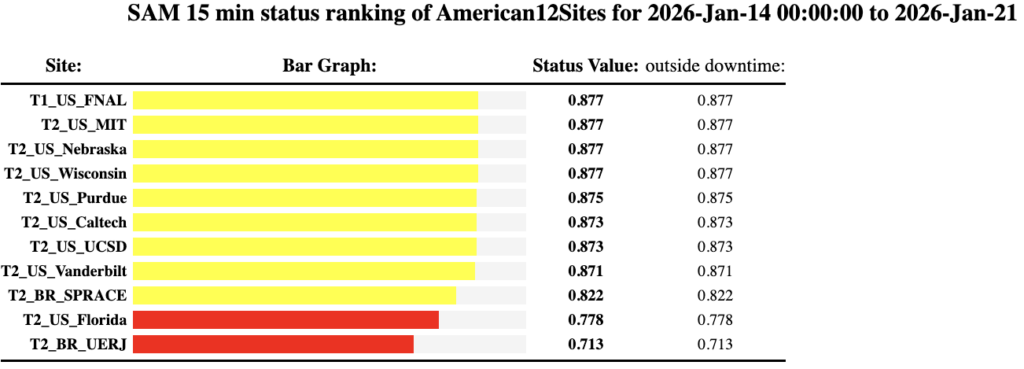
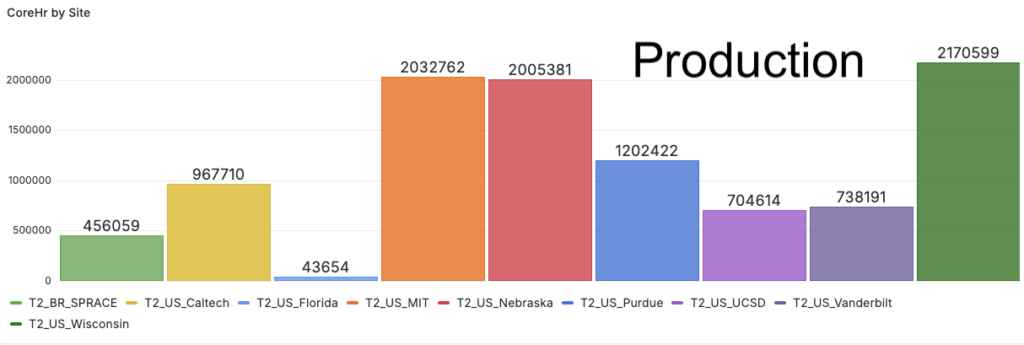
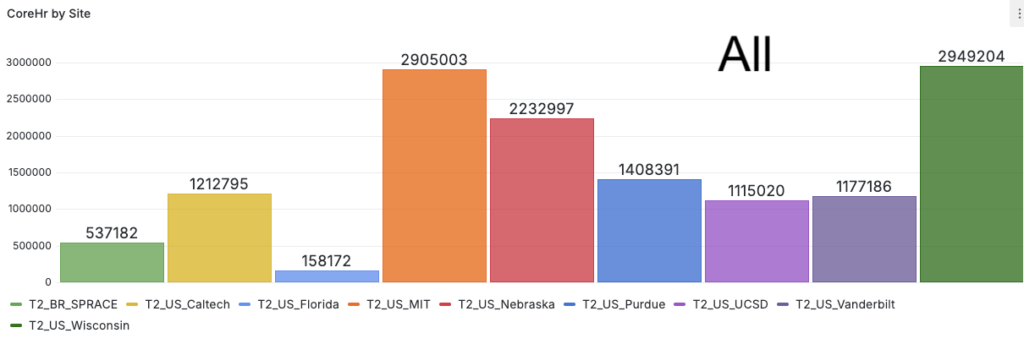
Report from Jan 14, 2026
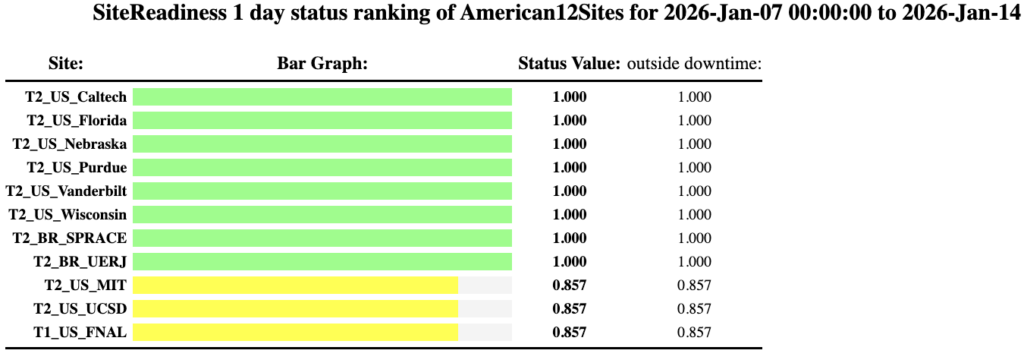
SiteReadiness: 85.7%
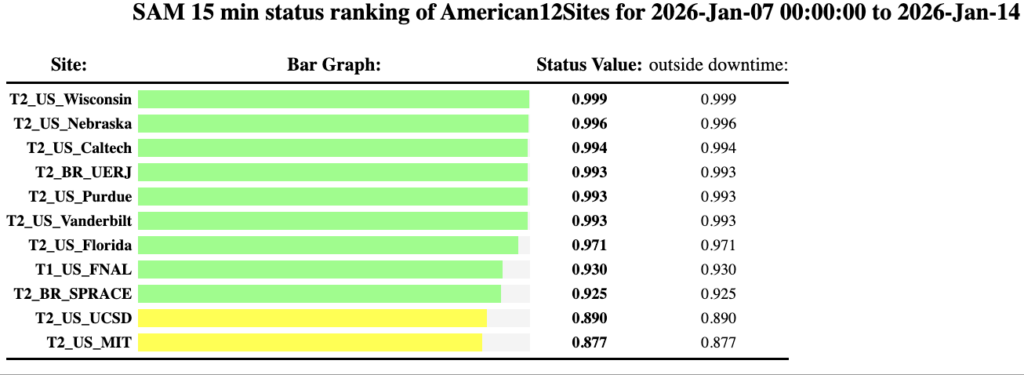
SAM tests: 87.7%
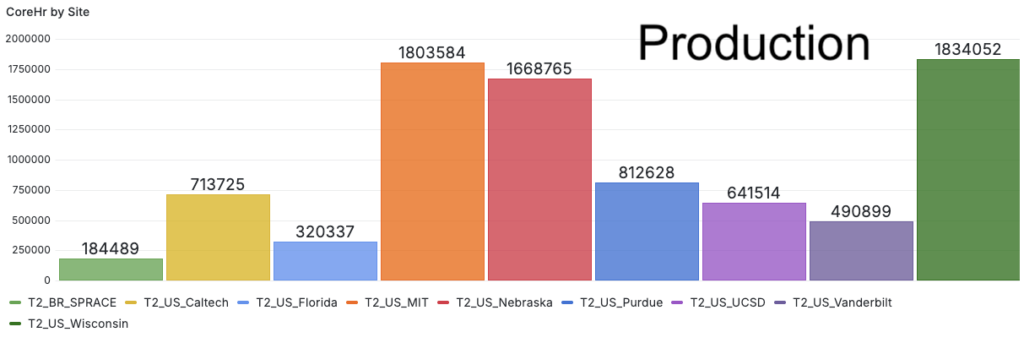
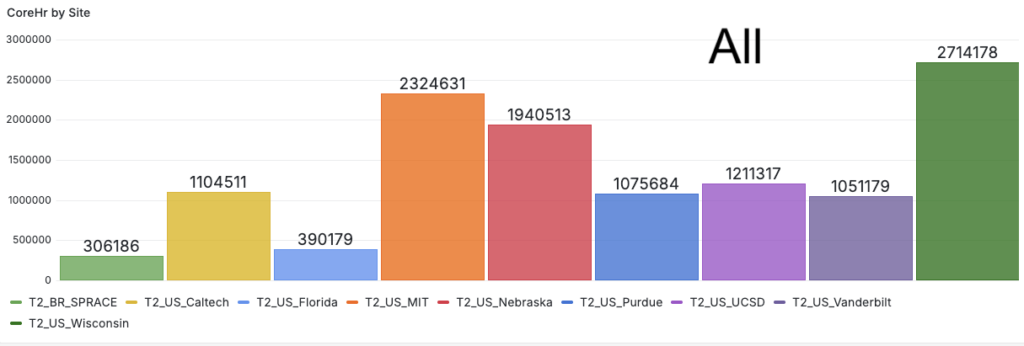
We had 2 days over the last week with significantly reduced availability.
01/09 – Cluster Condor configurations that caused problems for a number of struggling WNs.
01/11 – Network outage that lasted ~16 hours. All connections with the cluster were timing out.
Report from Jan 7, 2026
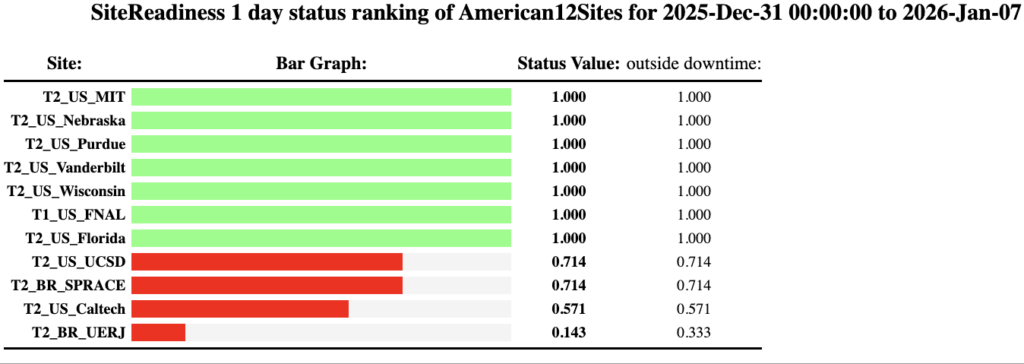
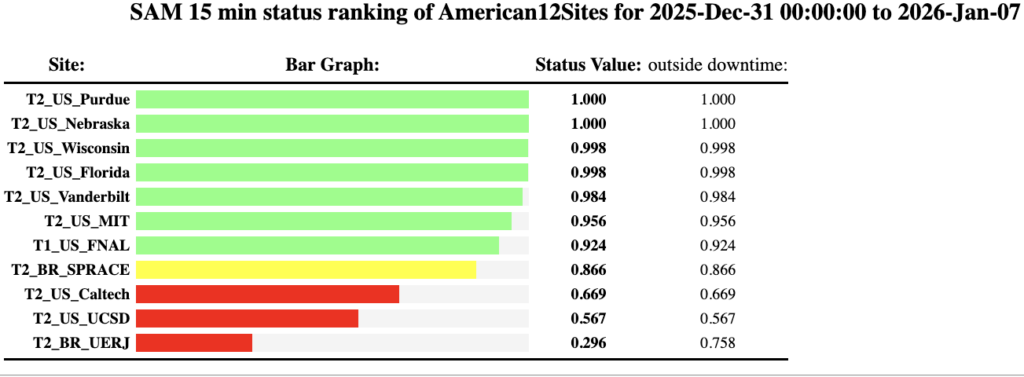
SiteReadiness: 100%
SAM tests: 95.6%
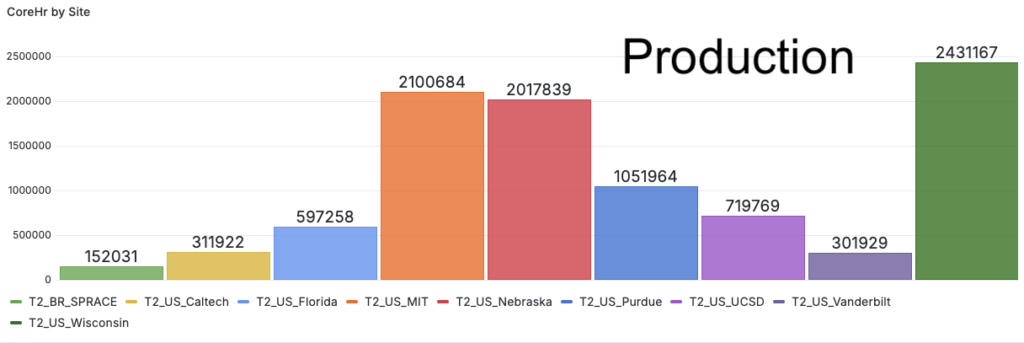
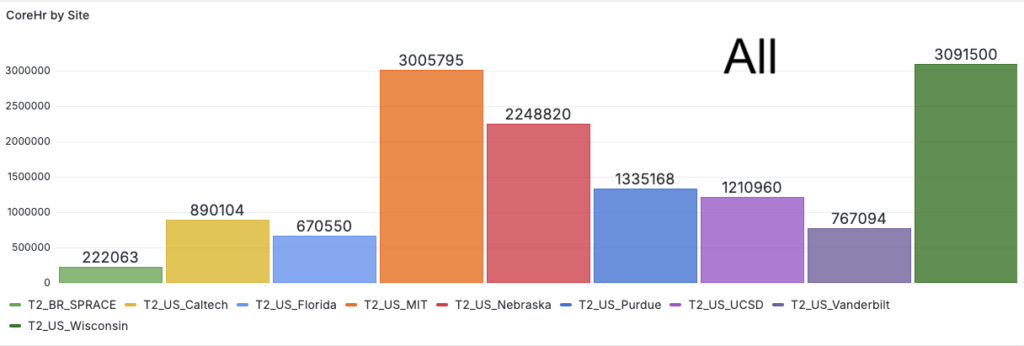
No major issues over the last week. Slight inefficiency is caused by Condor reconfiguration of WNs to improve the use of available resources.
Report from Dec 17, 2025
SiteReadiness: 100%
SAM tests: 99.2%
No major issues over the last week.
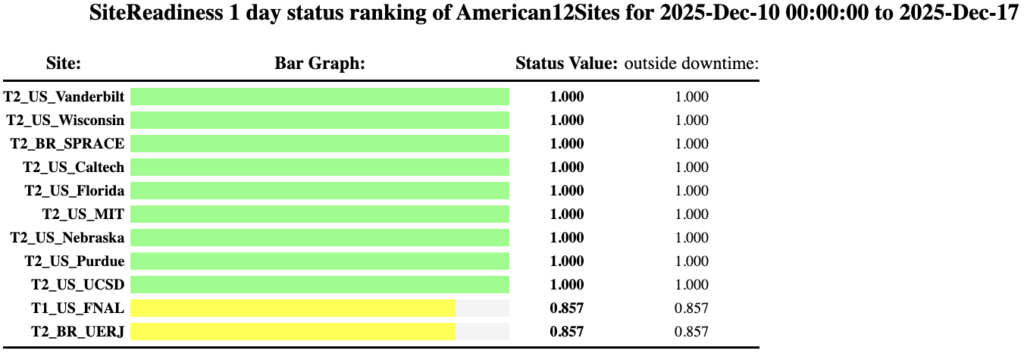
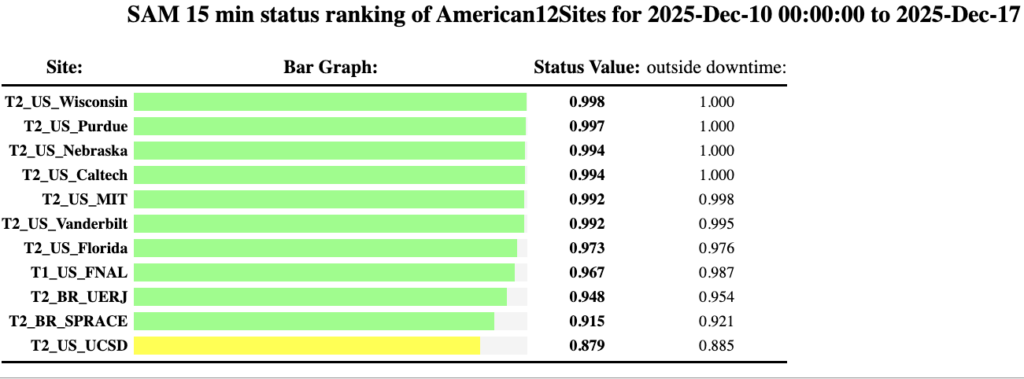
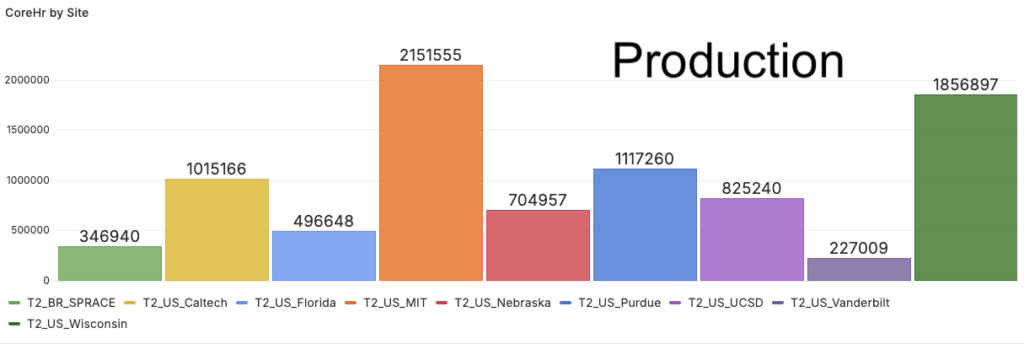
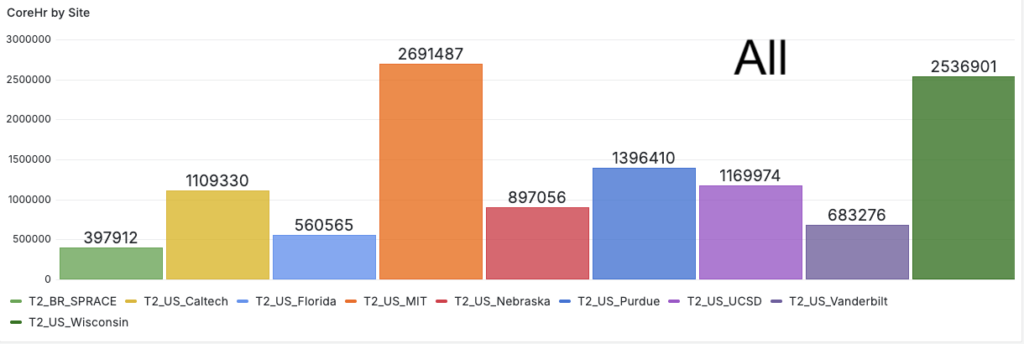
Report from Dec 10, 2025
SiteReadiness: 100%
SAM tests: 99.4%
No major issues over the last week.
Report from Dec 3, 2025
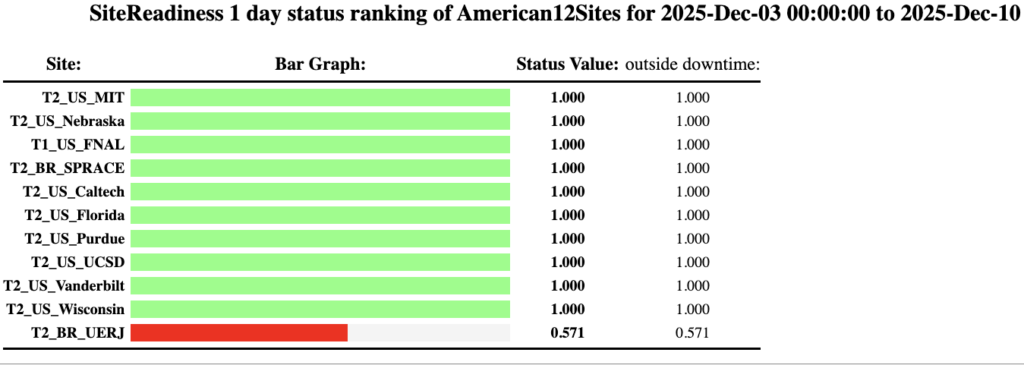
SiteReadiness: 100%
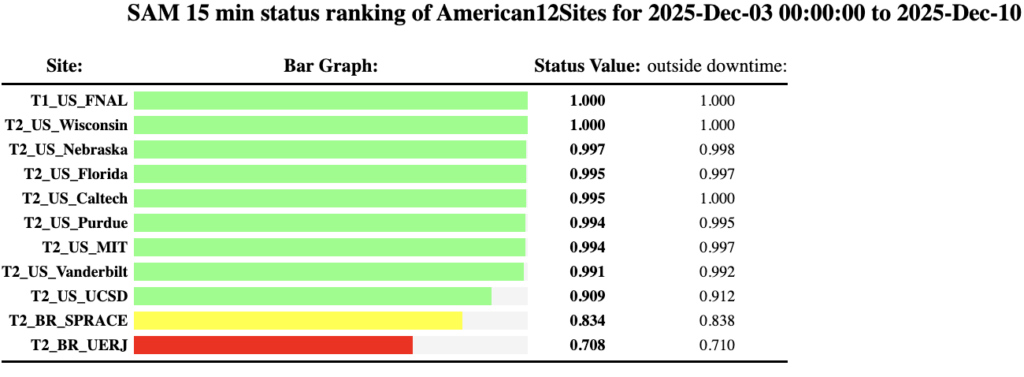
SAM tests: 97.8%
No major issues over the last week.
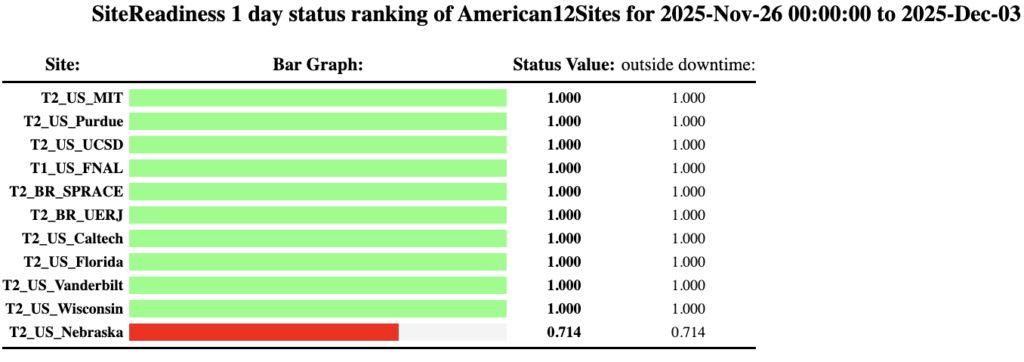
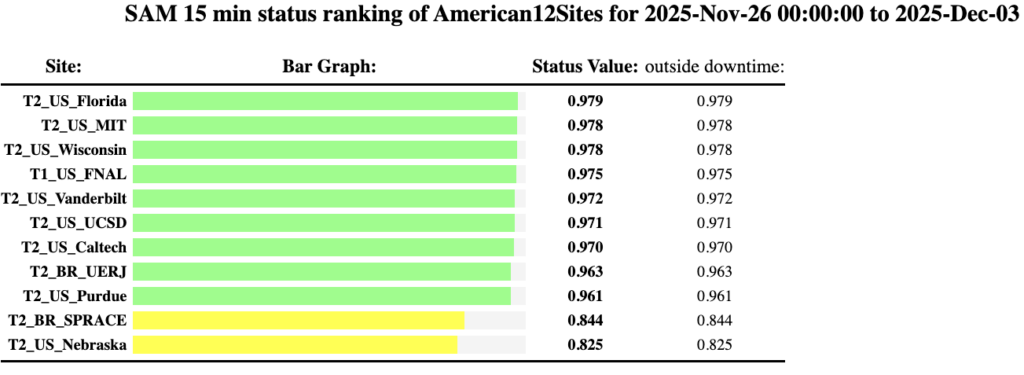
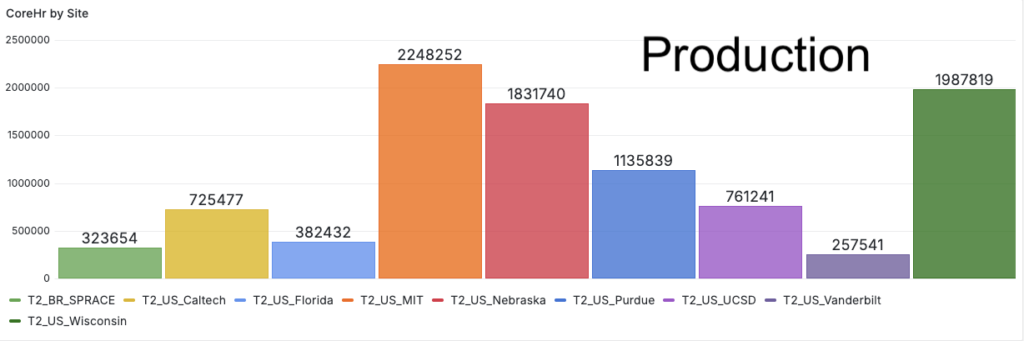
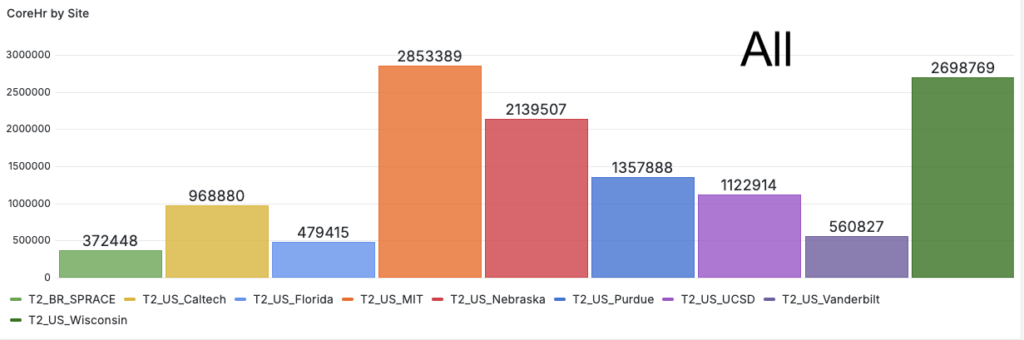
Report from Nov 26, 2025
SiteReadiness: 100%
SAM tests: 99.9%
No major issues over the last week. Storage scans were finished and the results were reported to Data Management (DM) team. DM took an appropriate action. Out of 2.5M files in the storage 7.5K files were identified as corrupted (0.3%).
Report from Nov 19, 2025
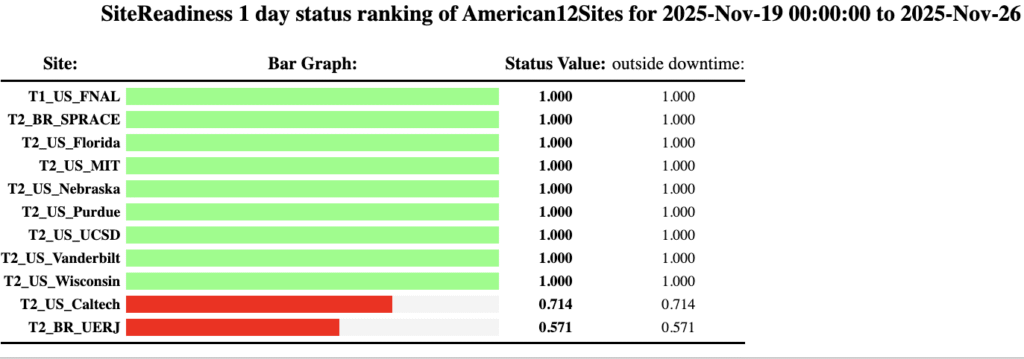
SiteReadiness: 100%
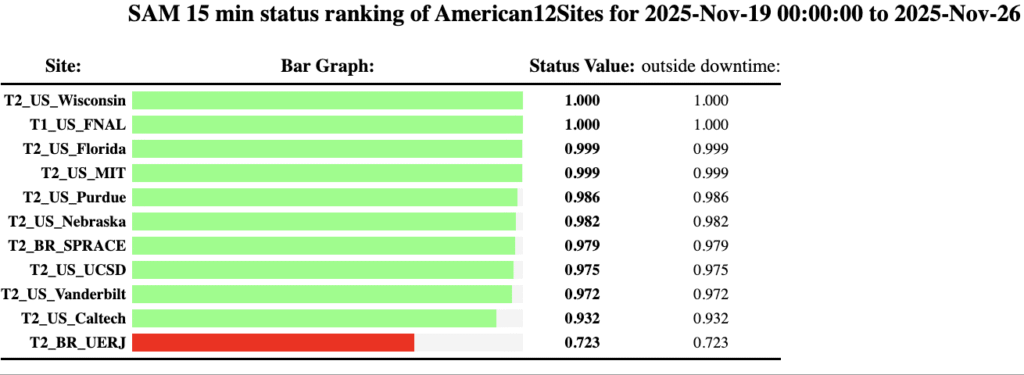
SAM tests: 100%
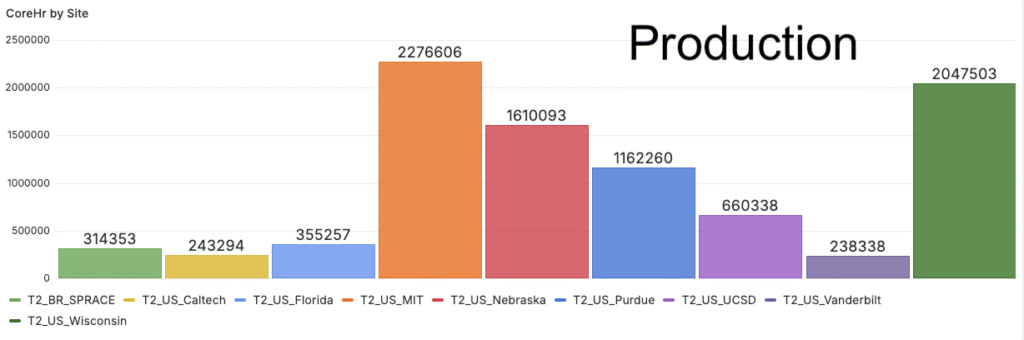
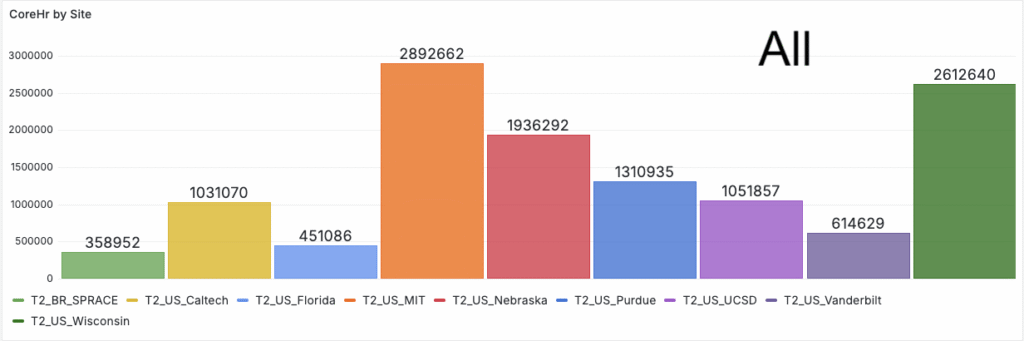
No major issues over the last week. We were asked to run storage scan that compares for all files a local adler32 checksum with the one from Rucio. The scan is still ongoing.
Report from Nov 5, 2025
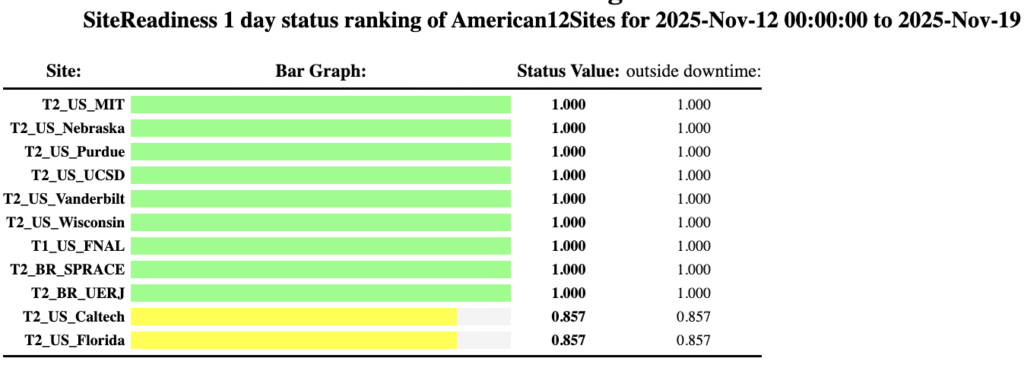
SiteReadiness: 100.0%
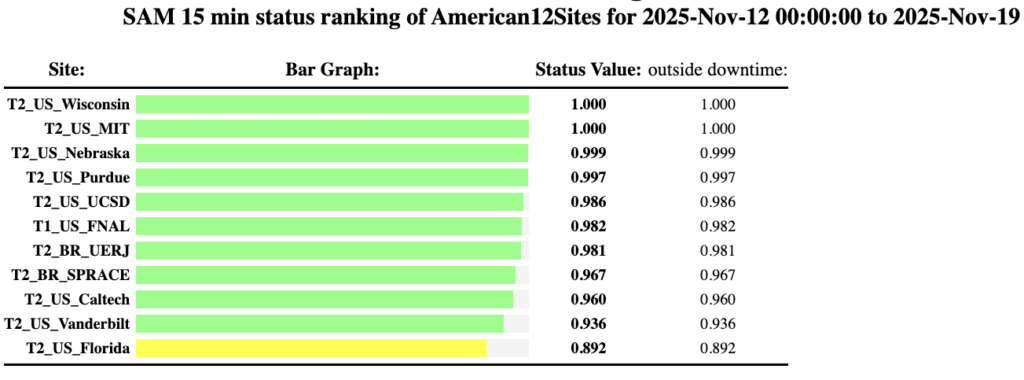
SAM tests: 96.3%
We experienced a power outage at the host facility that started on Monday at around 10:30 a.m. and lasted for 3 hours. During the outage all worker nodes were offline. The storage, meanwhile, stayed online and was fully available.
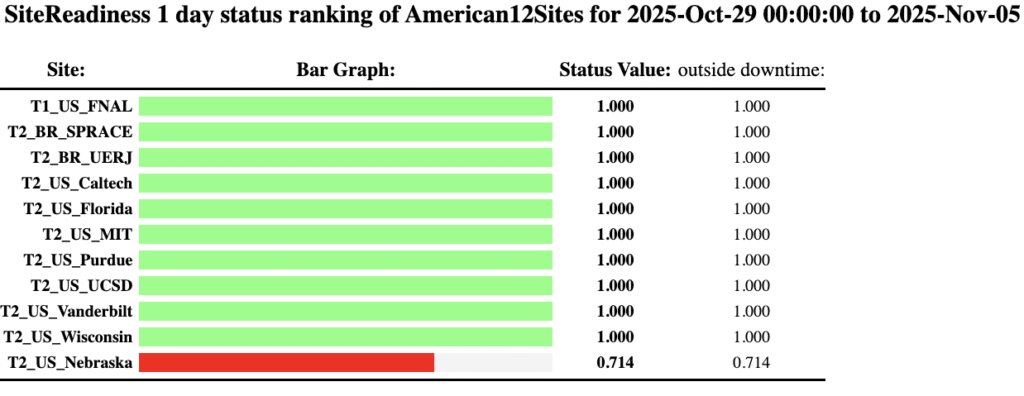
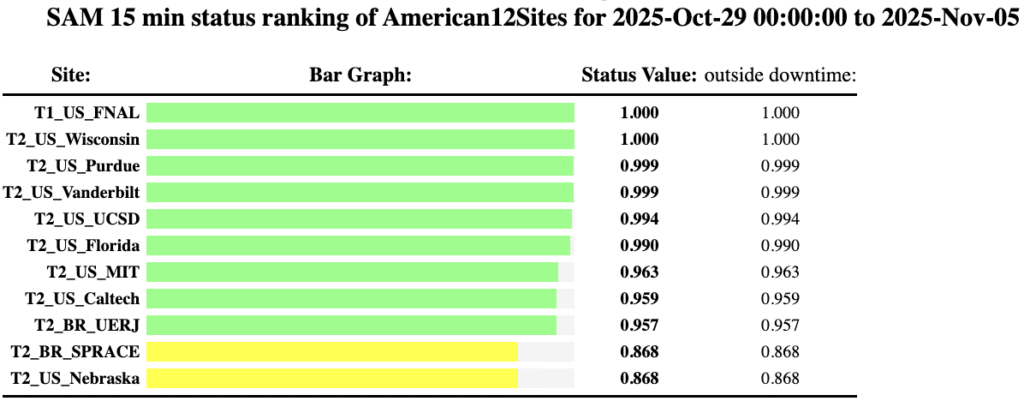
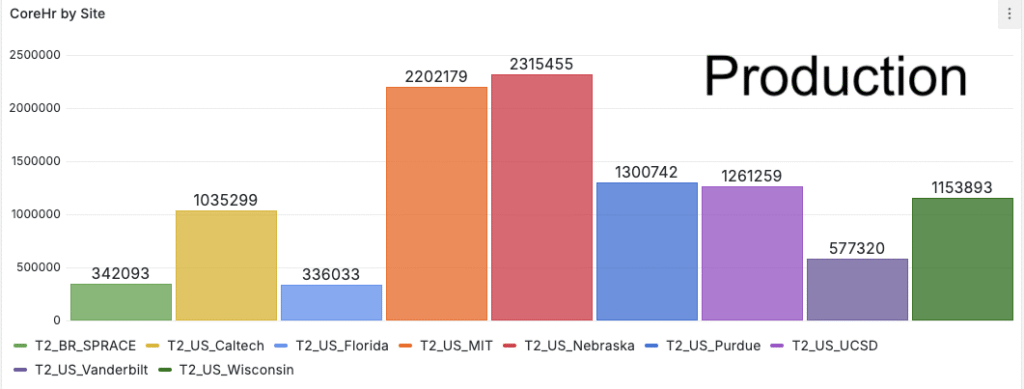
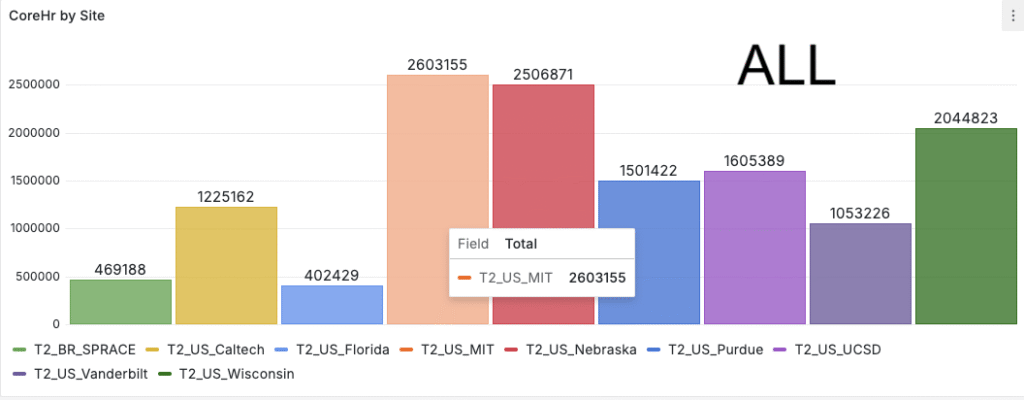
Report from October 29, 2025
SiteReadiness: 100.0%
SAM tests: 99.7%
No real issues over last week.
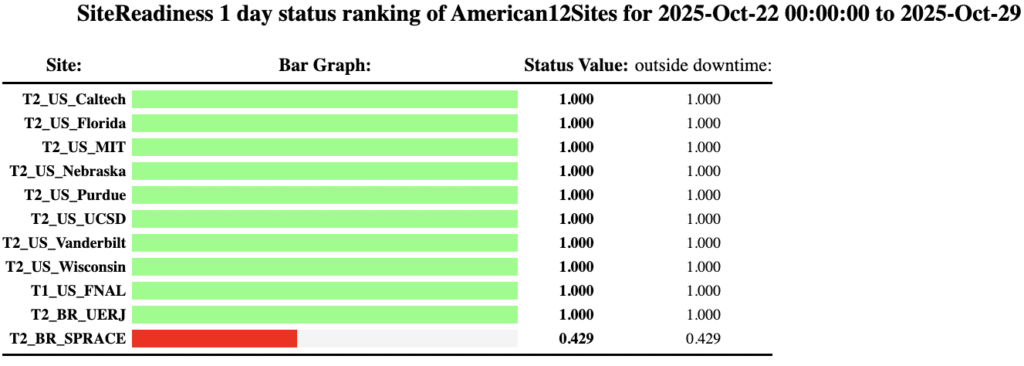
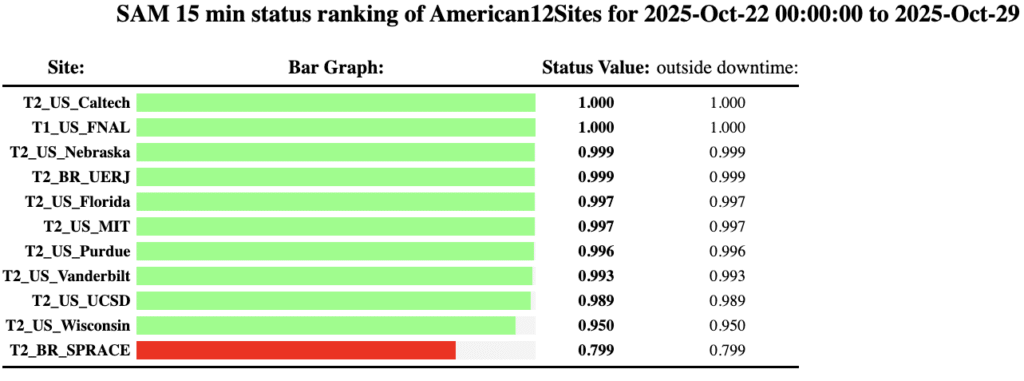
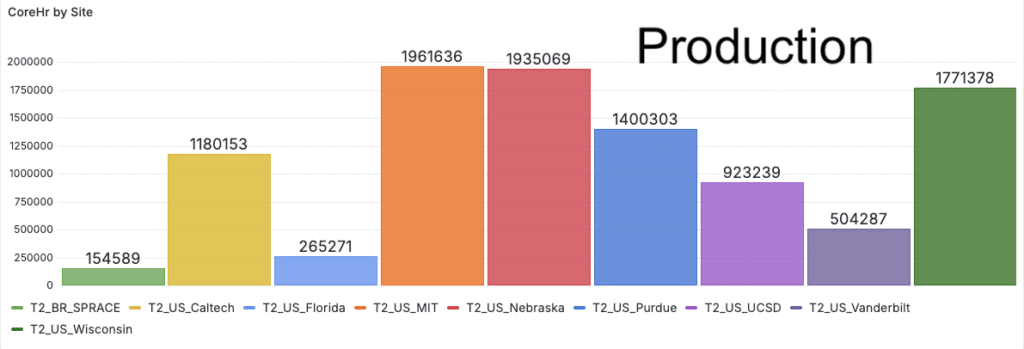
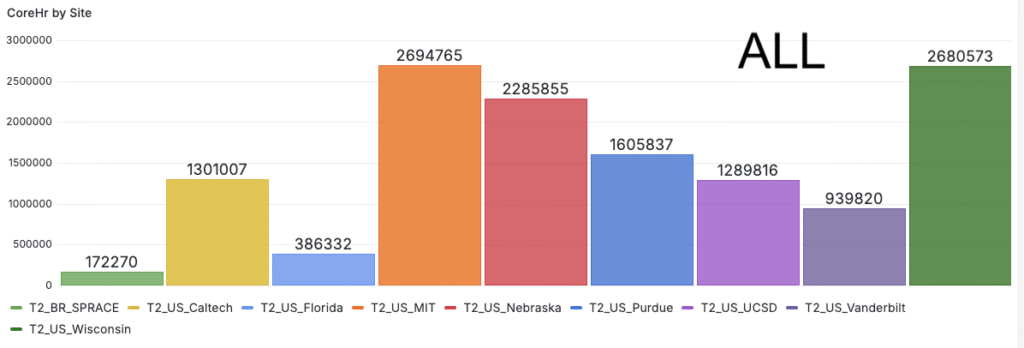
Report from October 22, 2025
SiteReadiness: 100.0%
SAM tests: 100.0%
No real issues over last week.
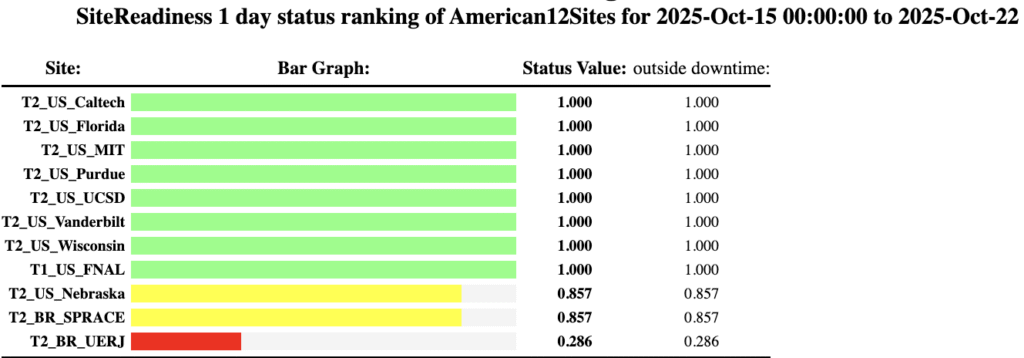
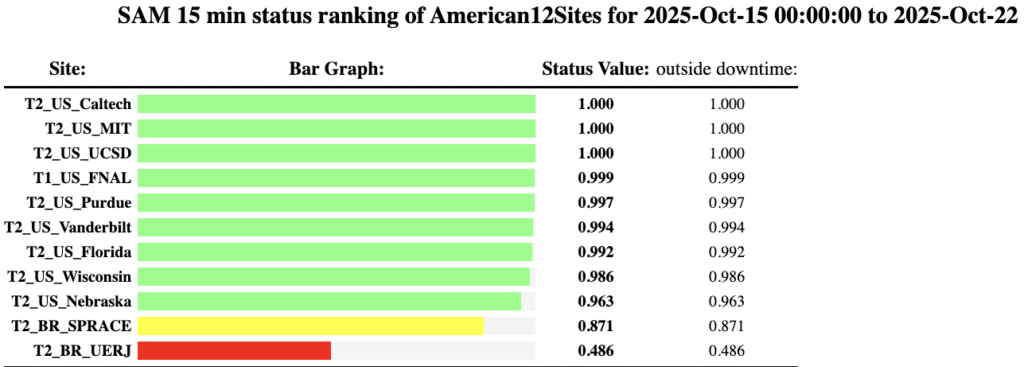
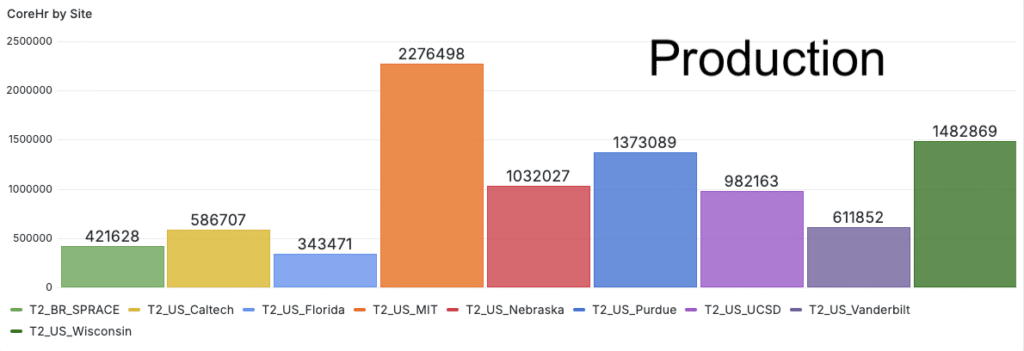
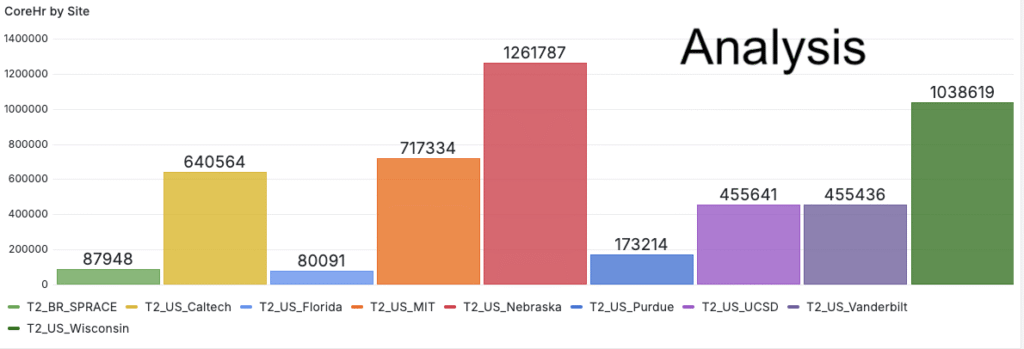
Report from October 8, 2025
SiteReadiness: 100.0%
SAM tests: 97.9%
No real issues over last week.
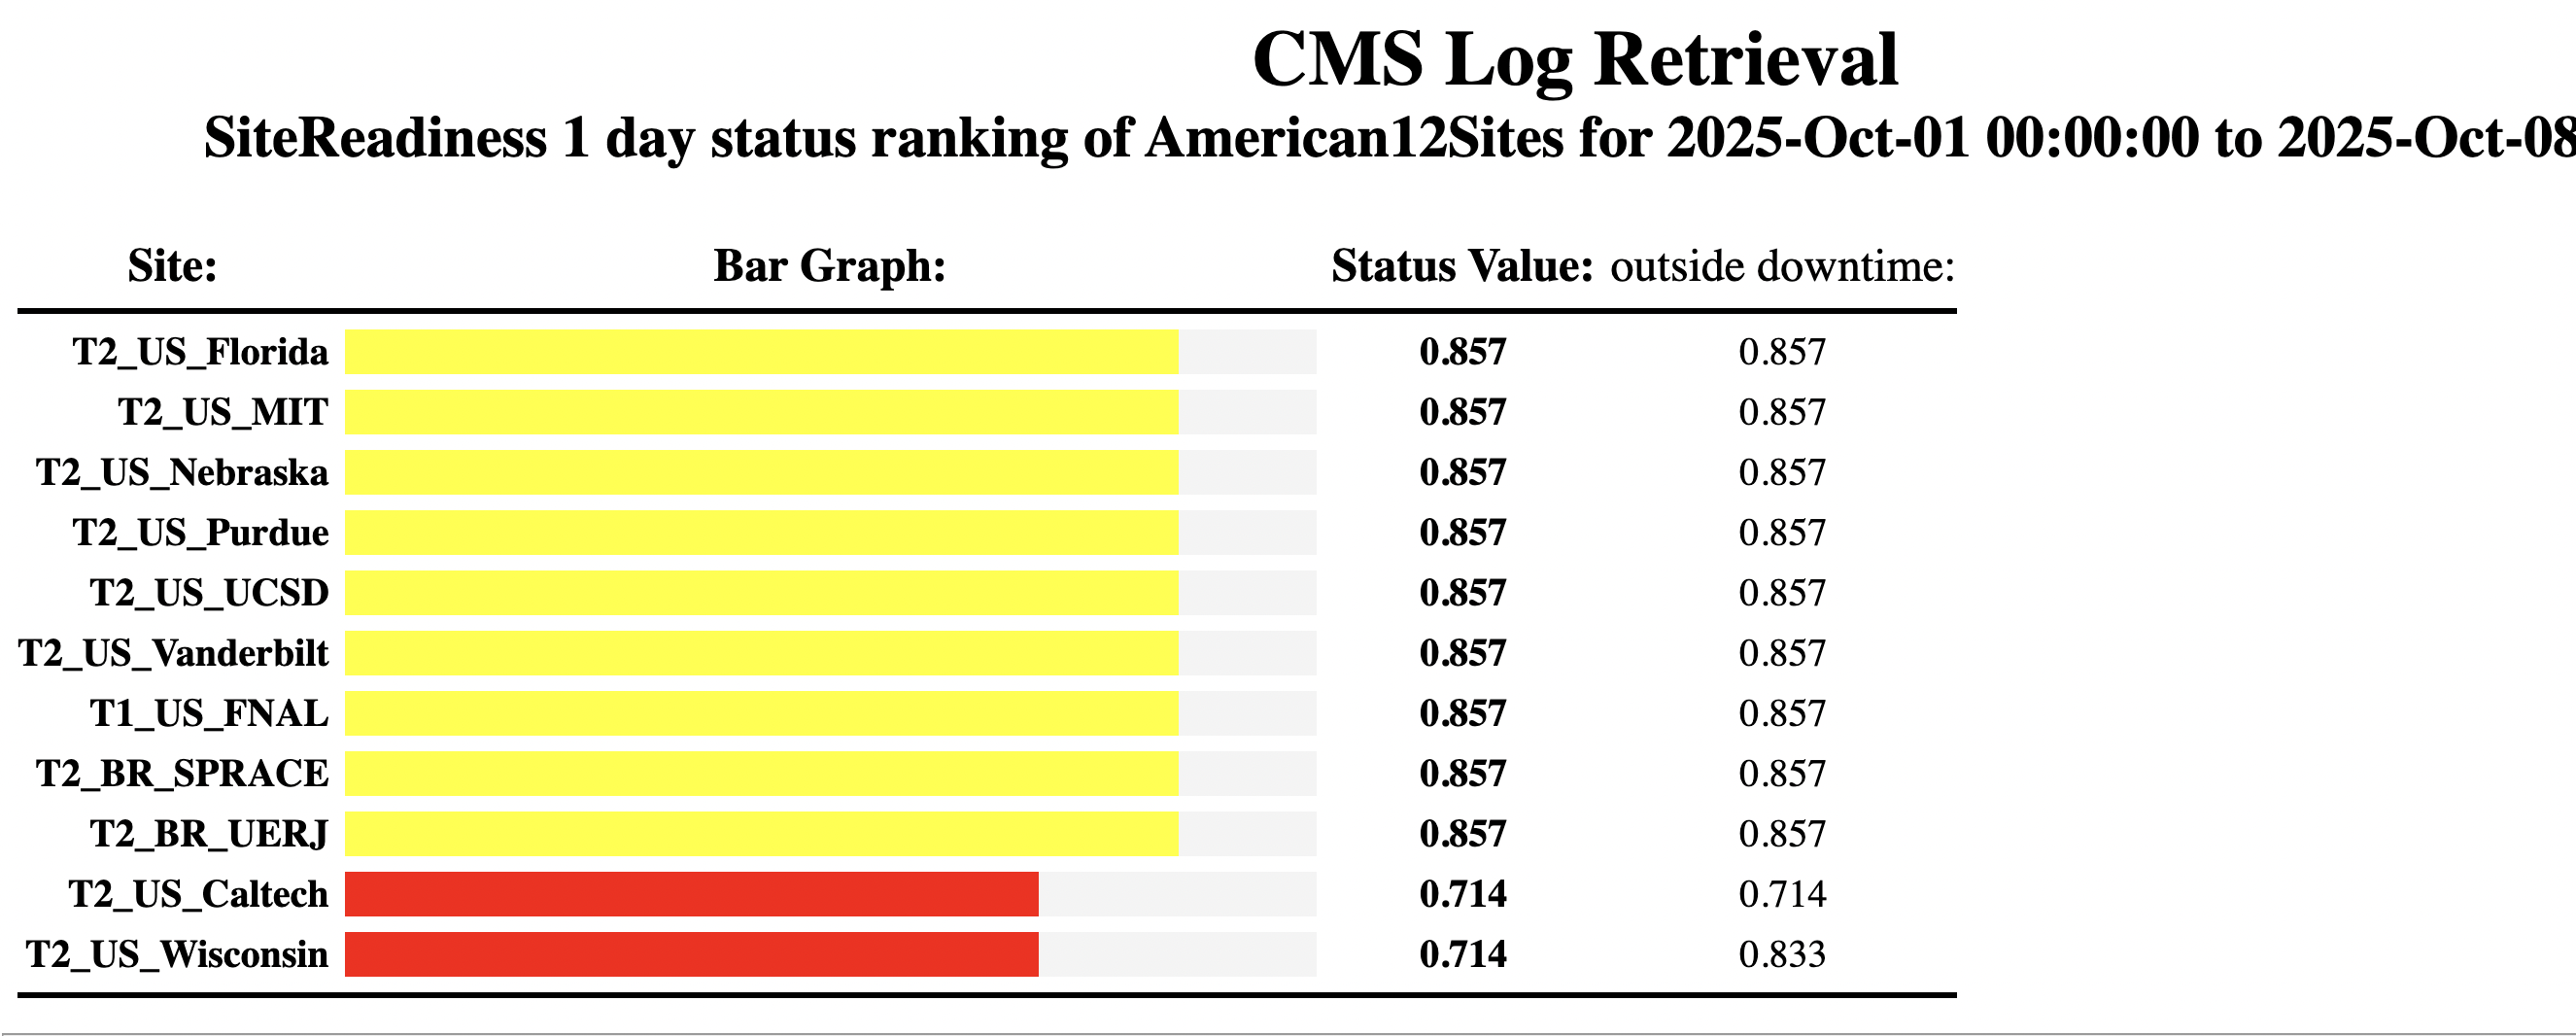
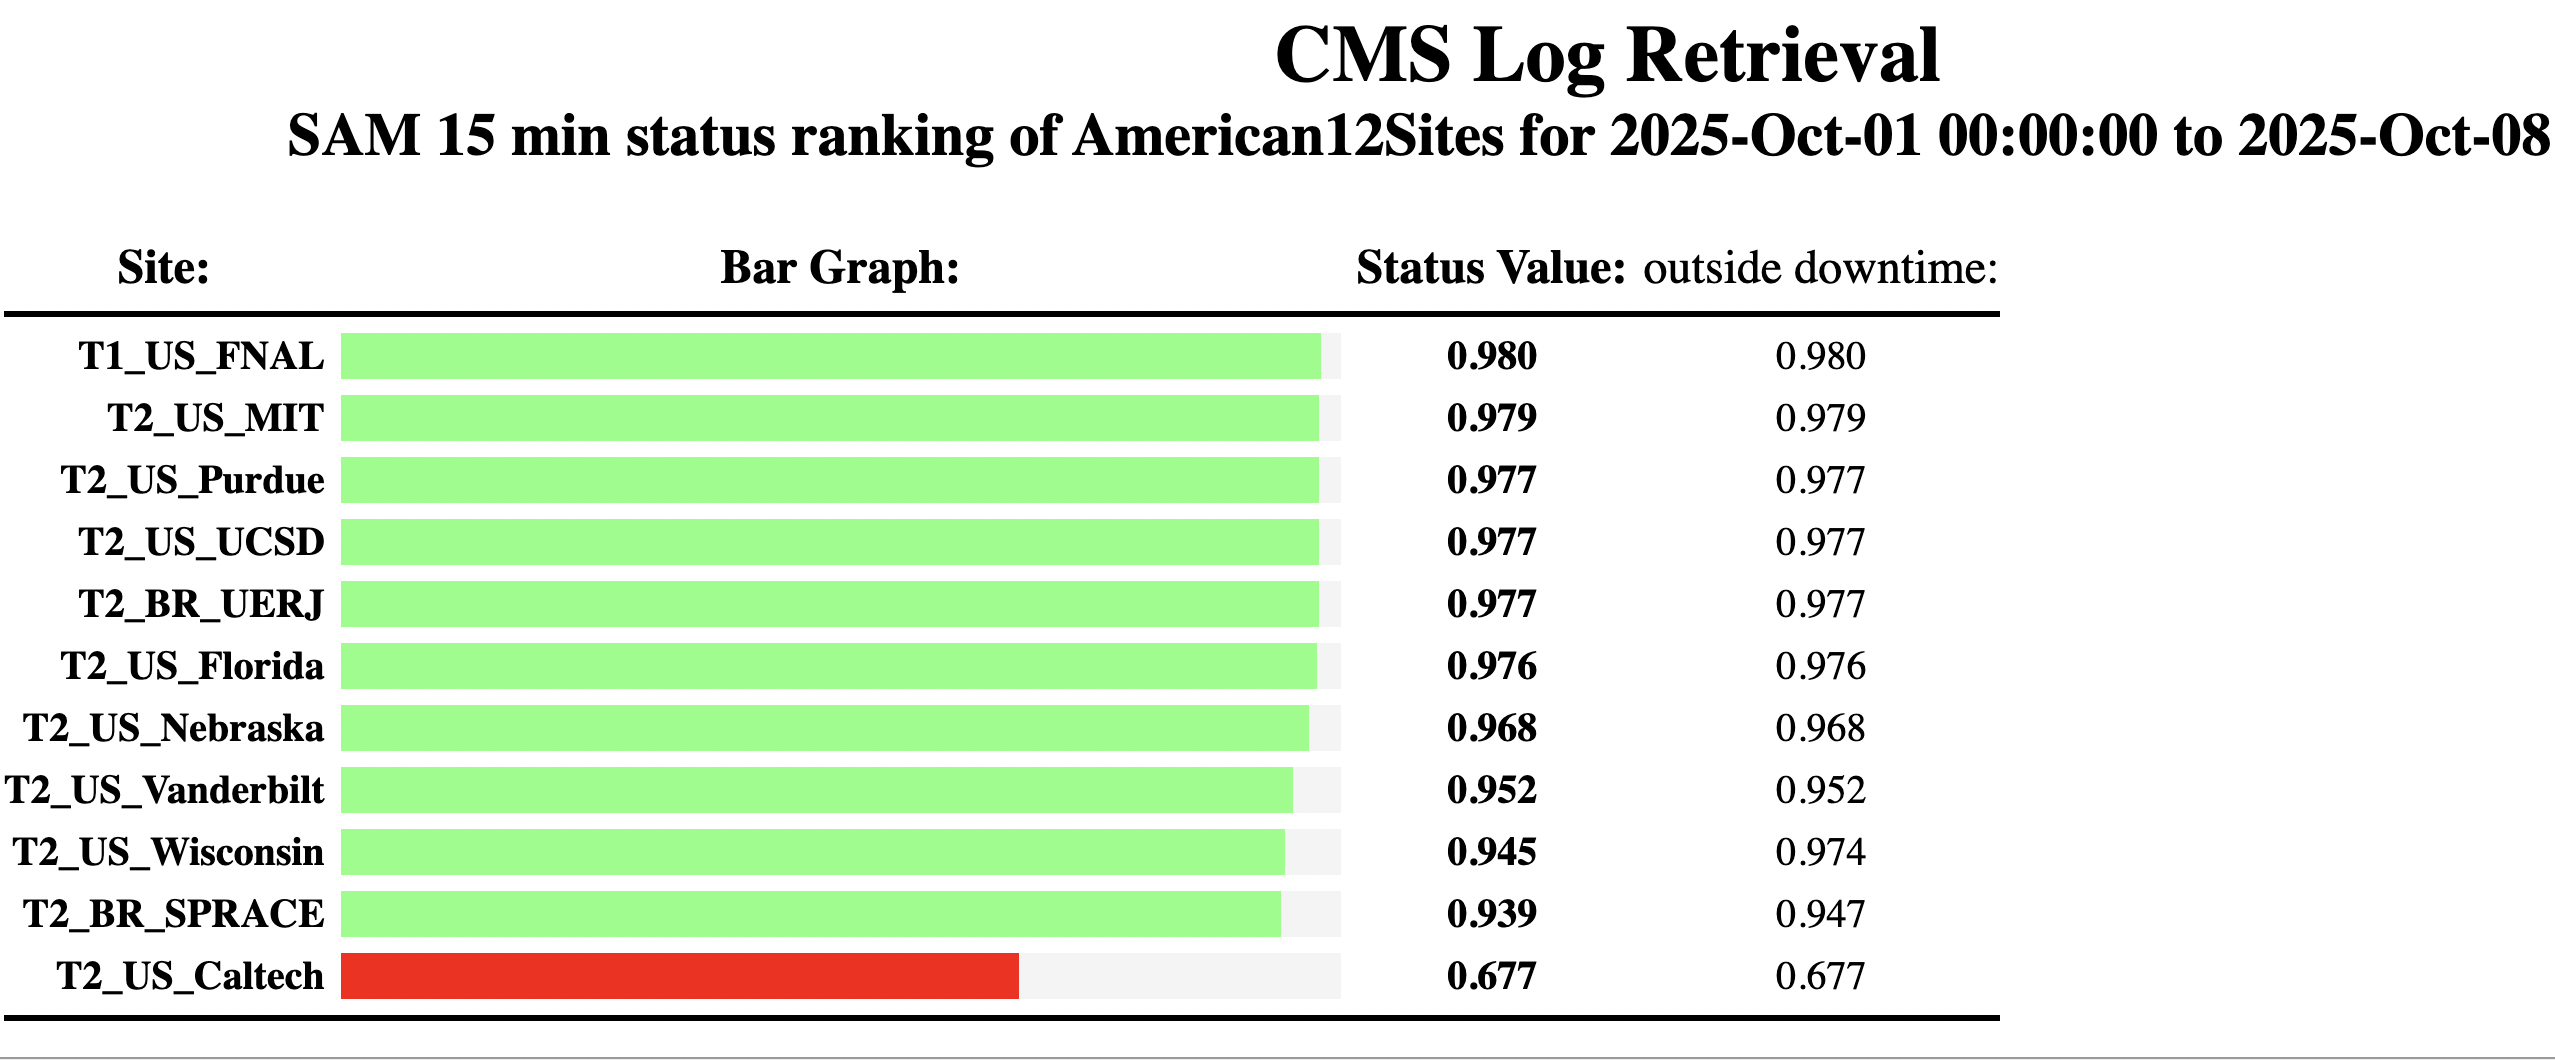
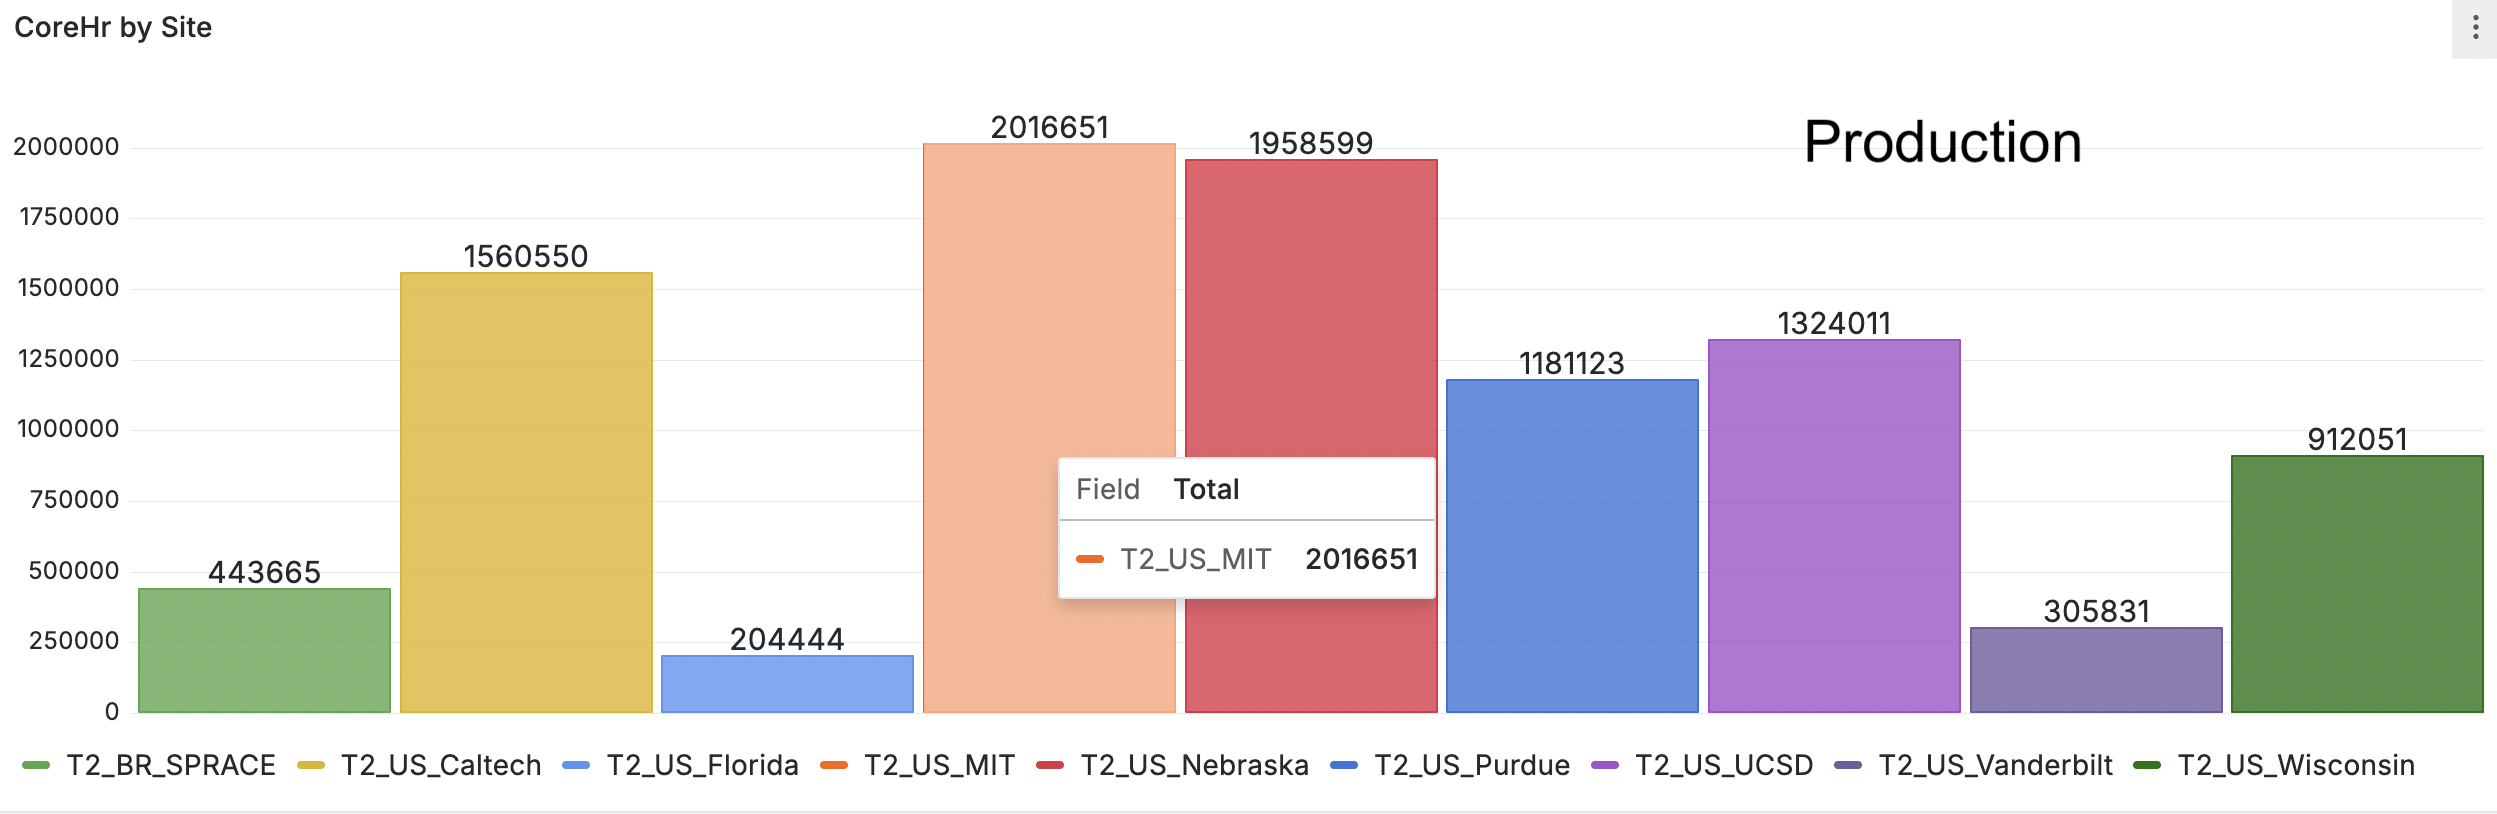
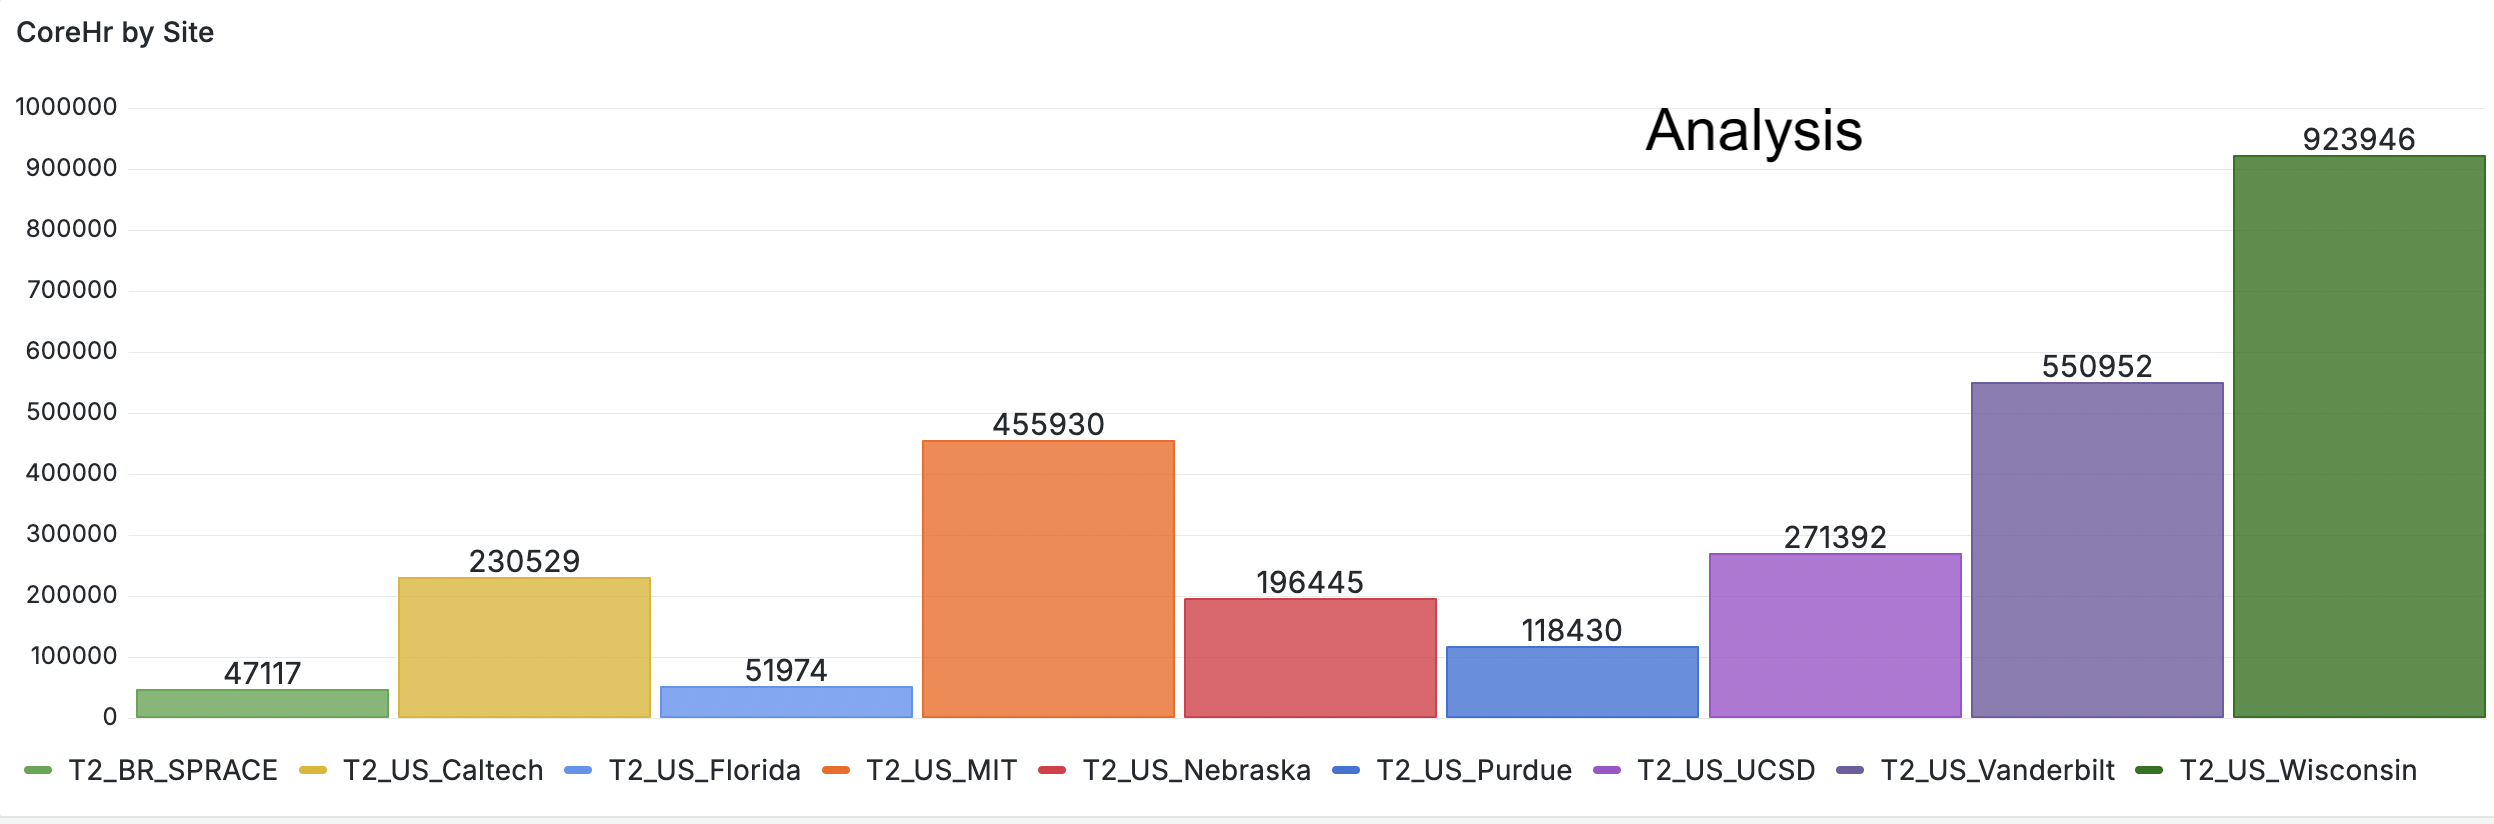
Report from October 1, 2025
SiteReadiness: 100.0%
SAM tests: 98.9%
No real issues over last week.
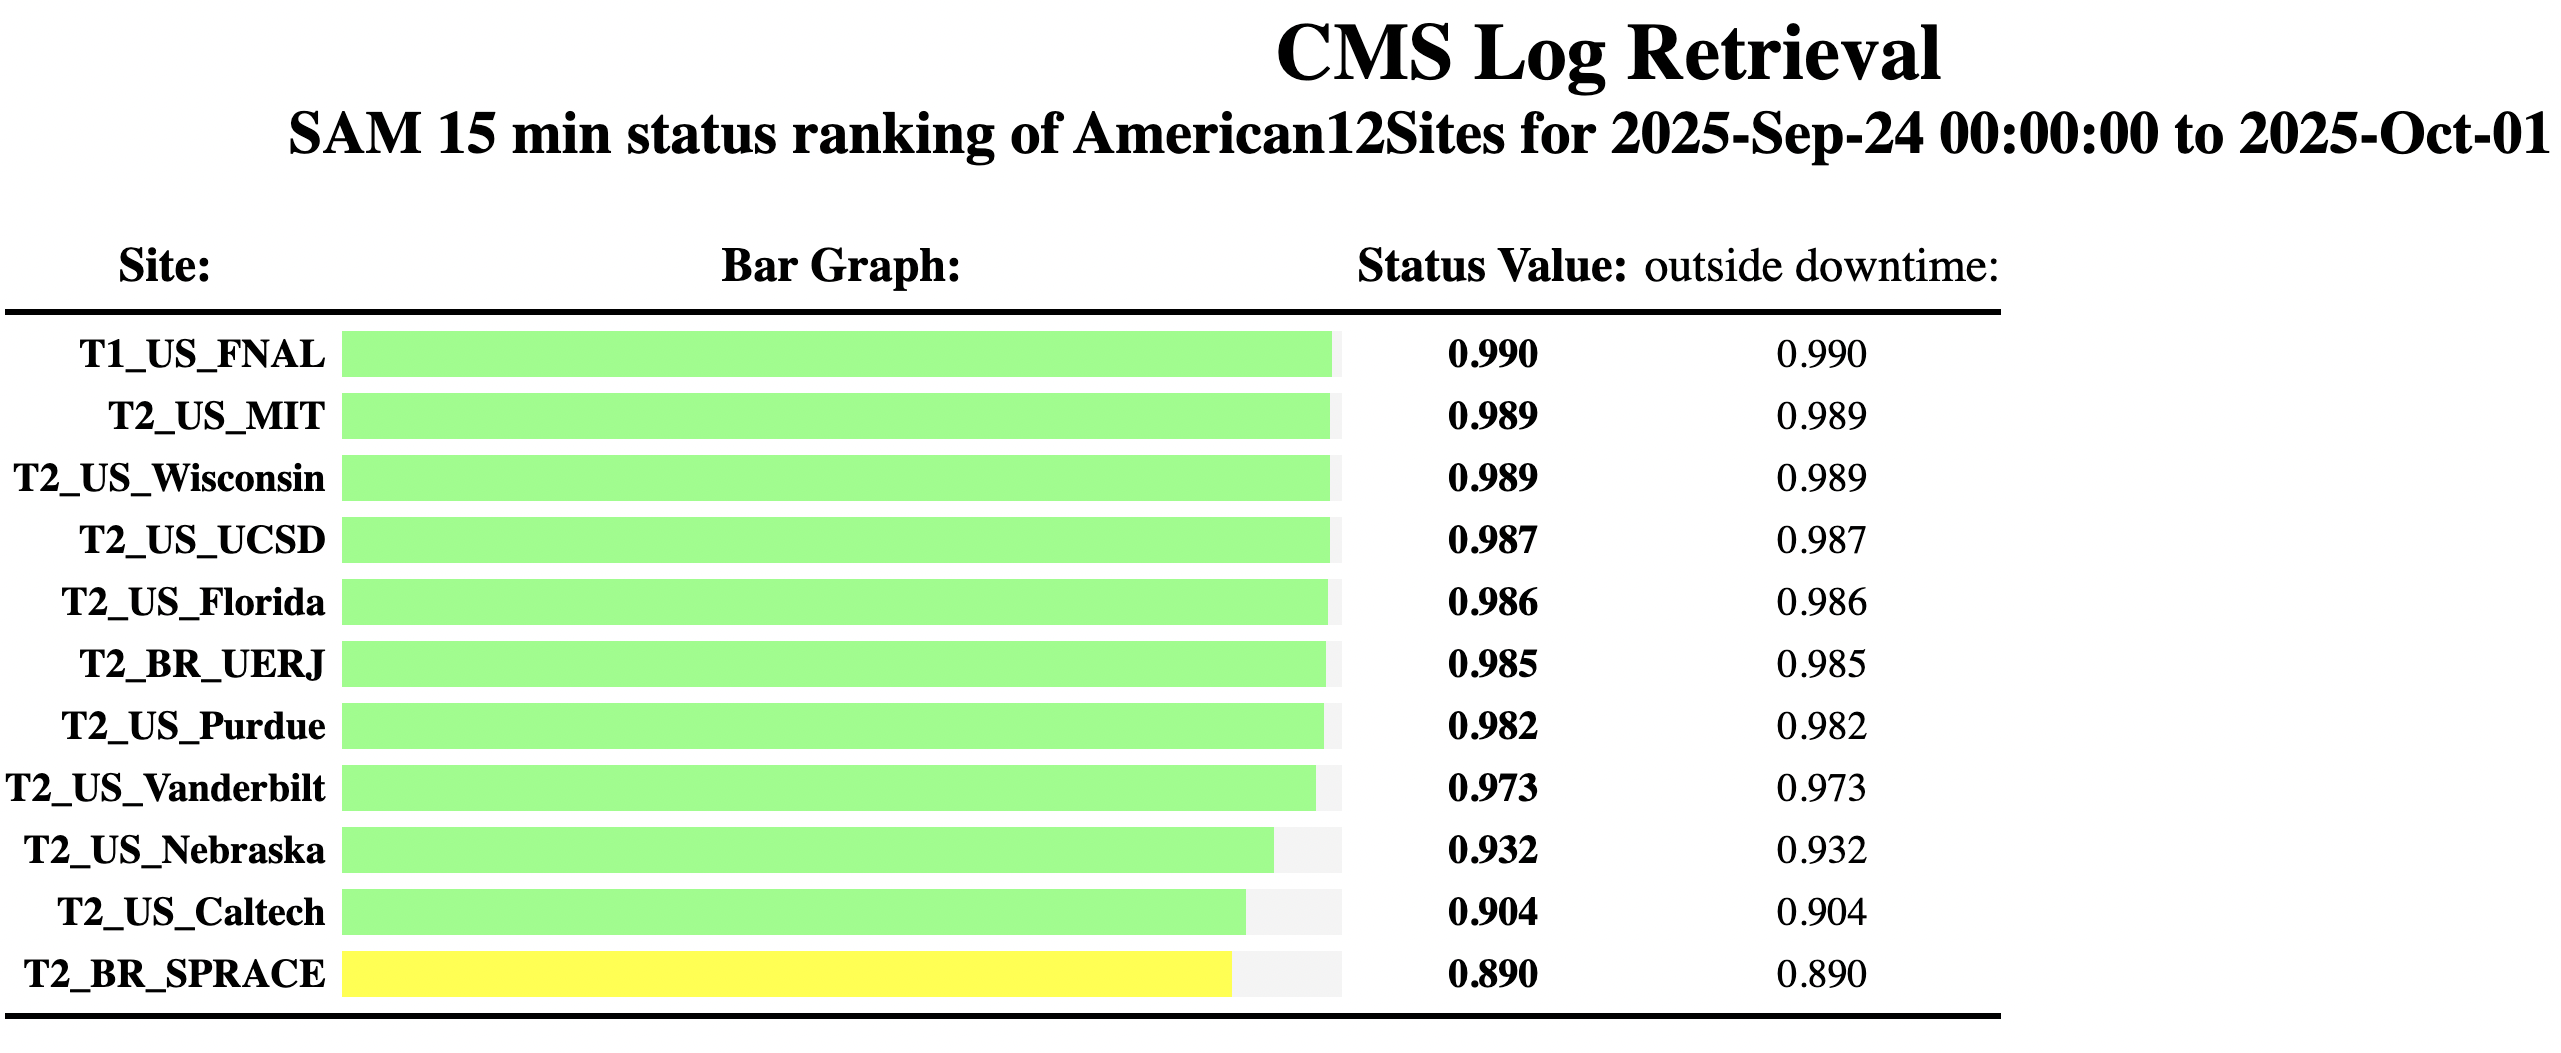
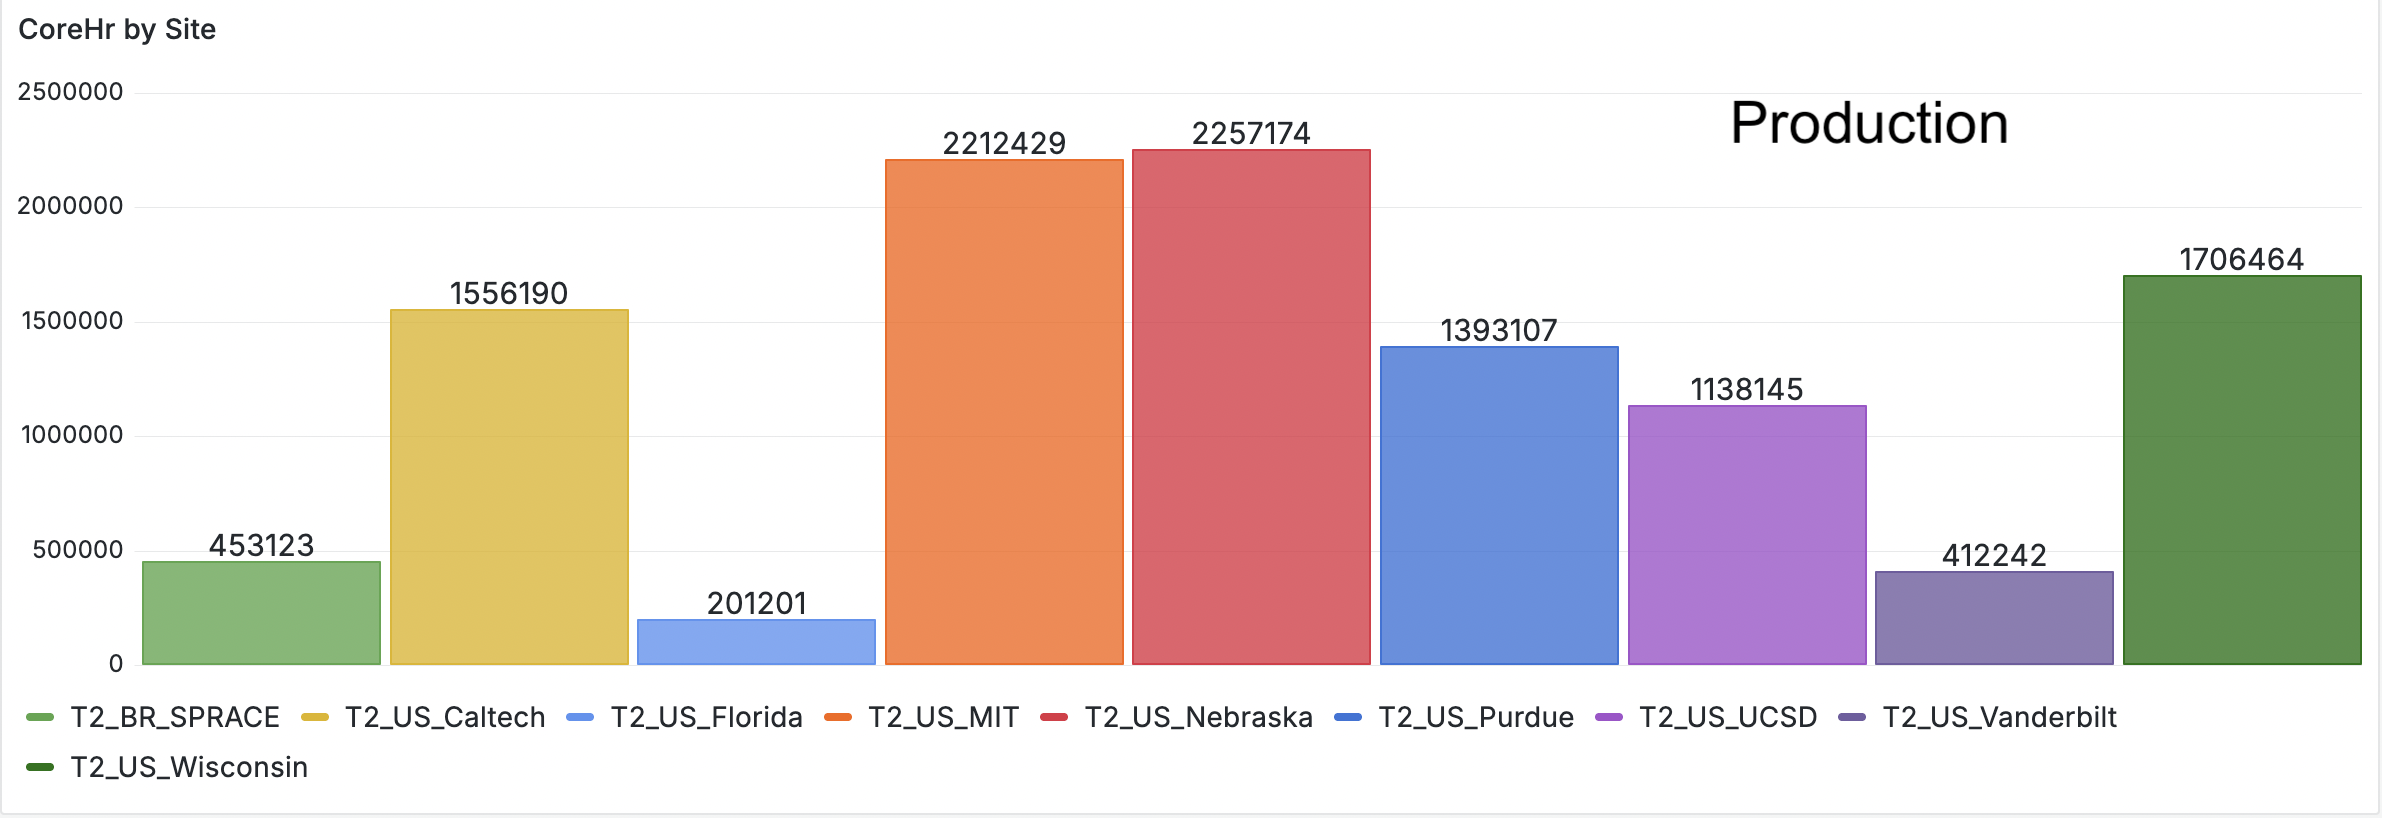
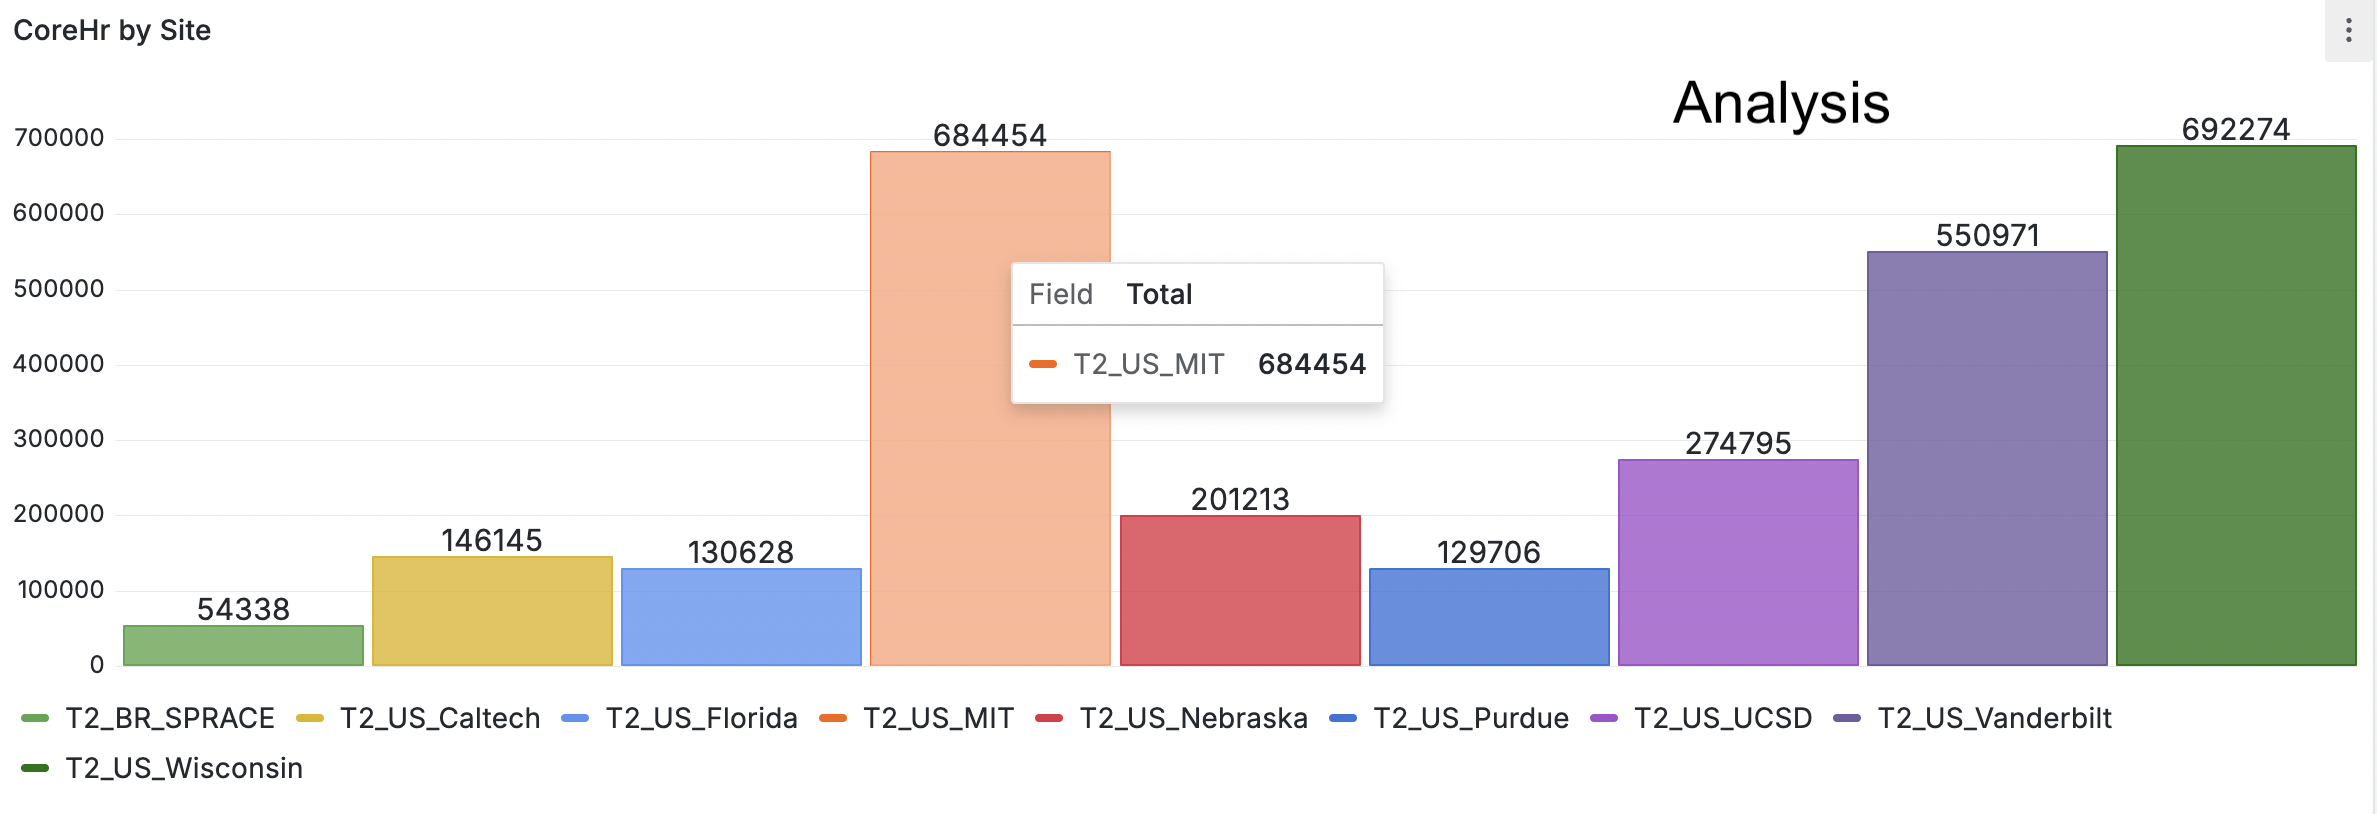
Report from September 24, 2025
SiteReadiness: 100.0%
SAM tests: 100.0%
No real issues over last week.
Report from September 17, 2025
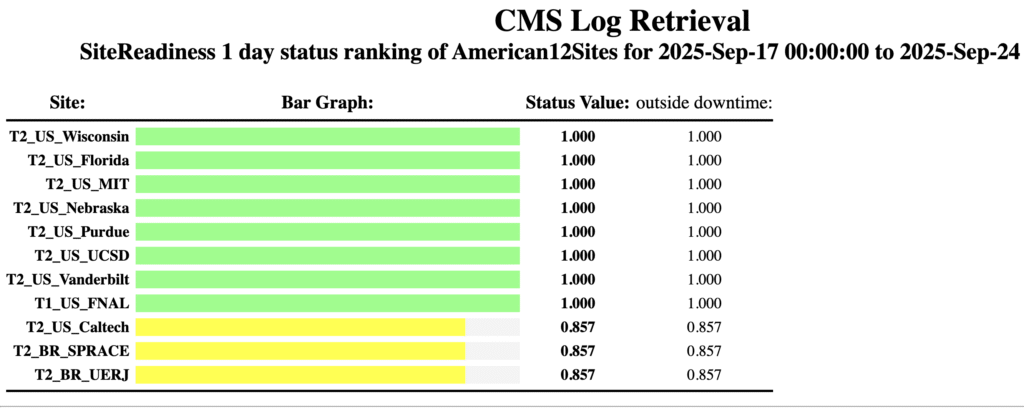
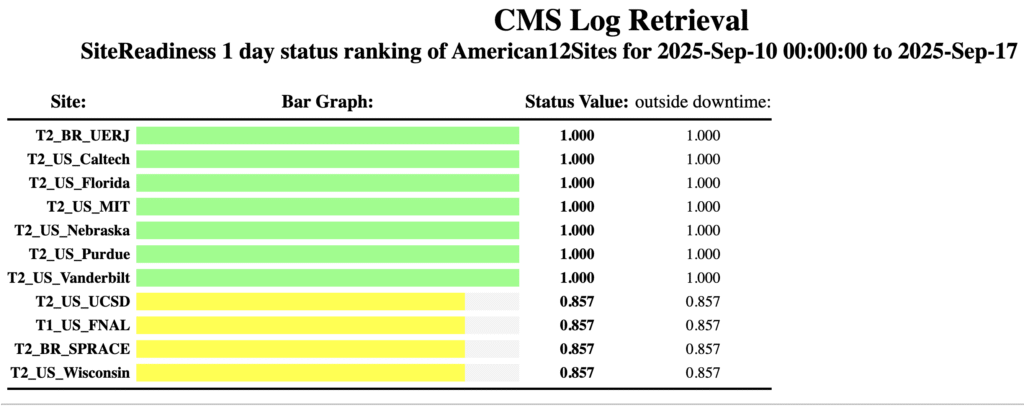
SiteReadiness: 100.0%
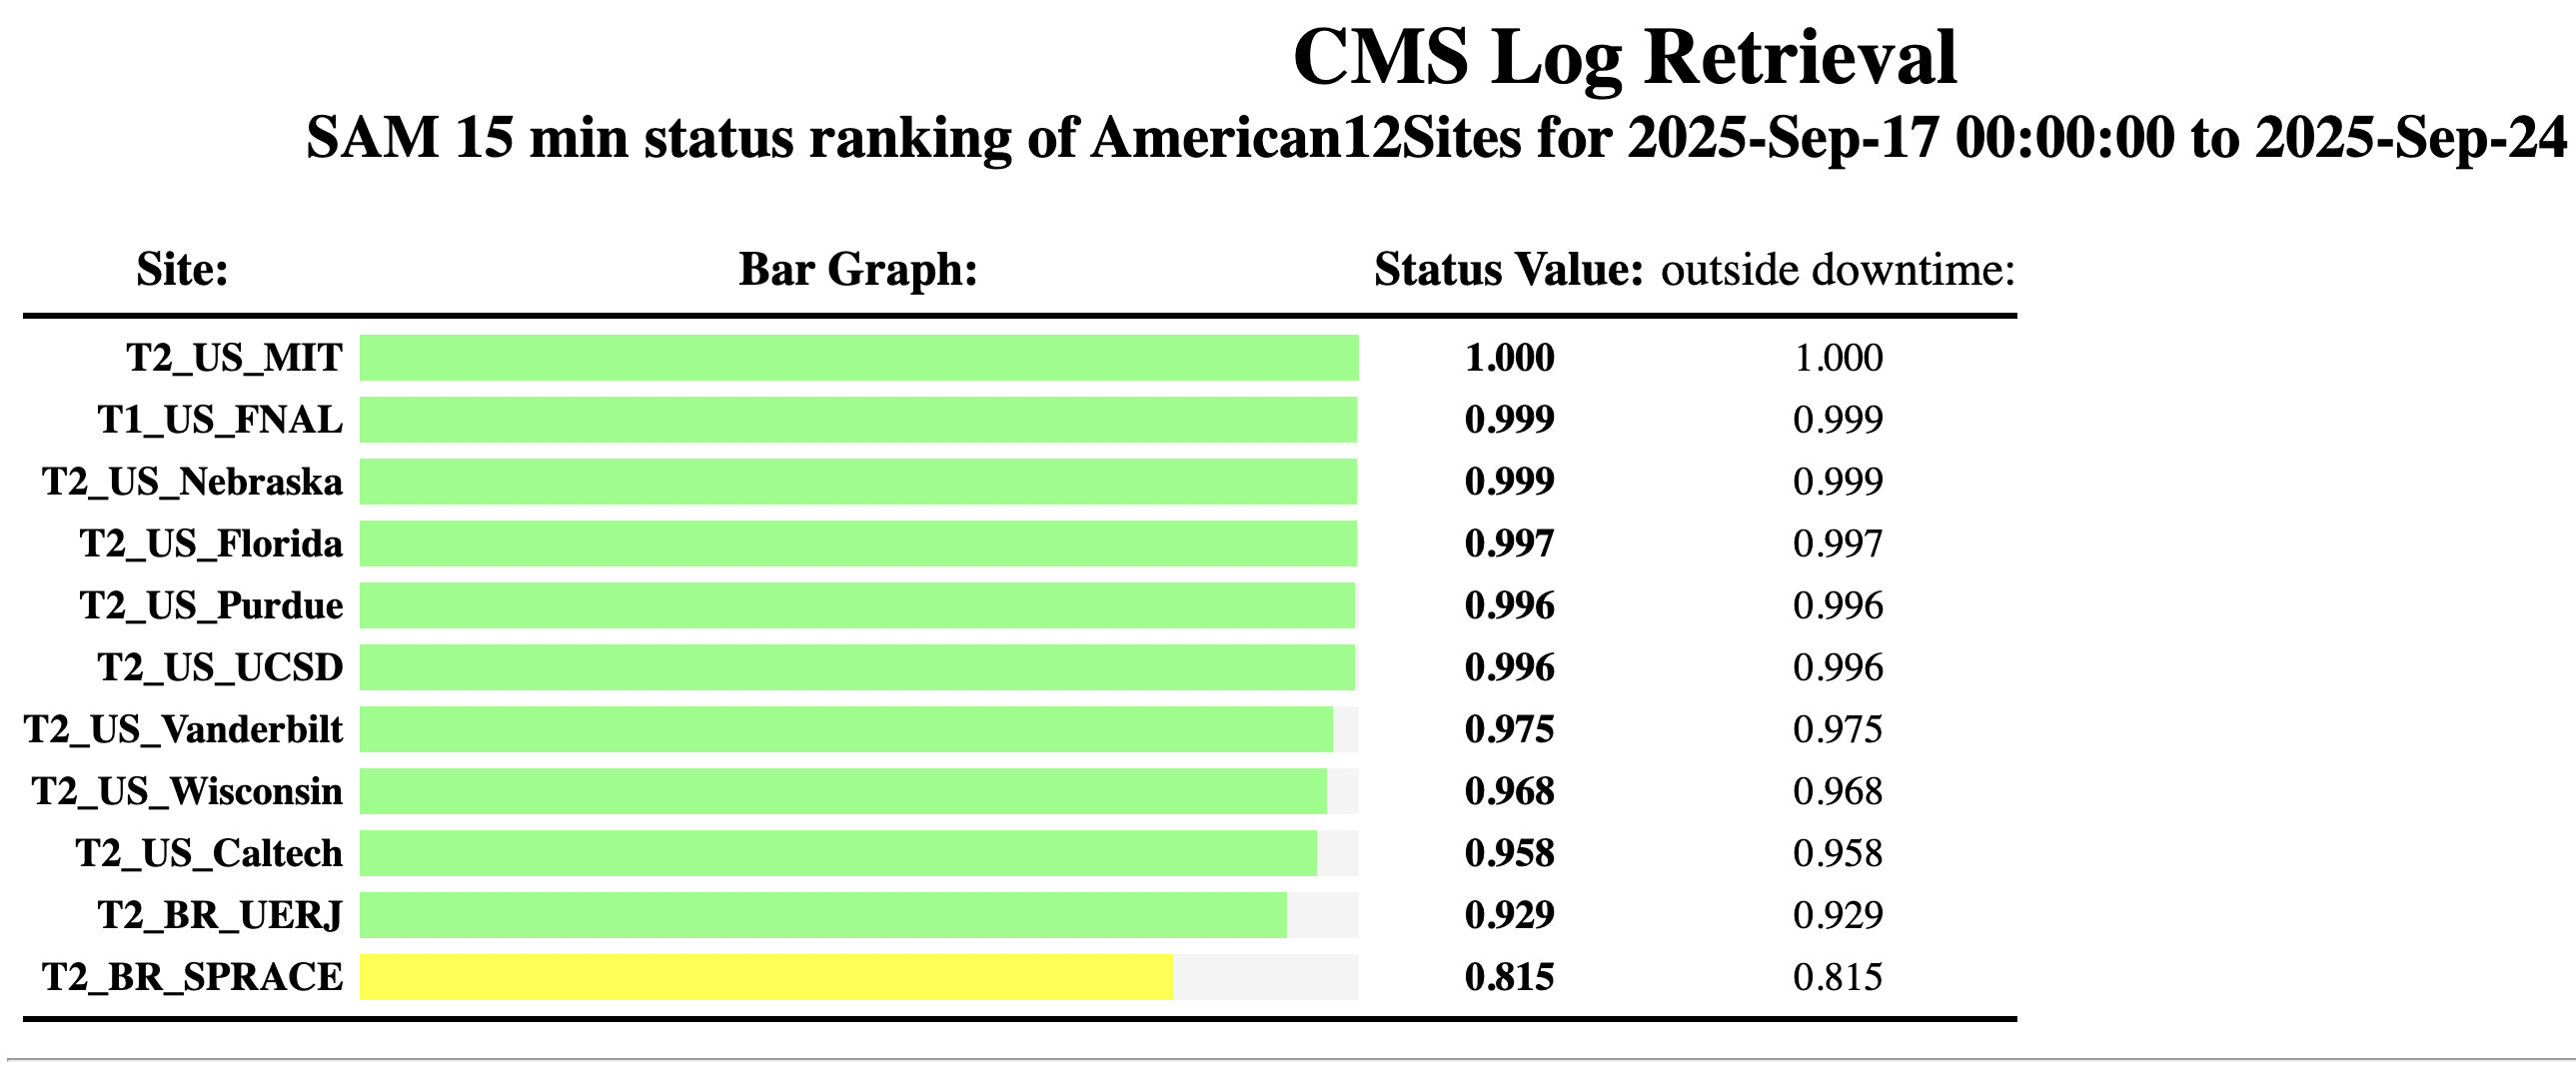
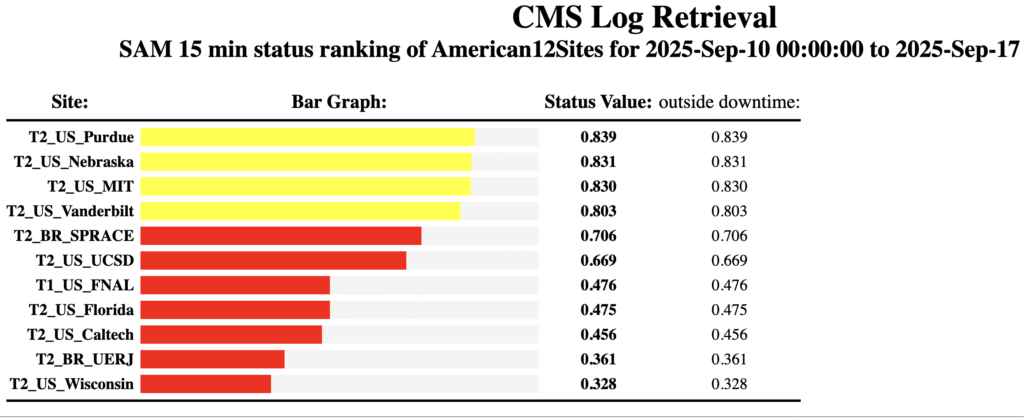
SAM tests: 83.0%
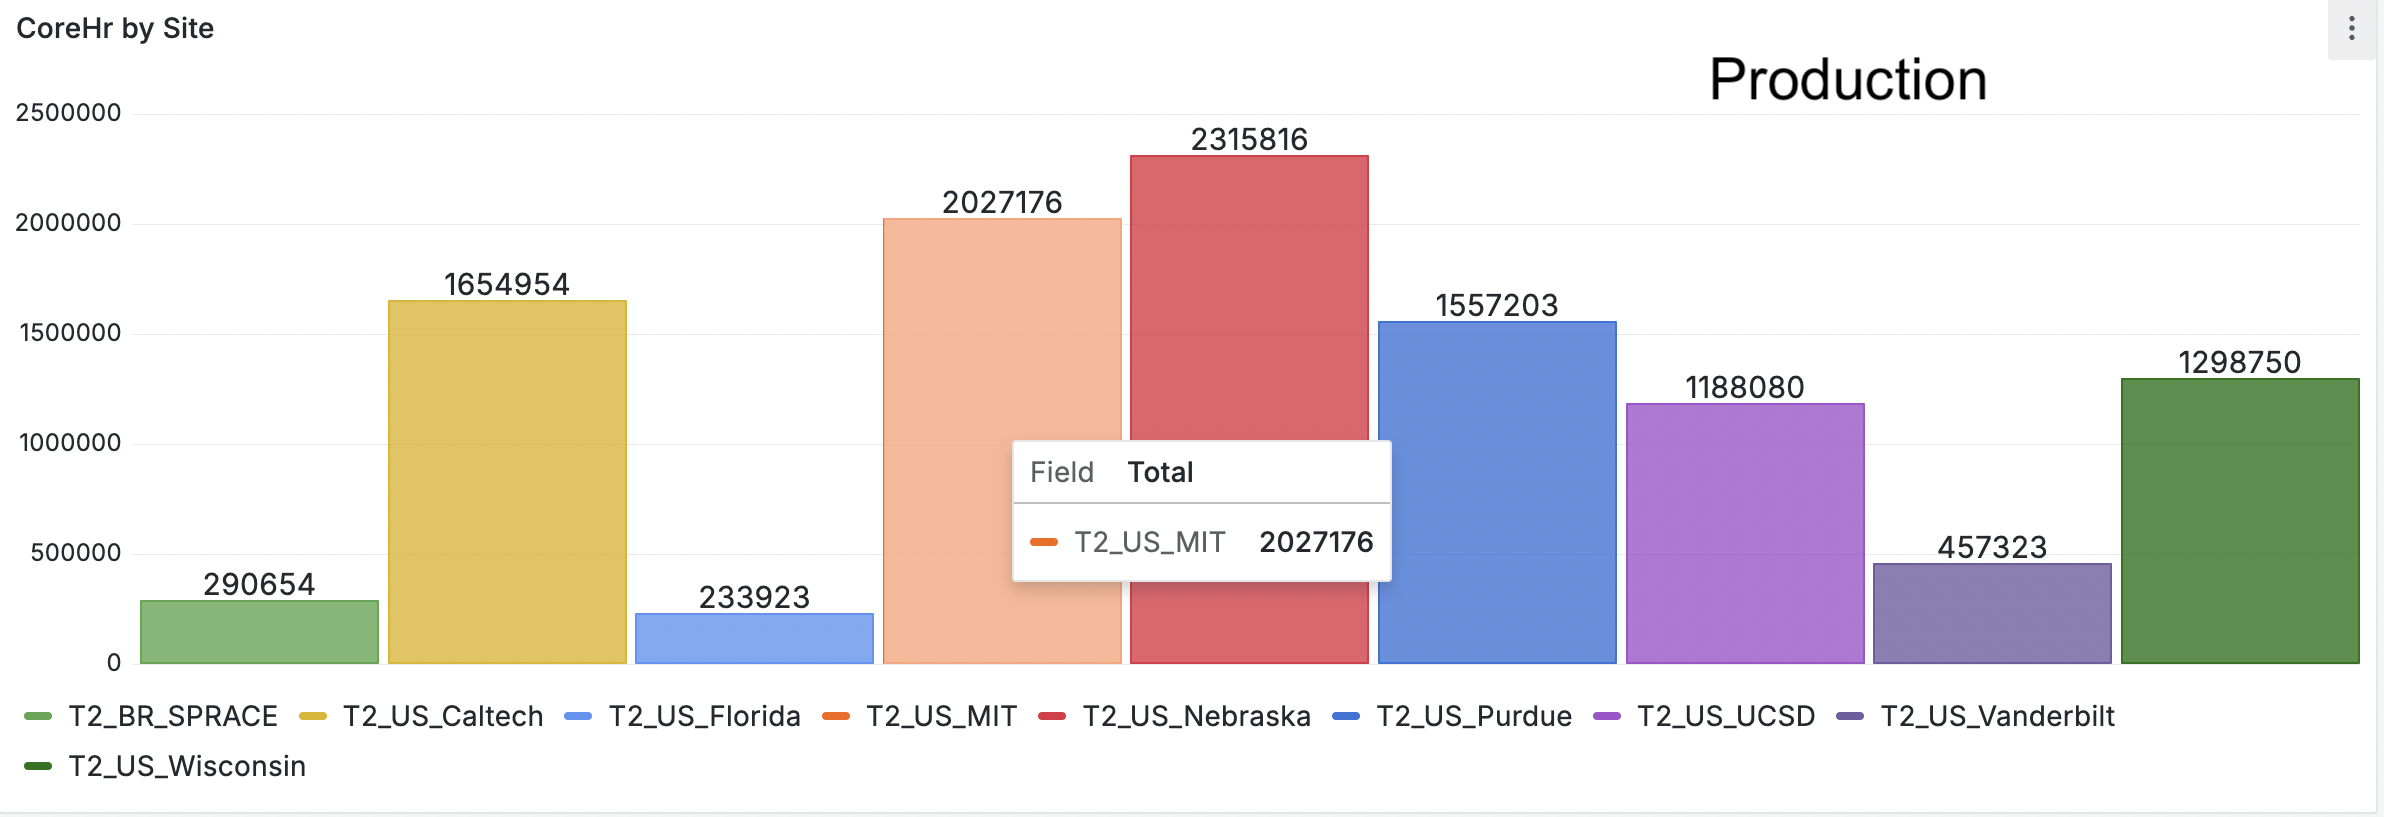
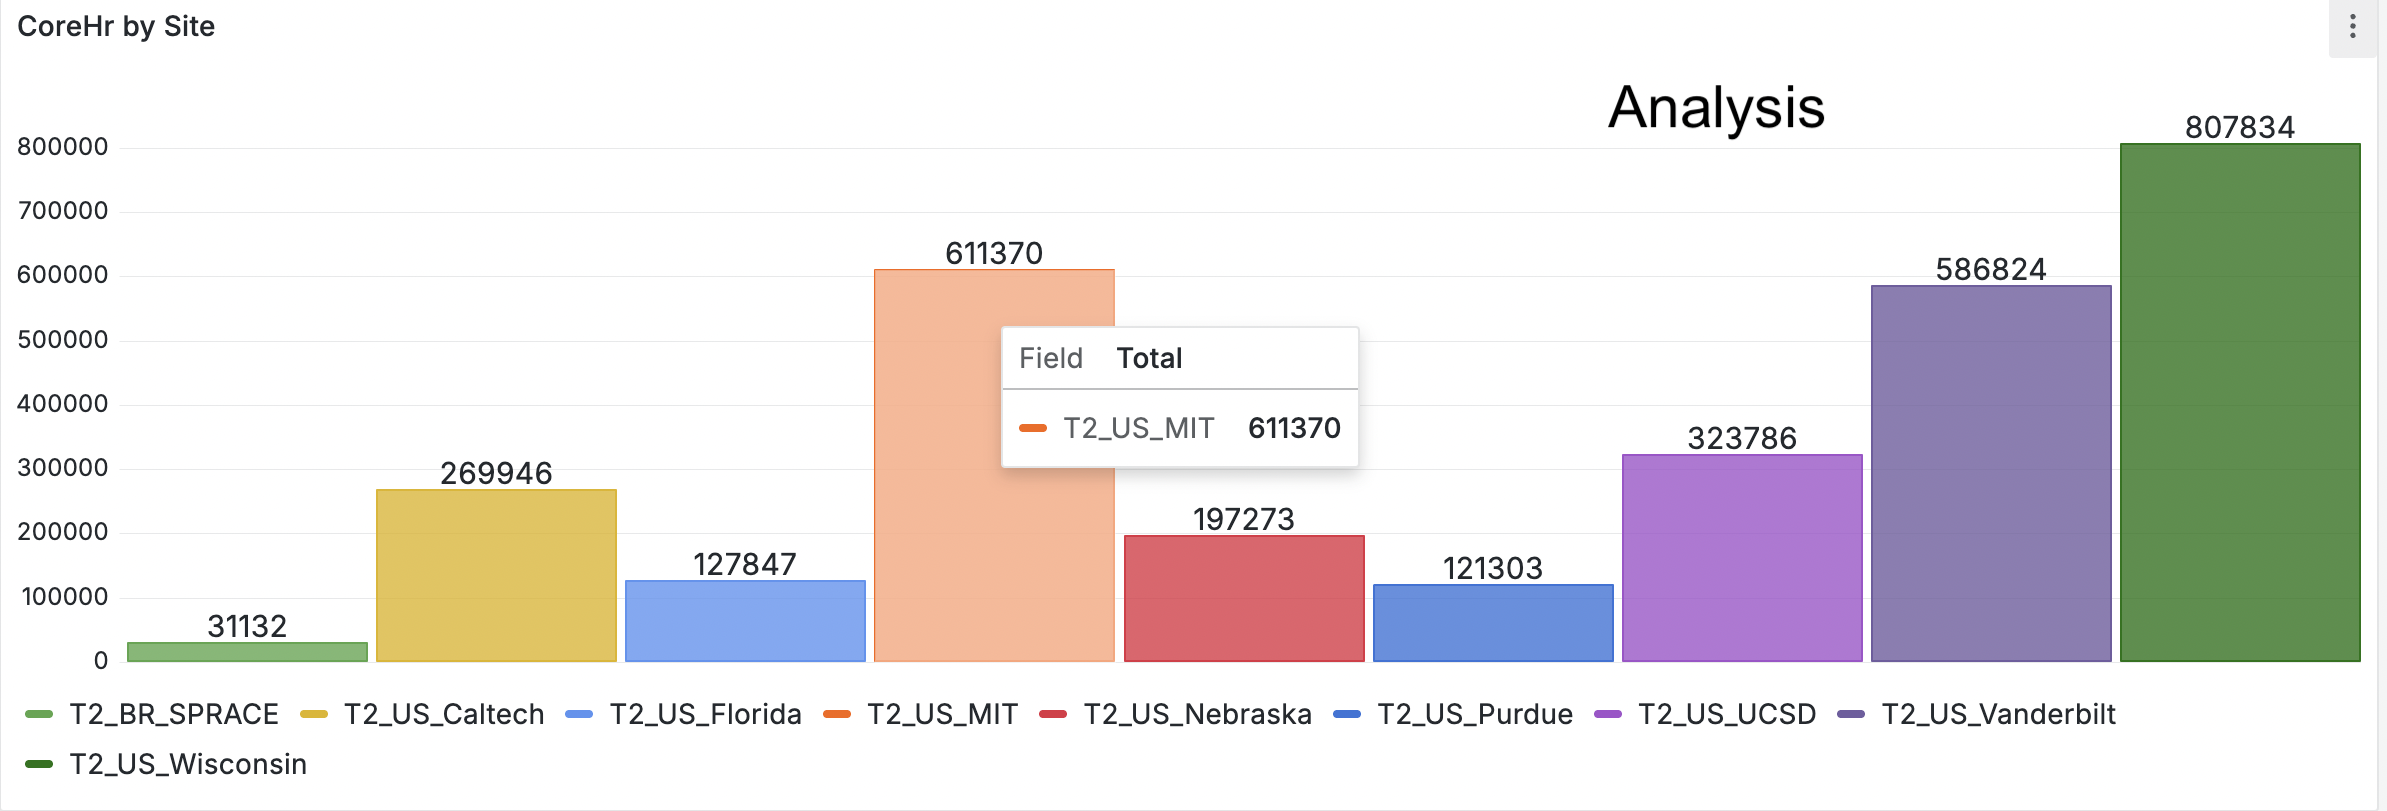
No real issues over last week. Central SAM tests had problems for several days because of CERN GitLab unavailability. The site readiness was corrected to account for that, but SAM tests were not.
Report from September 3, 2025
Our site started to fail SAM tests on XRootD on Tuesday (Sept. 2nd) afternoon. At the moment I do not understand what the issue is, all systems here are responsive and I can’t detect any problems. I am starting to suspect that there is a network problem between us and Fermilab.
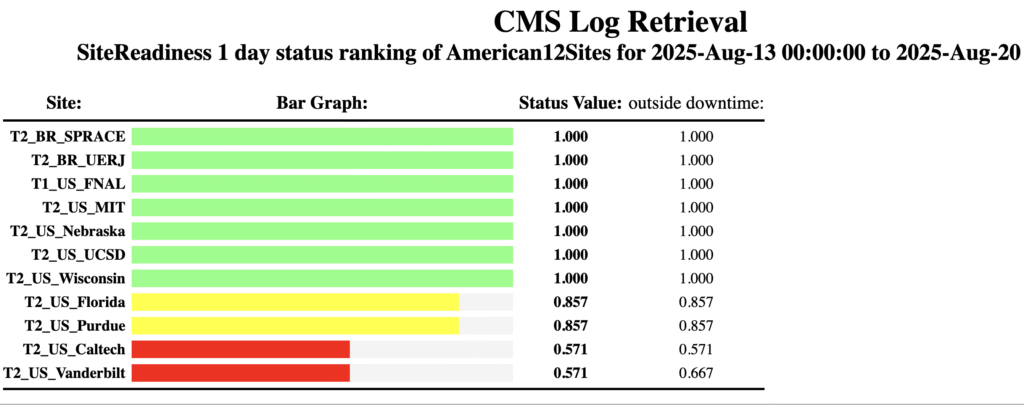
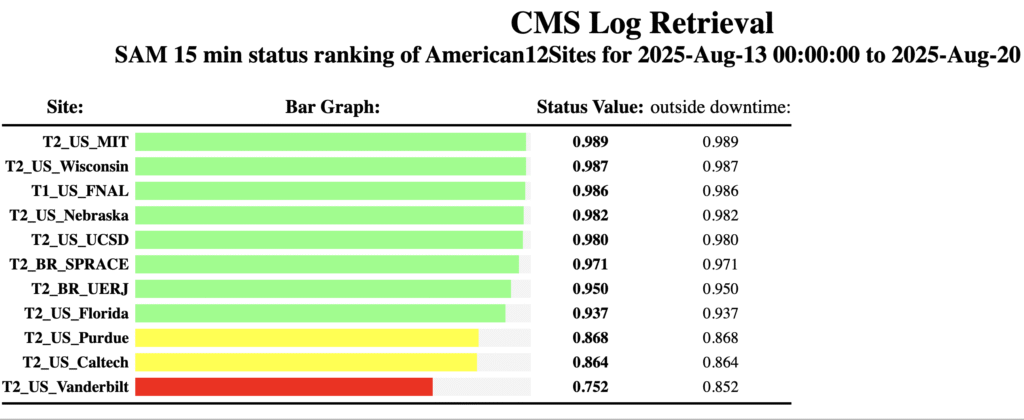
Report from August 20, 2025
SiteReadiness: 100.0%
SAM tests: 98.9%
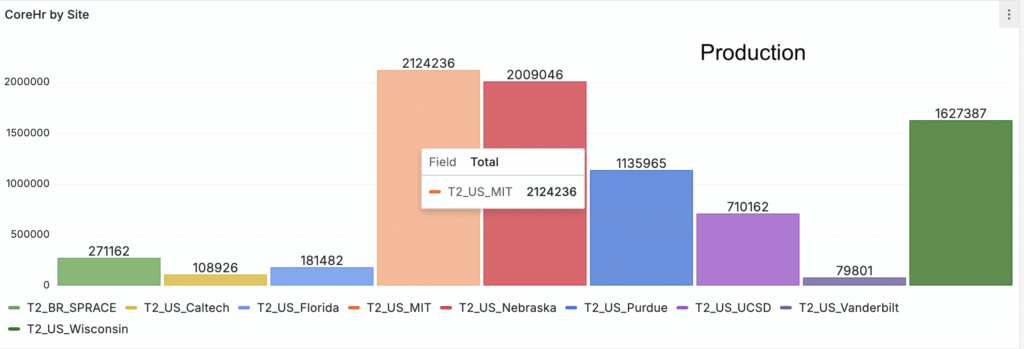
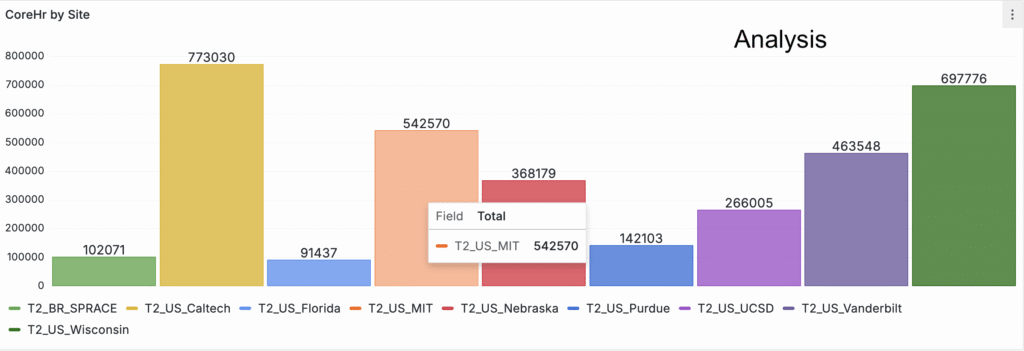
There was a problem with user CRAB jobs caused by CMSSW having problems with davs protocol. I switched our site to root default. Over last 24 hours CMS transferred to us ~600 TBs of data. Today we are scheduled for data challenge tests.
Report from August 6, 2025
SiteReadiness: 100.0%
SAM tests: 99.9%
Overall uneventful week.
Report from July 30, 2025
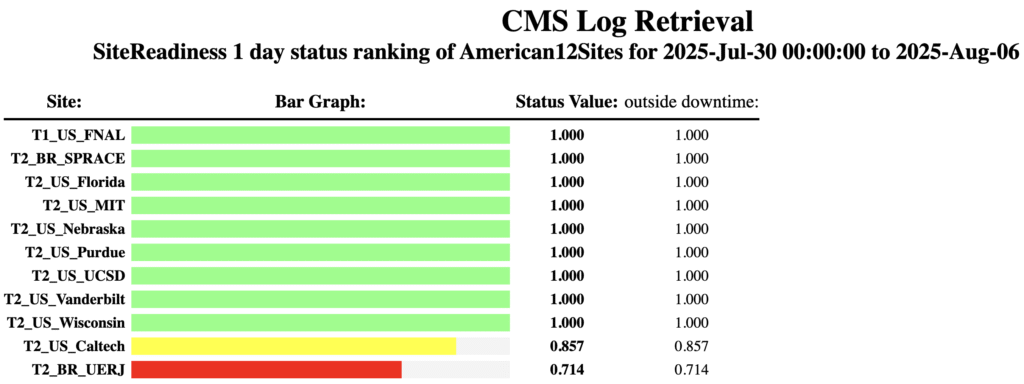
SiteReadiness: 100.0%
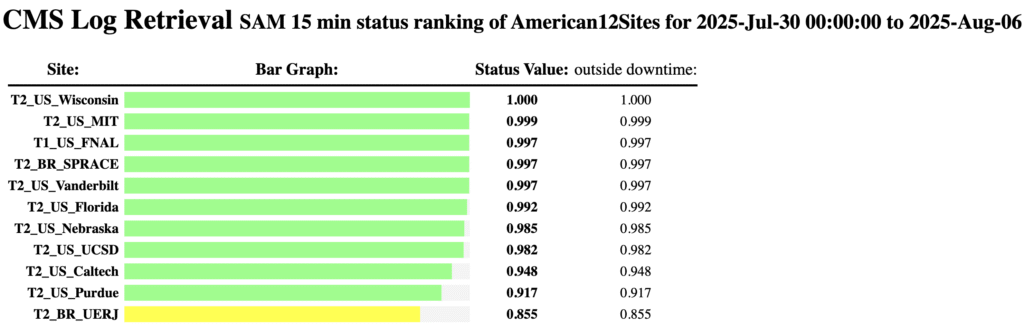
SAM tests: 95.3%
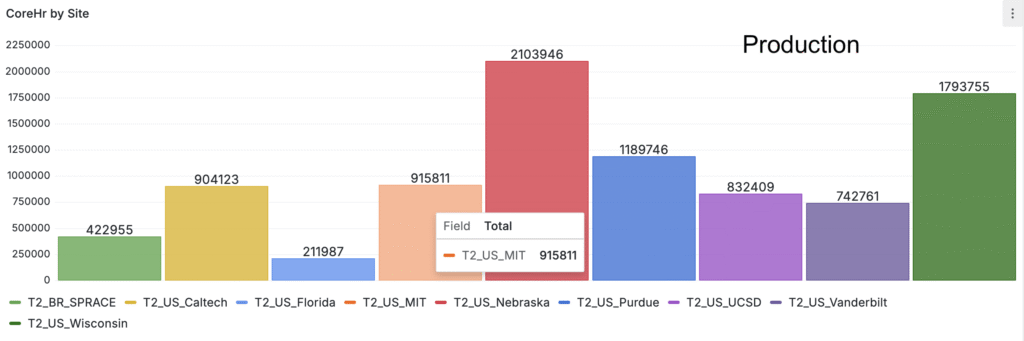
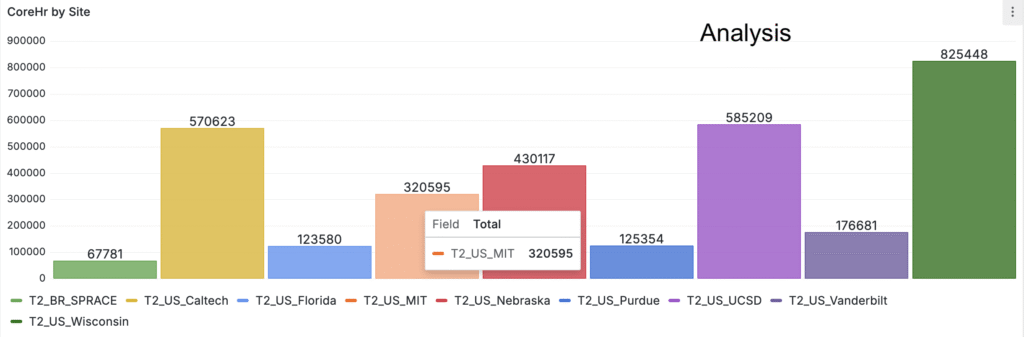
Overall uneventful week. The apptainer misconfiguration was discovered on several WNs, and corrected. We have somewhat low utilization of our site for another week.
Report from July 23, 2025
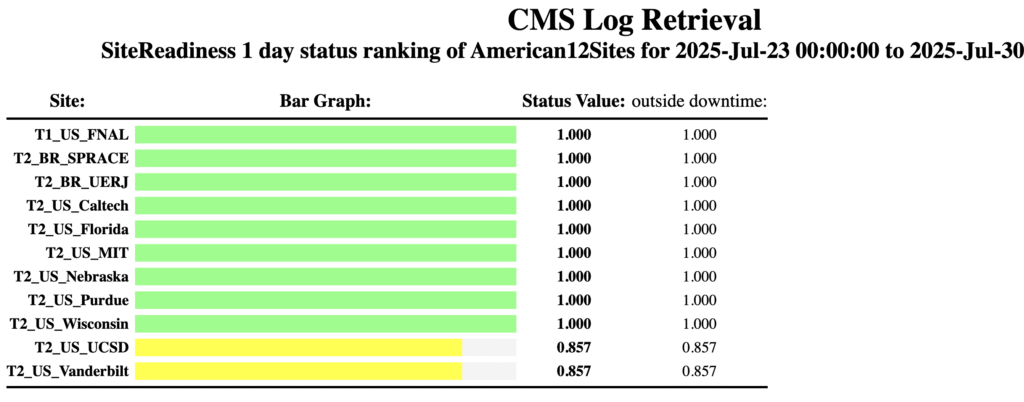
SiteReadiness: 100.0%
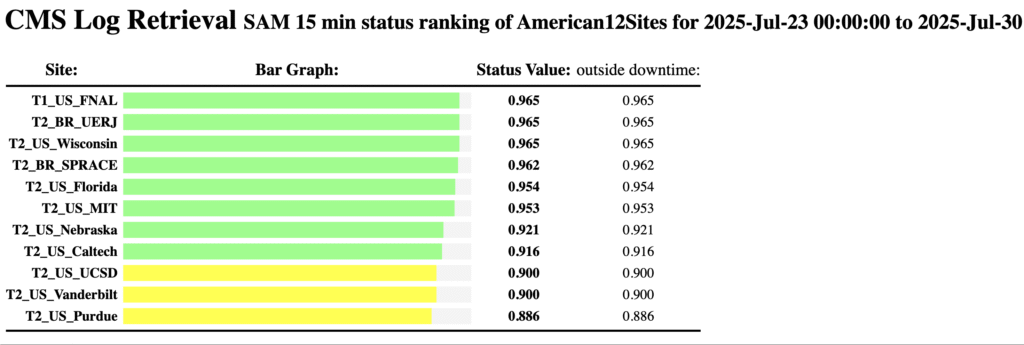
SAM tests: 99.9%
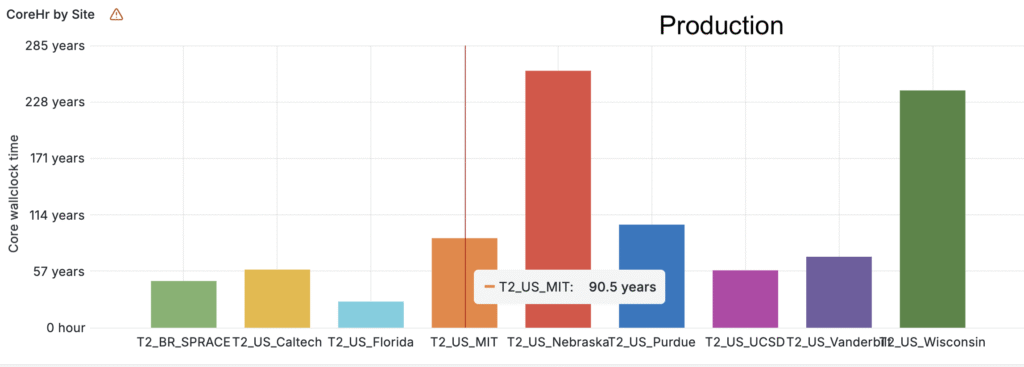
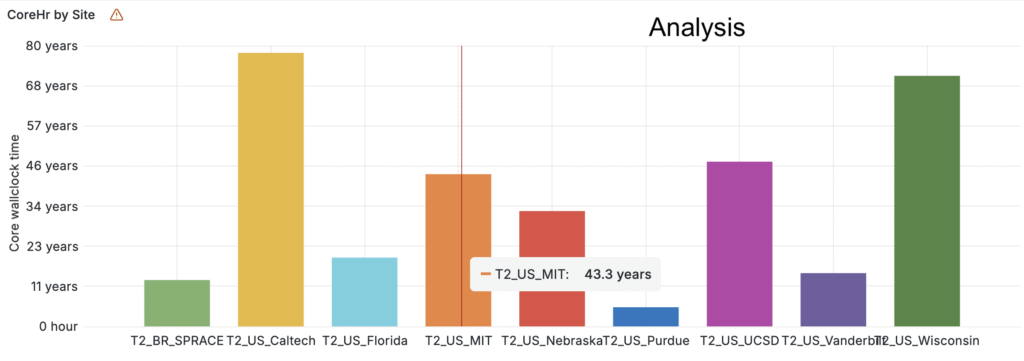
Overall uneventful week. What worries me is low utilization of our site.


Report from July 9, 2025
SiteReadiness: 85.7%
SAM tests: 91.9%
Over the last week we started to have problems with the worker nodes (WNs). Some WNs loose reliable connectivity to the outside world (ping starts showing packet loss), some go offline, and some need to be rebooted. I am not sure what is exactly the reason behind it – CMS jobs; or us offloading data from a lot of HDFS nodes preparing for servers retirement, the activity that saturates networking capability and loads a lot of WNS.


Report from July 2, 2025
SiteReadiness: 100.0%
SAM tests: 98.7%
No significant issues over last week. I switched CRAB area (/store/temp) from HDFS to CephFS, preparing to switch /store/unmerged, and with that all CMS areas will be in CephFS.


Report from June 25, 2025
SiteReadiness: 100.0%
SAM tests: 99.0%
No significant issues over last week. It looks like the storage is synchronized with Rucio. There were no FTS logs indicating that we miss some files or the files have incorrect checksum. Also no such new reports from users came. CephFS storage is sitting at ~74%, I am considering switching CRAB work area from HDFS to CephFS.


Report from June 18, 2025
SiteReadiness: 71.4%
SAM tests: 100.0%
The only issue over the last week, like in the previous week, was FTS errors. Together with DM team we took care of all files that were lost, and of all files that had incorrect check sum. I am monitoring FTS logs to catch cases when a transfer fails because of missing source file, or because of incorrect check sum. So far I have not seen them for three days, I hope that there are no more significant amount of corrupted/missing files in our storage.
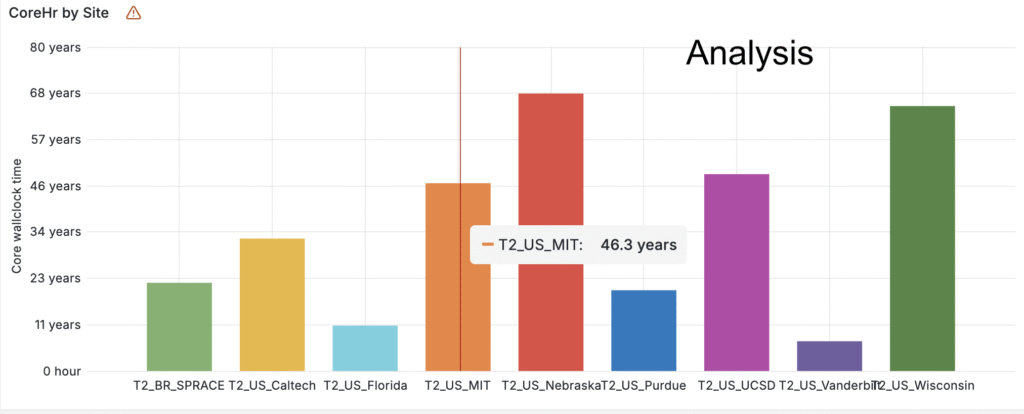
Report from June 11, 2025
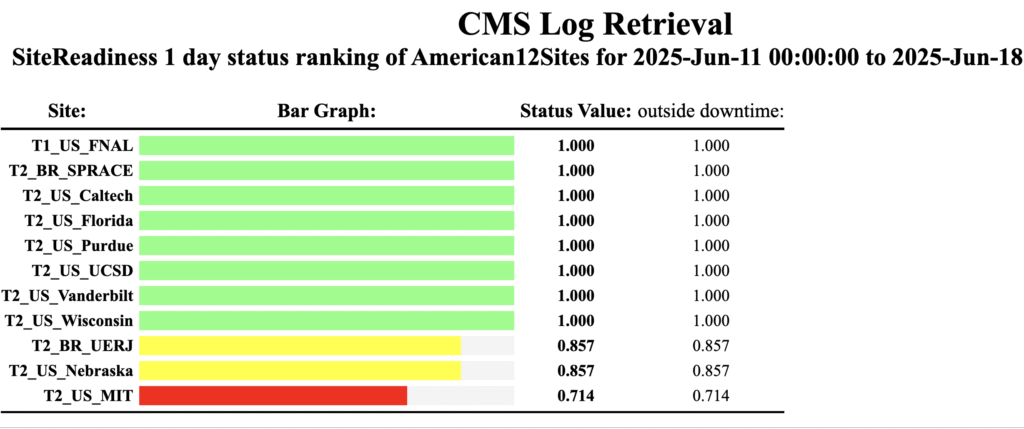
SiteReadiness: 71.4%
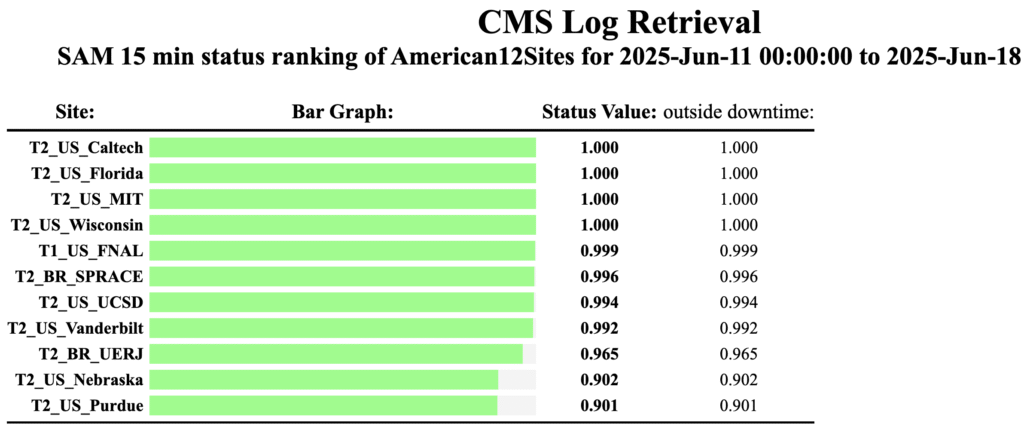
SAM tests: 99.9%
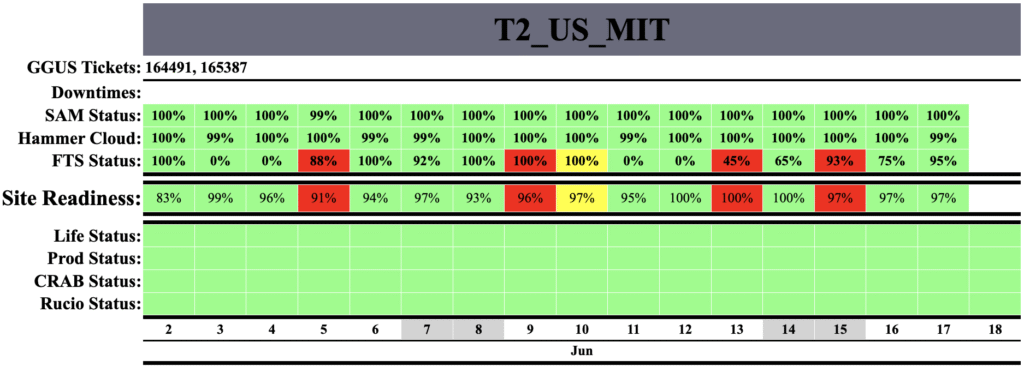
The only issue over the last week is FTS errors. Data Management team transferred all missing files. The remaining item was to take care of files that only existed at our site and were lost. They should have been invalidated globally, but instead DM team invalidated them only partially, as a result FTS kept trying to transfer those files from our storage that are known NOT to exist. DM corrected situation yesterday. The last remaining issue are the files with incorrect checksum that do not exist anywhere else (again FTS is full of requests to transfer them). I hope Site Readiness will be corrected as red days were NOT really caused by bad performance on our end.
Report from May 28, 2025
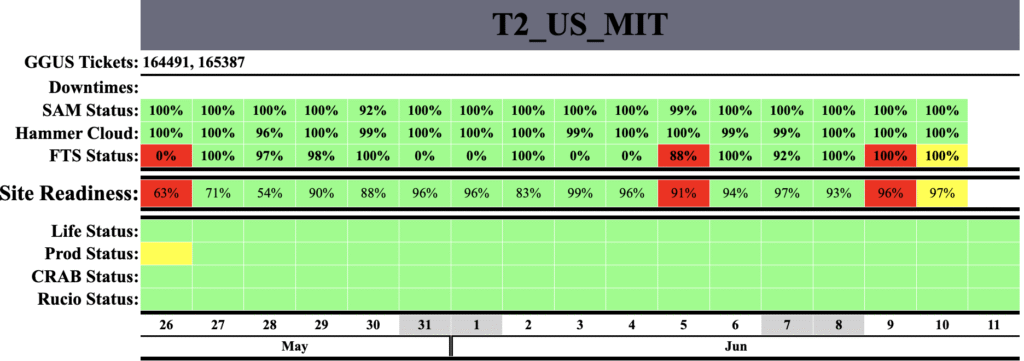
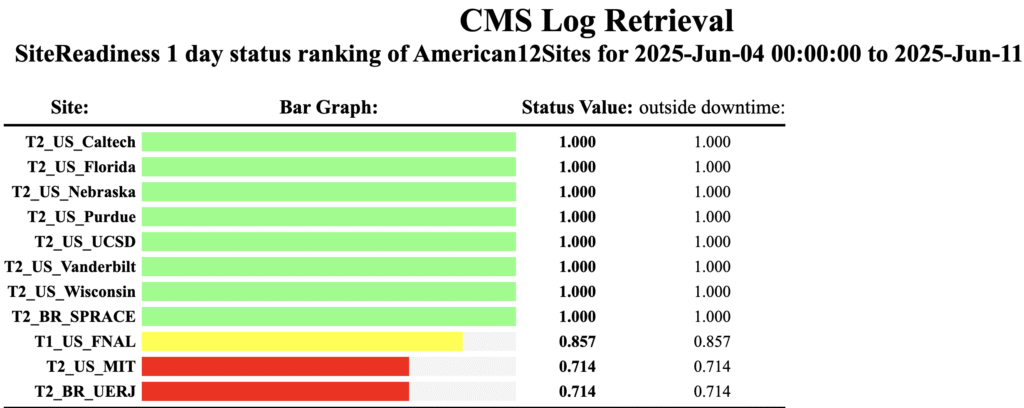
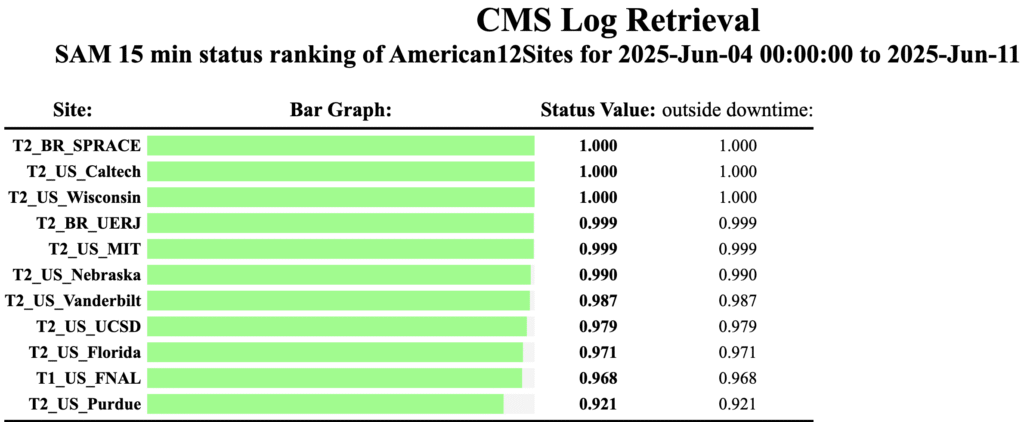
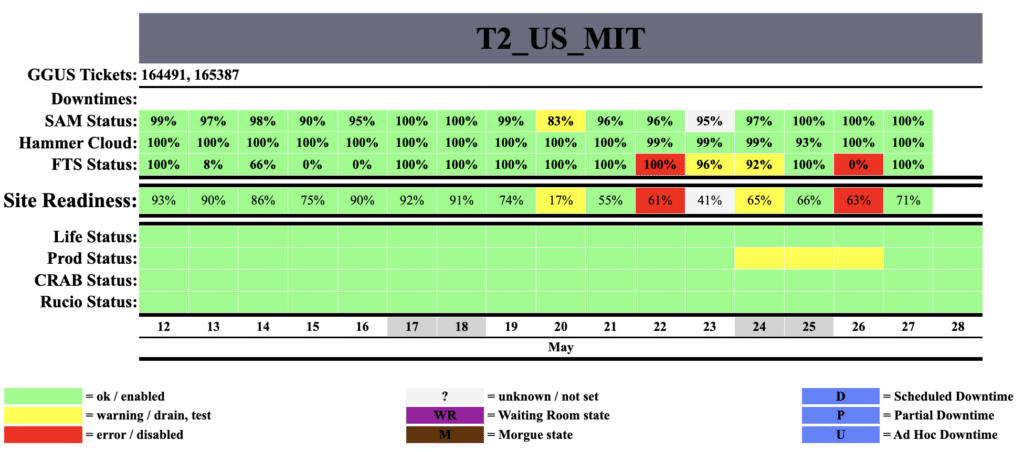
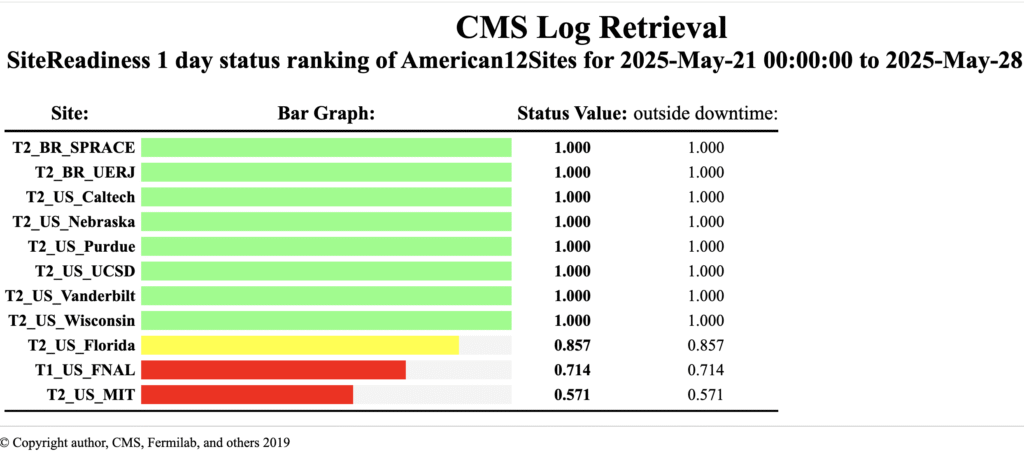
SiteReadiness: 57.1%
SAM tests: 90.3%
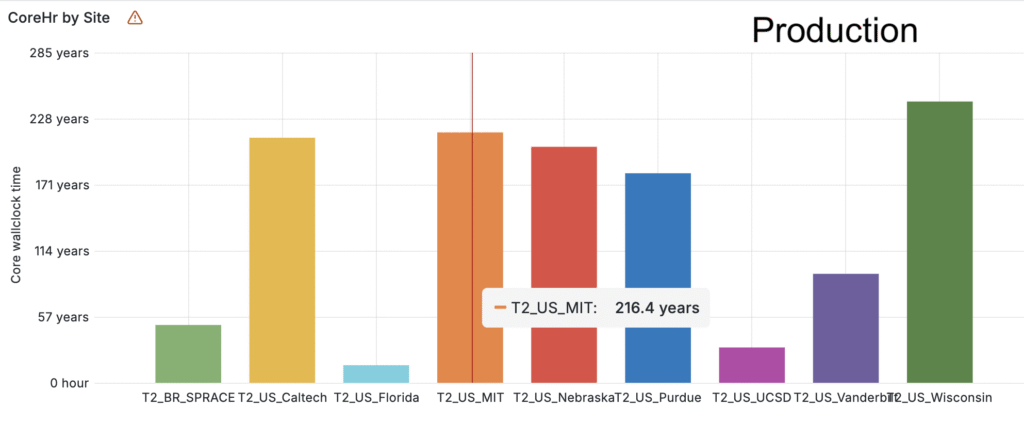
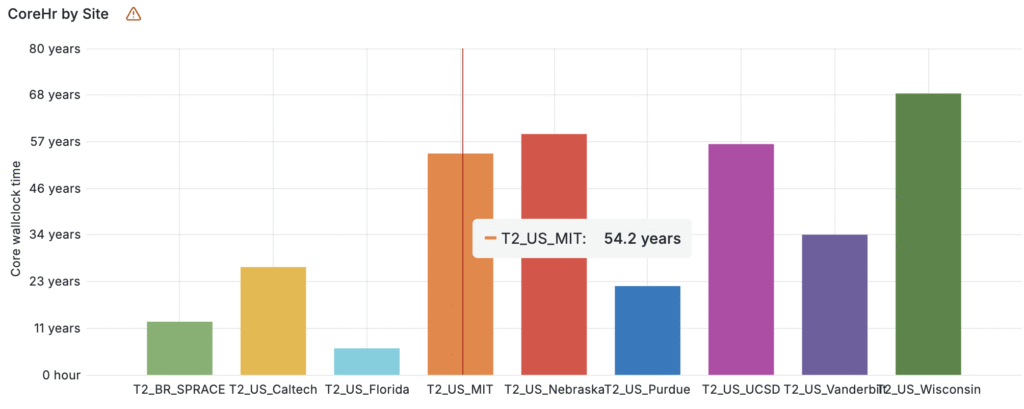
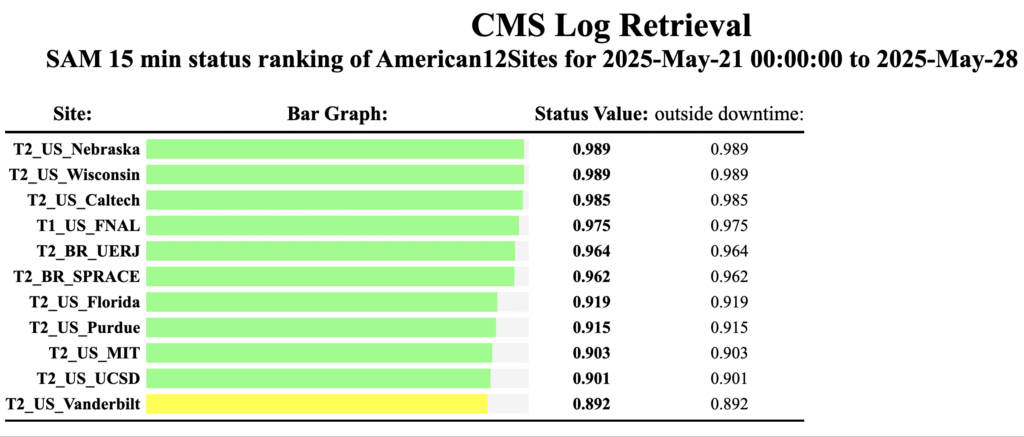
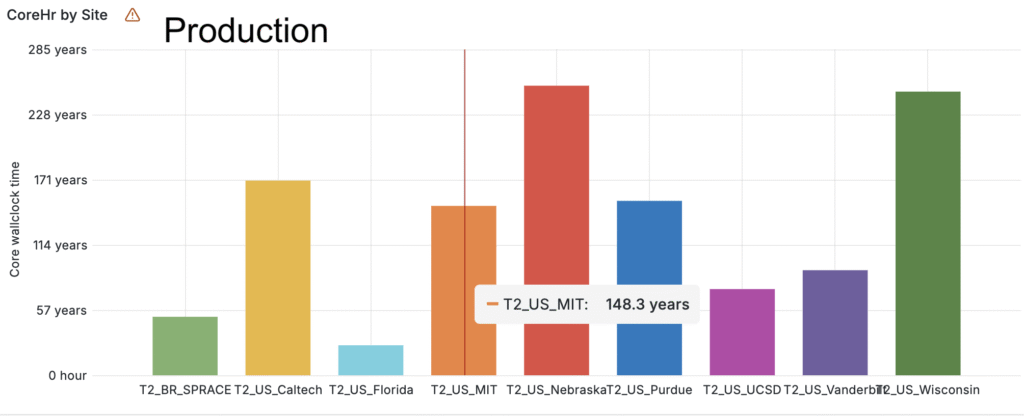
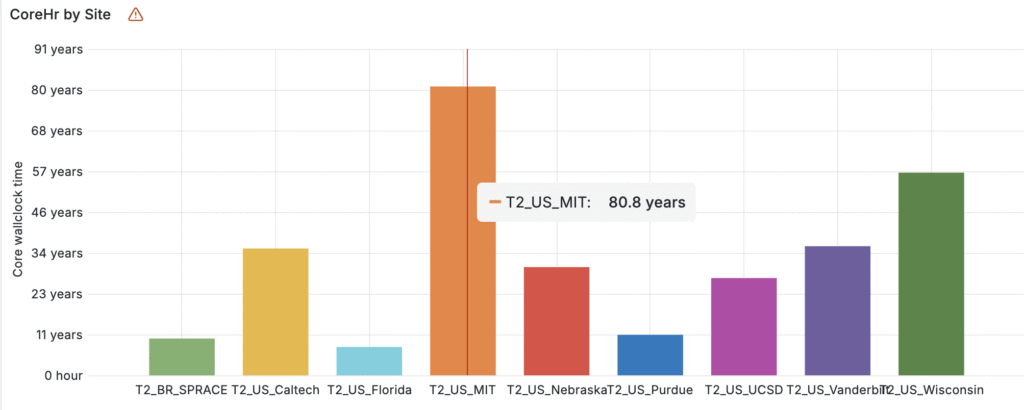
I switched our site configuration on May 22. However, changes were propagated to /cvmfs only on May 27. For several days there was a difference between global and local site configuration. I am not sure if this is the reason behind our site in red for two days in site readiness. I think there is a mistake in site readiness logic, I do not understand how it is possible to have all metrics at 100%, and at the same time to be in red. Also, my eyes and experience tell me that we should fail site readiness for any single day.
Data management team ran CC tests, site storage is fully enabled, FTS is working on making storage consistent with Rucio.
Report from May 21, 2025
SiteReadiness: 100%
SAM tests: 92.2%
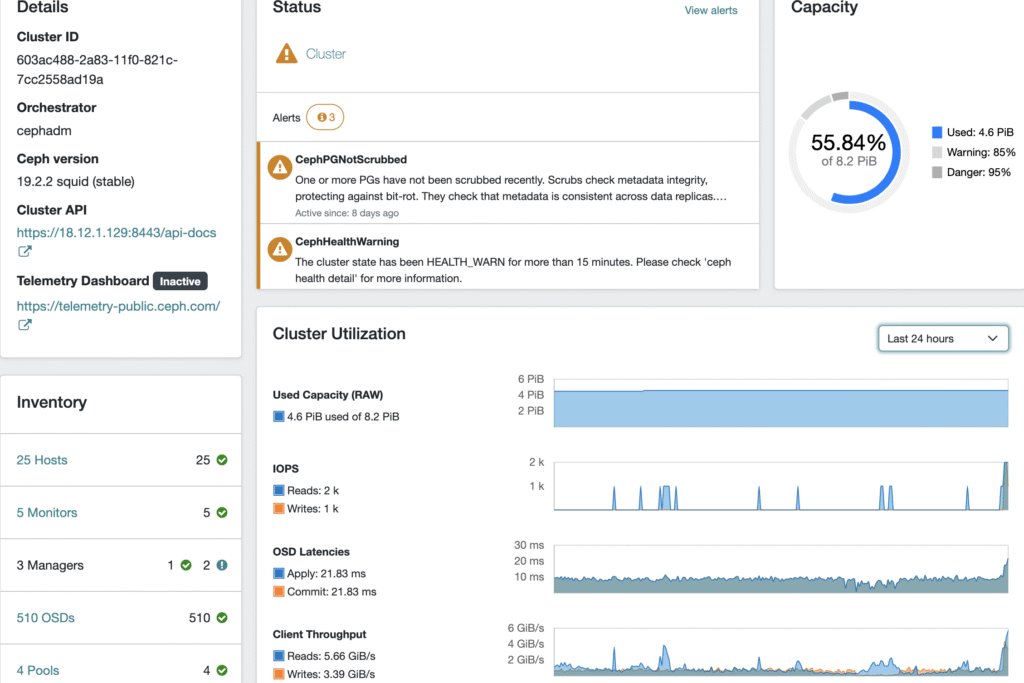
Mostly smooth operations over the last week. Almost finished with pushing data (what can easily be copied) into CephFS. However, there will be a couple of hundred thousand files missing, mostly in /store/mc, because I suspect those files are only available on tape and my tools are very inefficient transferring those files.
I will switch mostly to CephFS this Thursday. Three directories – /store/user, /store/temp, and /store/unmerged – will stay in HDFS for now. I plan to ask DM team to run consistency check and submit FTS requests that will make CephFS storage consistent with Rucio expectations.
Report from May 14, 2025
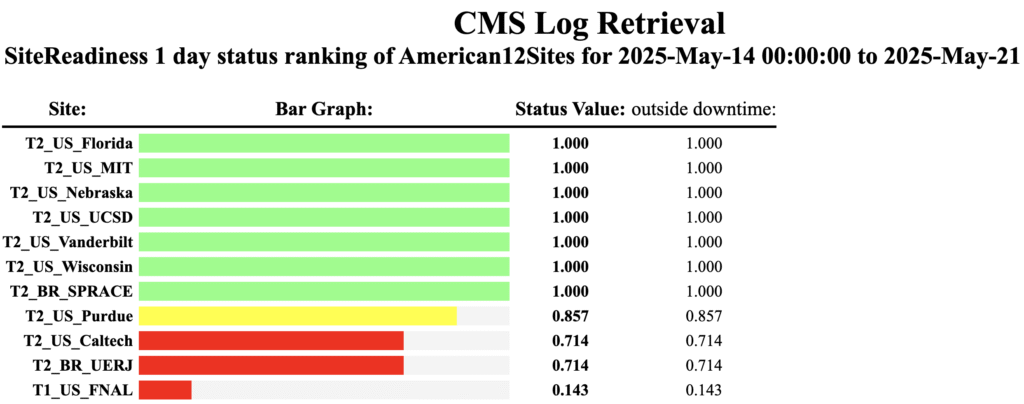
SiteReadiness: 100%
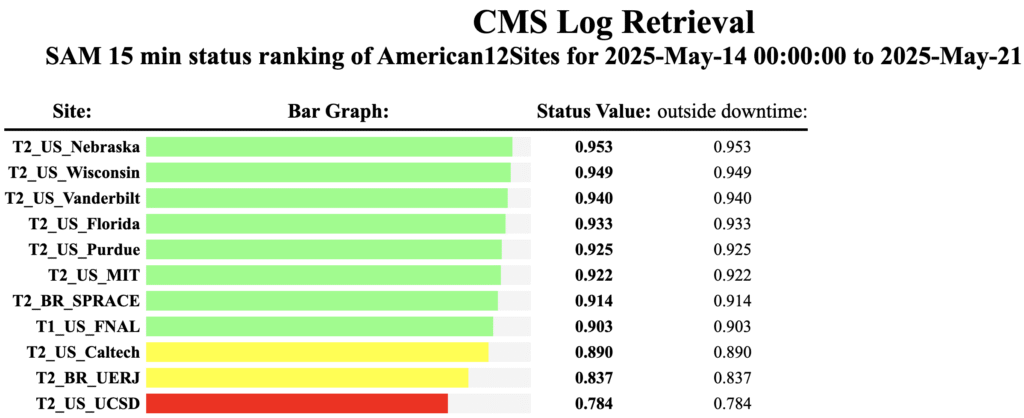
SAM tests: 95.4%
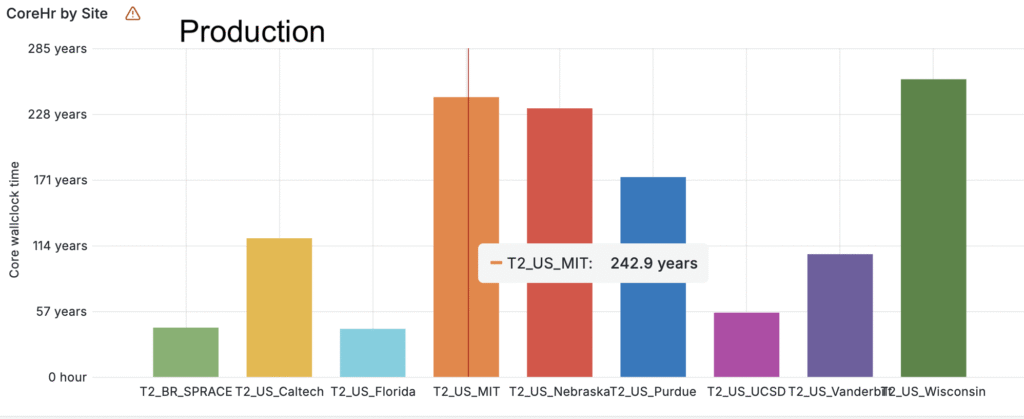
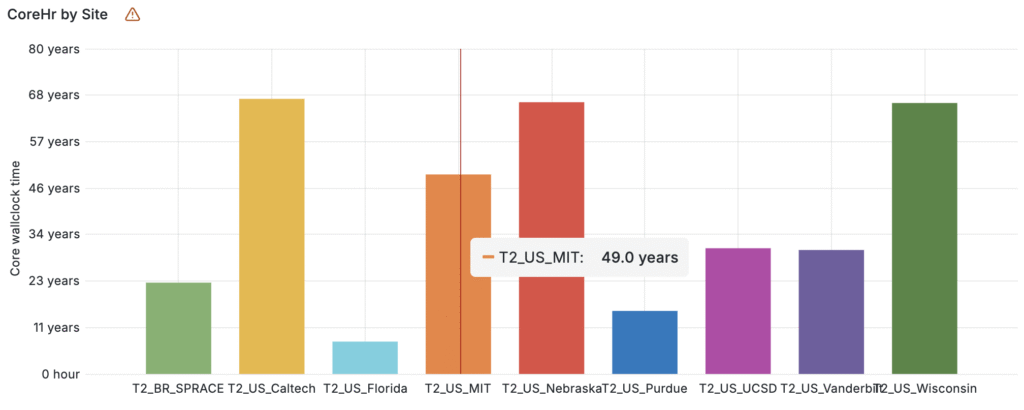
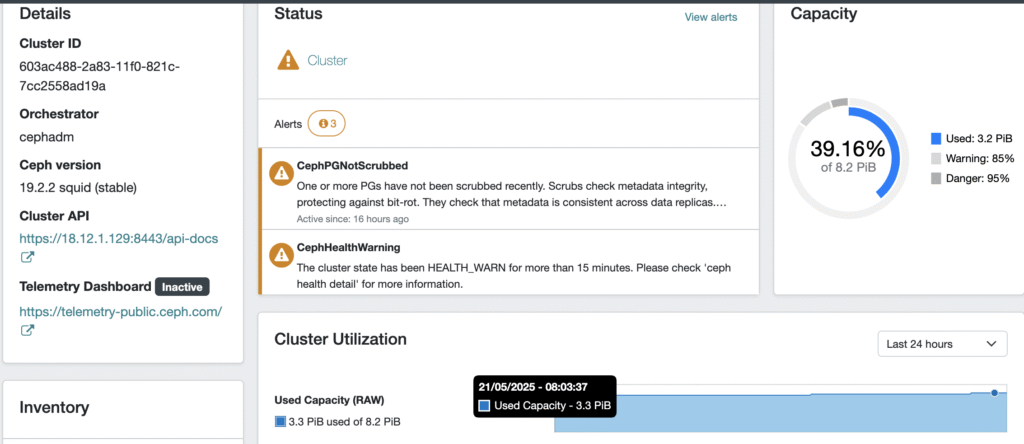
We had smooth operations over the last week. We wiped out previous CephFS deployment and bootstrapped a new cluster last Tuesday. While doing it, SAM tests turned red for several hours while new file system was unavailable; as a result SiteRediness for that day was in red, and our sire was briefly put into the waiting room.
Once CephFS was redeployed we started to push data into it. At the moment we have transferred /store/himc, /store/hidata, and ~70% of /store/mc. Also started copying of /store/data. At the peak we can push ~400 TB into CephFS. We expect this activity will be completed this weekend. At that moment we will switch our site configuration to mostly use CephFS. However, we plan to rely on old HDFS for /store/user, /store/temp, and /store/unmerged.
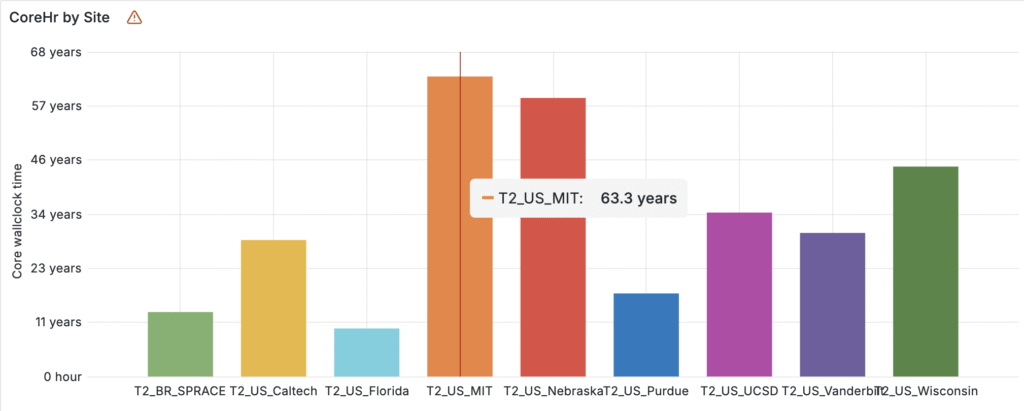
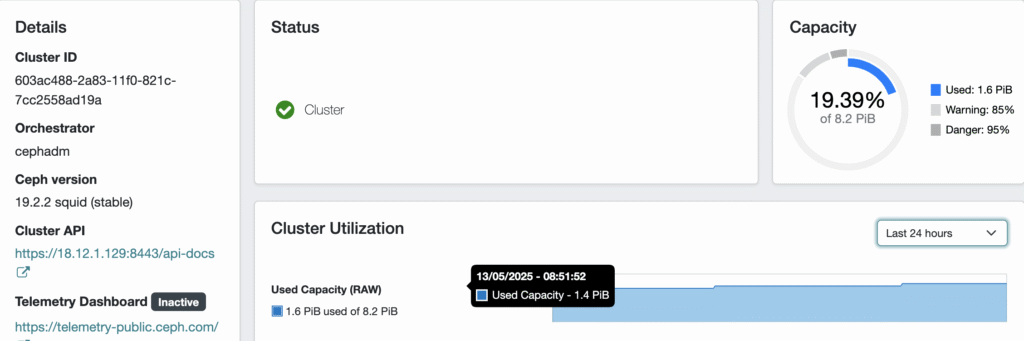
Report from May 7, 2025
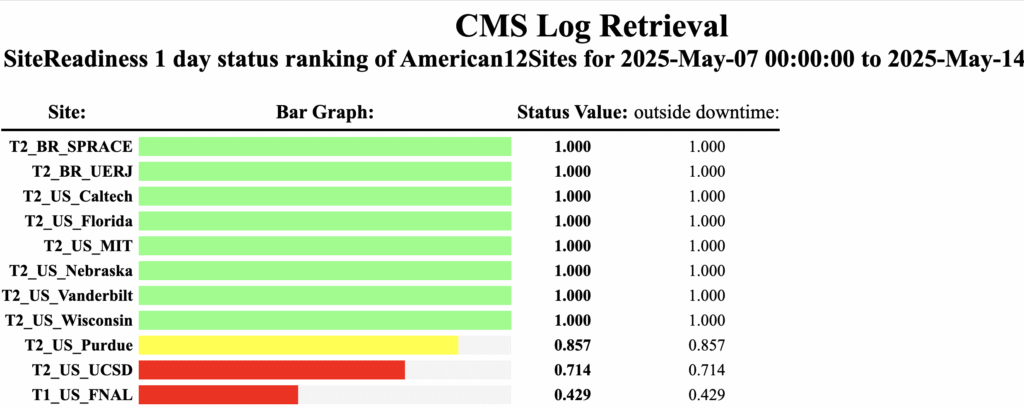
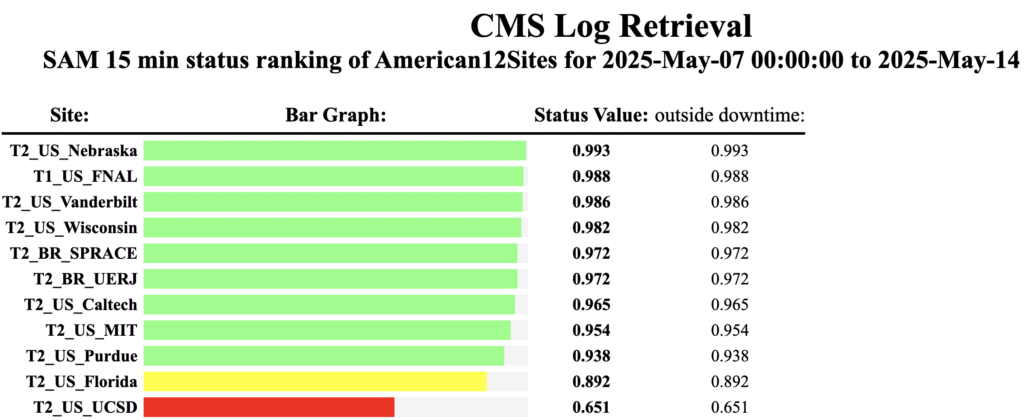
SiteReadiness: 57.1%
SAM tests: 74.4%
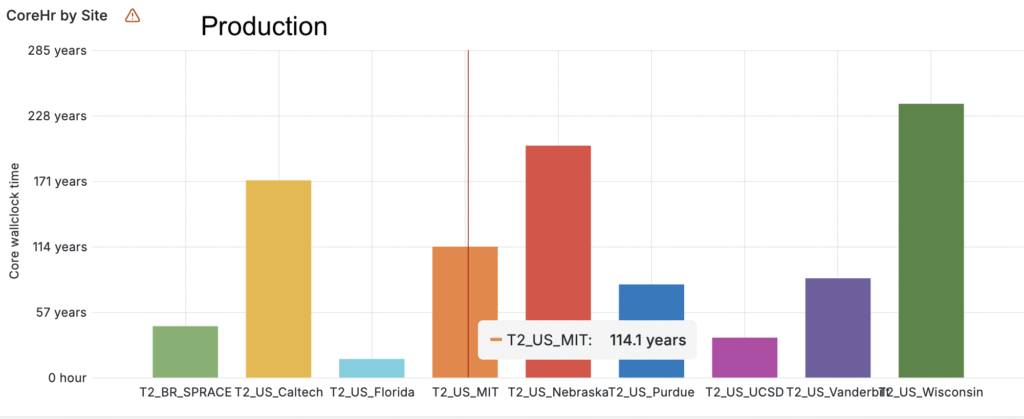
Last week we tried to optimize our new CephFS file system. This ended up in unexpected CephFS behavior, at the end it put itself in read only mode. For several days we tried to understand how to fix the problem and repair CephFS. At the end this week we came to a conclusion that the problem is probably not fixable. We attempt one suggestion that we found, however, as expected, it resulted in all metadata lost. At that moment on Tuesday I wiped out old system and bootstrapped new CephFS installation, and started to transfer data into it (at the moment /store/mc). So far I pushed ~150 TB in one day. If CephFS remains stable I will increase the rate. My estimate is that I should be able to transfer ~400 TB in one day.
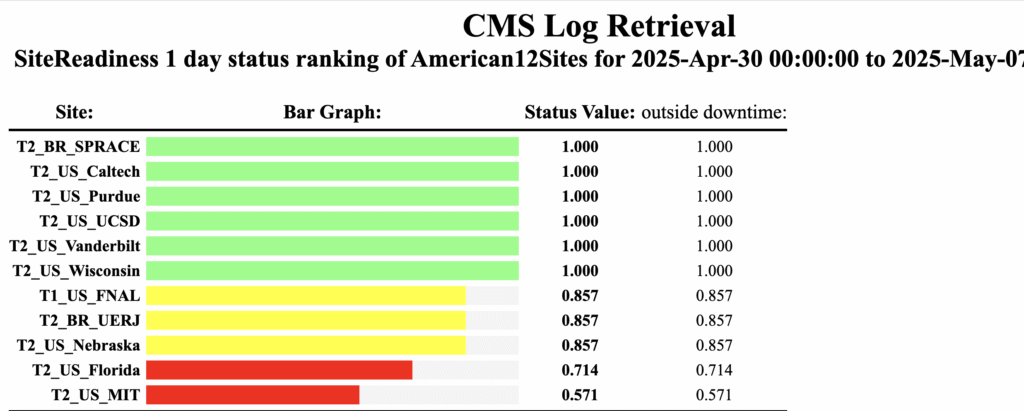
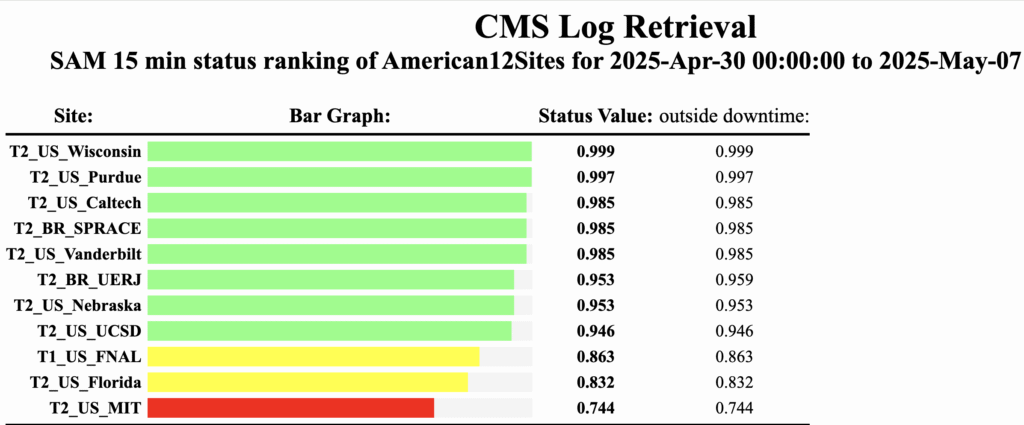
Report from April 23, 2025
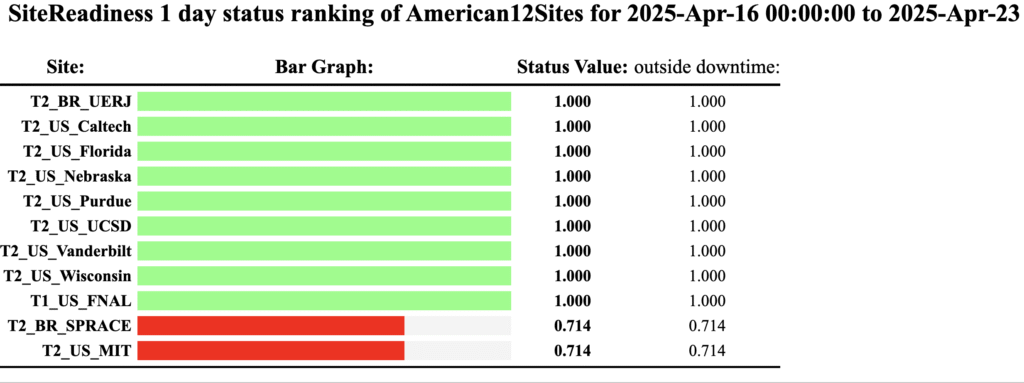
SiteReadiness: 71.4%
SAM tests: 91.8%
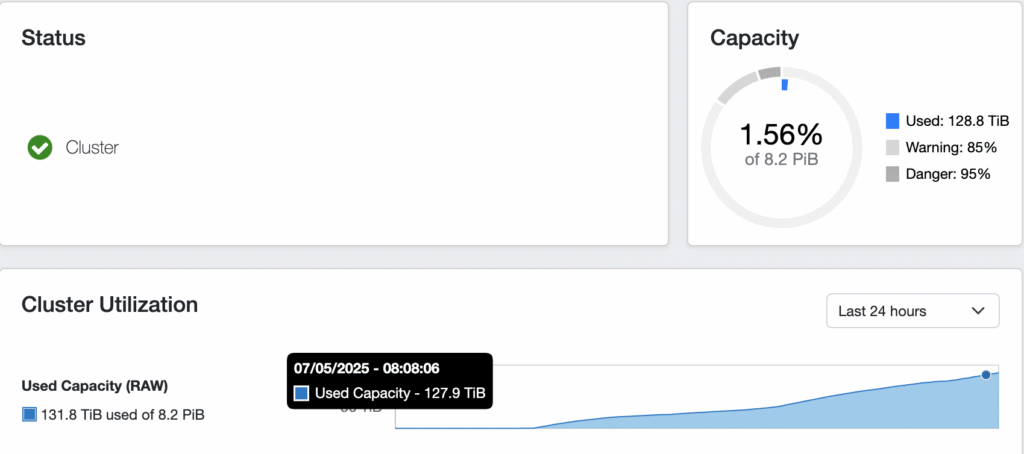
We were adding for the first time more disks into one of the storage nodes. Now I have realized that it should have been done differently. As a result of erroneous procedure one of the disks reached full state, and CephFS put itself into read only state. This affected our availability for two days. I asked Rucio team to put us in read only mode until CephFS balances disks. I also had to stop transferring data from HDFS into CephFS. I see that disk usage slowly getting even, but it is taking very long time.
Report from April 16, 2025
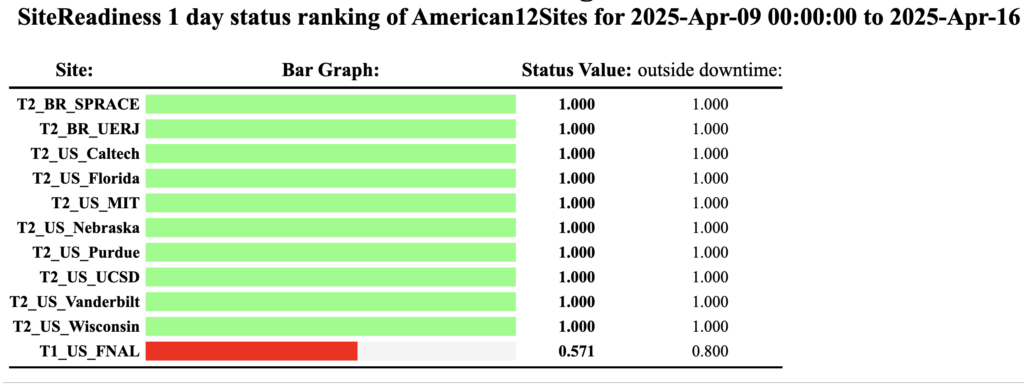
SiteReadiness: 100%
SAM tests: 97.3%
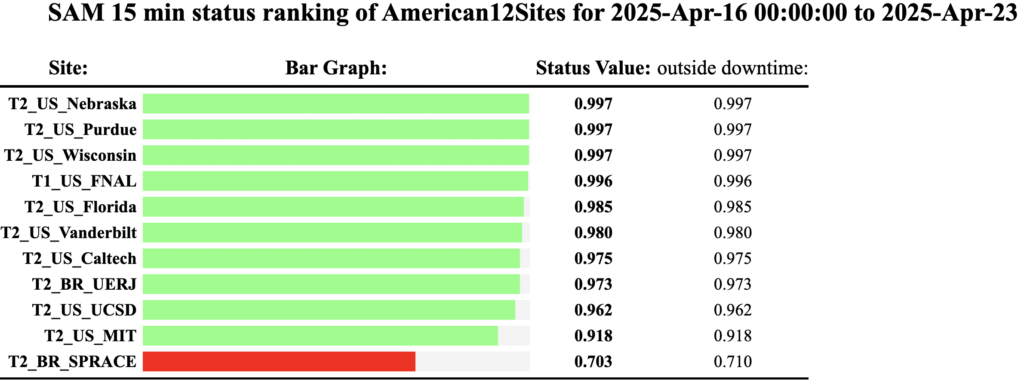
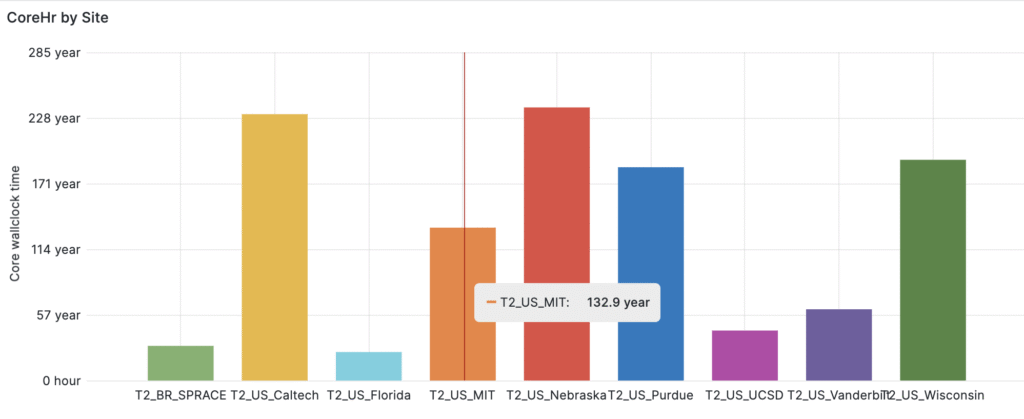
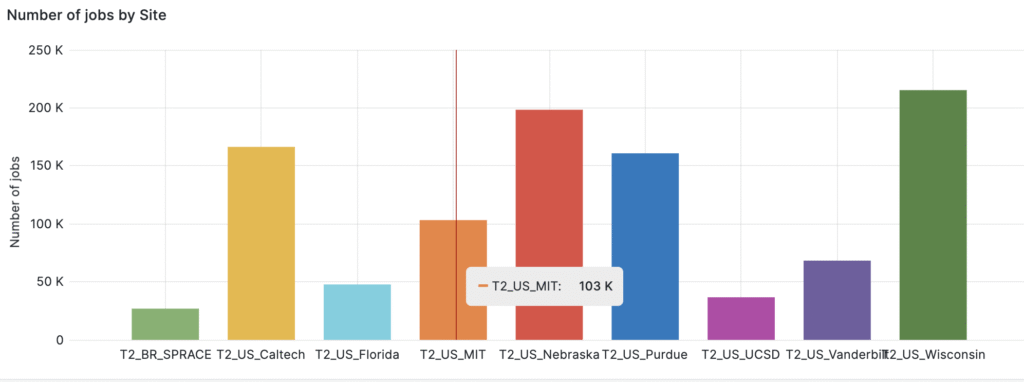
Over the last week we had a problems with some test held. Most inefficiency comes from HammerCloud tests. On Tuesday we restarted xrootd after adjusting read permissions for general CMS users. We had a report of some files in CephFS corrupted. At the moment we think corruption happened upstream and file was transferred to already with a problem (and the issue is not unique to our site).
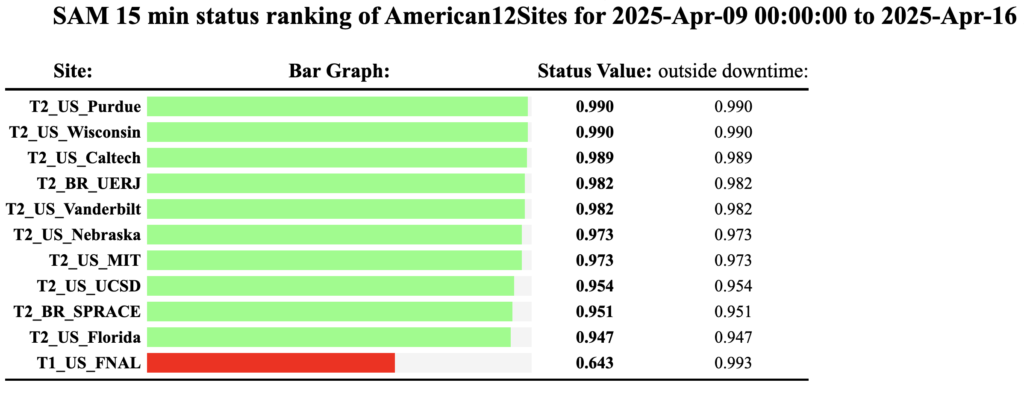
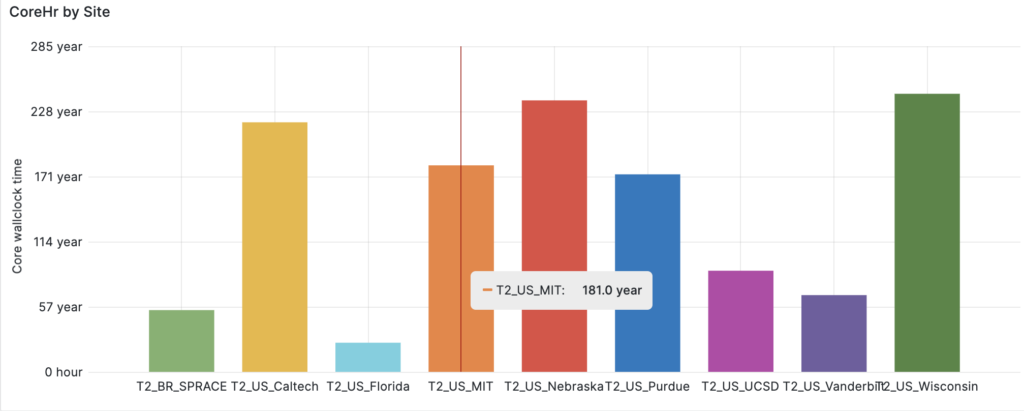
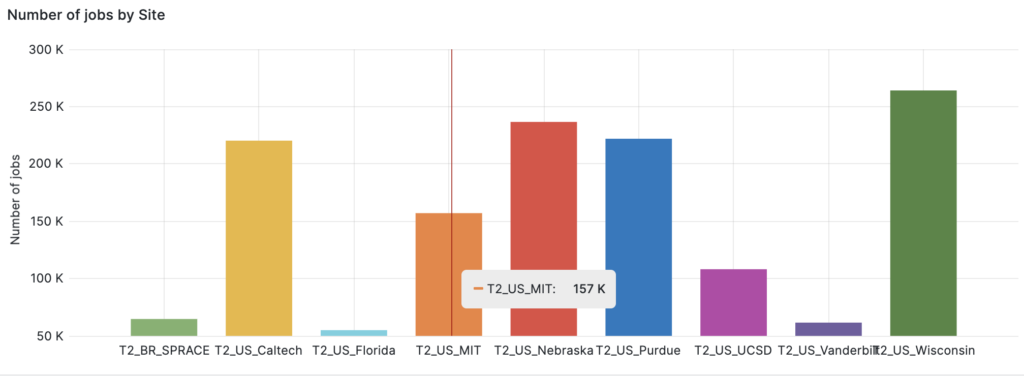
Report from April 9, 2025
SiteReadiness: 100%
SAM tests: 99.3%
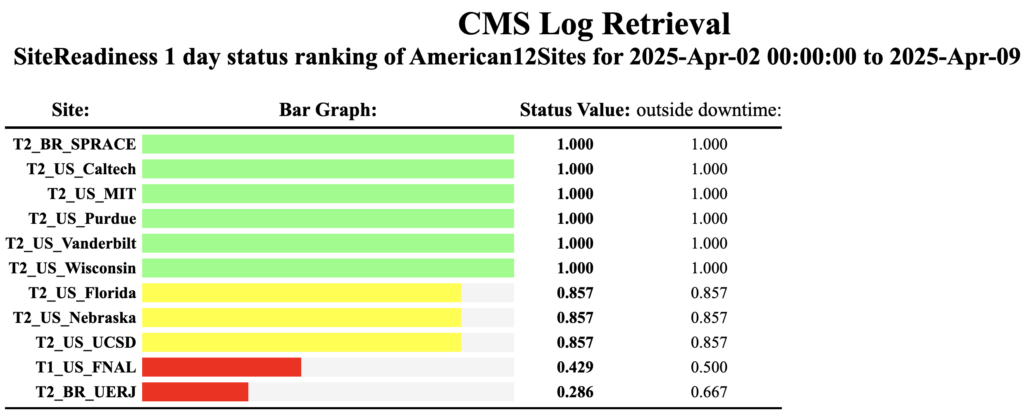
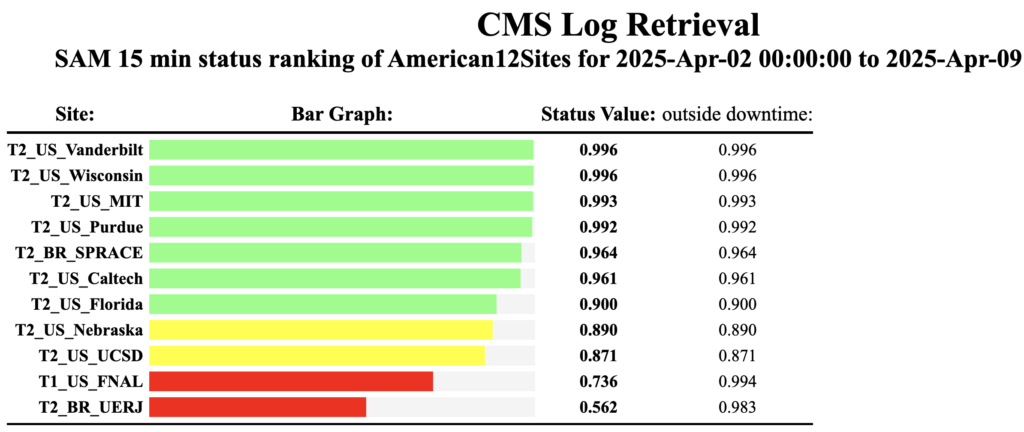
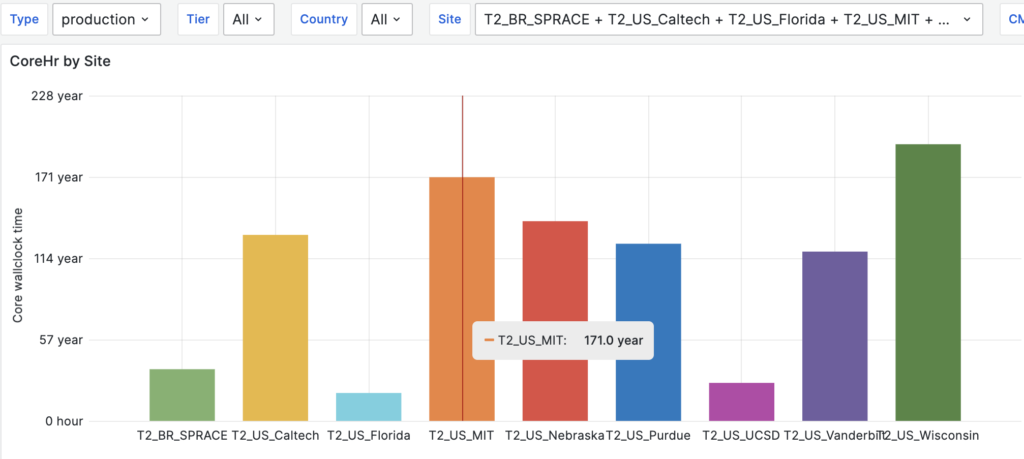
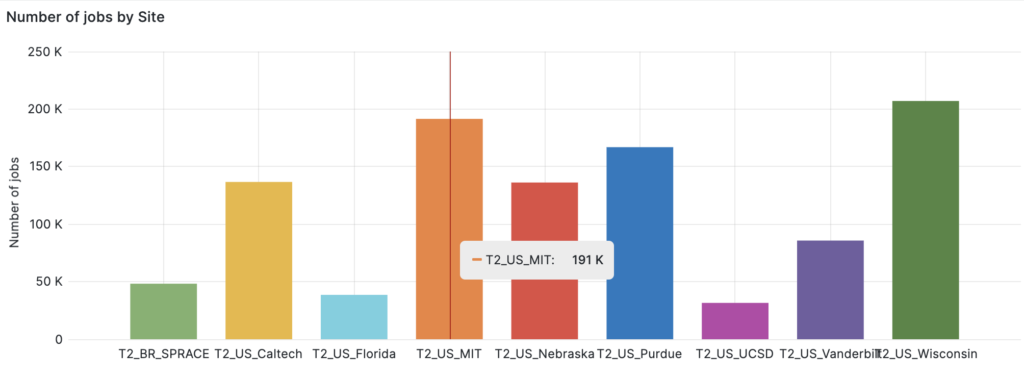
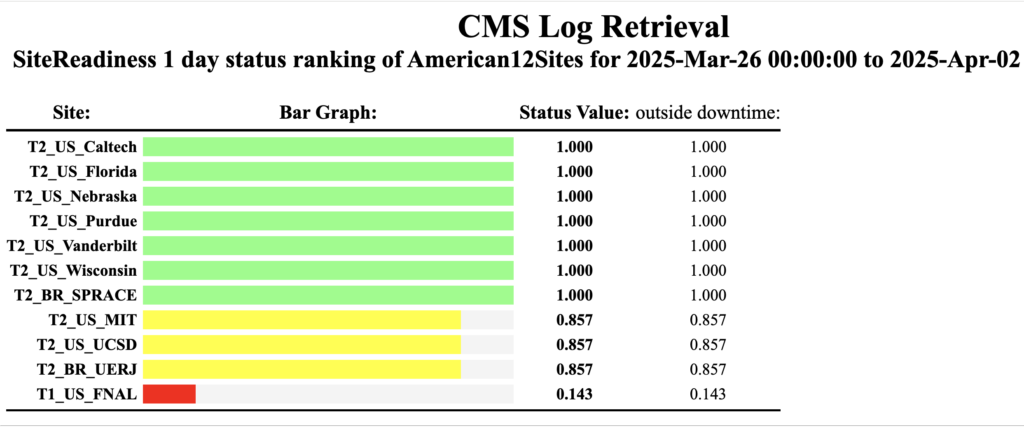
Report from April 2, 2025
SiteReadiness: 75%
SAM tests: 85.6%
We had a power outage (reported below). Because of that our metrics are low for the reported time period.
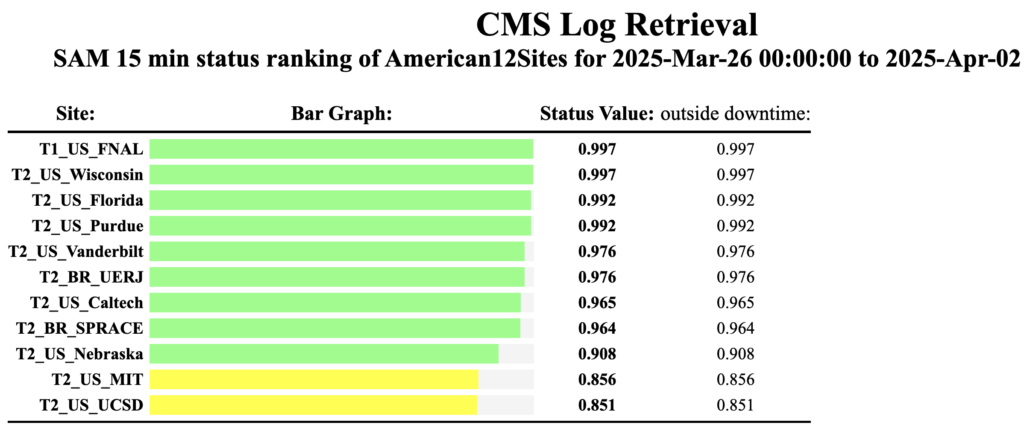
Report from March 31, 2025
We had a power outage that started on Saturday morning and lasted for several hours. As a result our Tier2 was not available to run jobs for 24 hours. CephFS storage system stayed online and was available right after the power outage was over and the network became available. Tape storage was fullu available during the outage.
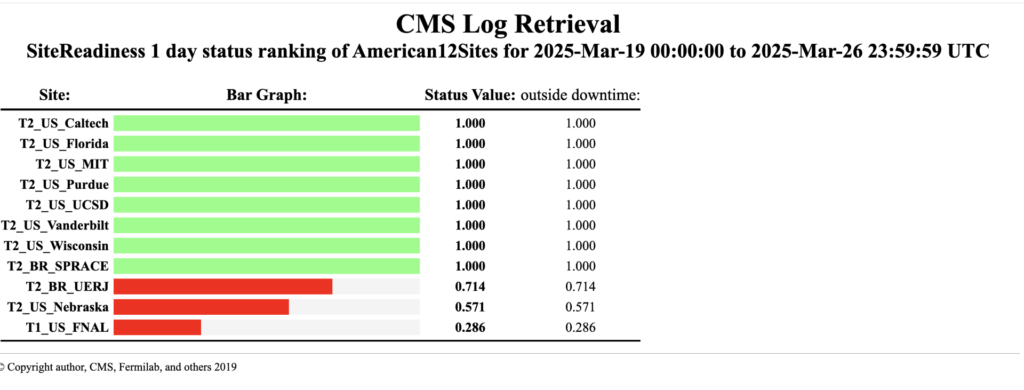
Report from March 26, 2025
SiteReadiness: 100%
SAM tests: 98.7%
No major issues over last week. No new tickets were opened. The only thing that comes to mind is that I was asked to make sure that 3 datasets in /storage/data are fully available in CephFS storage.
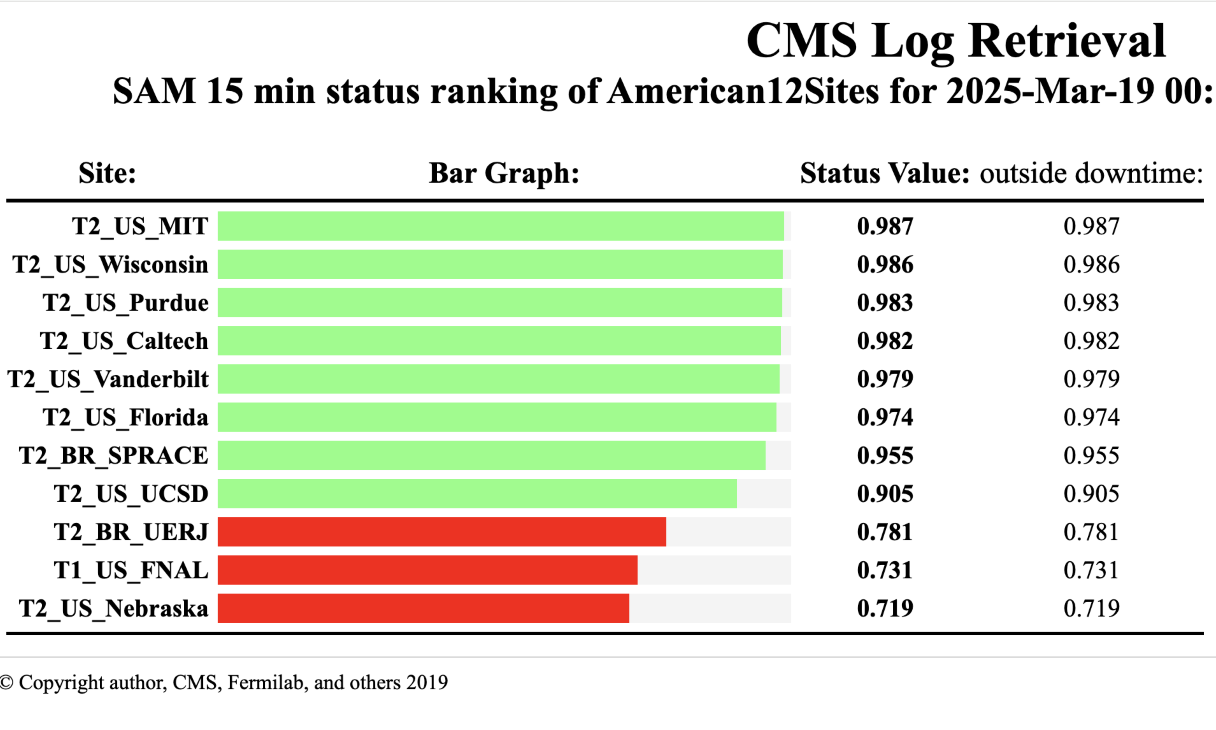
Report from March 18, 2025
SiteReadiness: 99.9%
SAM tests: 99%
Last week we experienced serious issues with ldap server. It was overwhelmed with requests. After fixing issues with ldap our Tier2 show no problems. For several days we pass all CMS tests, as a result we are out of waiting room, CMS started to run production and analysis jobs. I also started to transfer remaining data from HDFS to CephFS. CephFS itself is slowly re-balancing data, it is taking it’s time though, looks like CephFS prioritizes other disk activities like data accessibility over balancing.
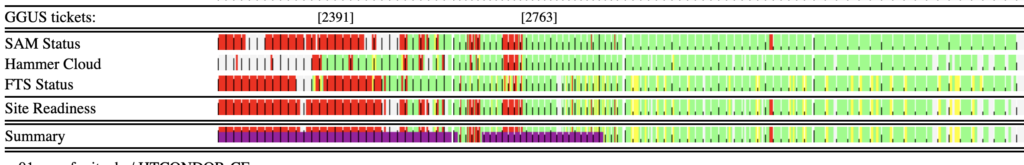
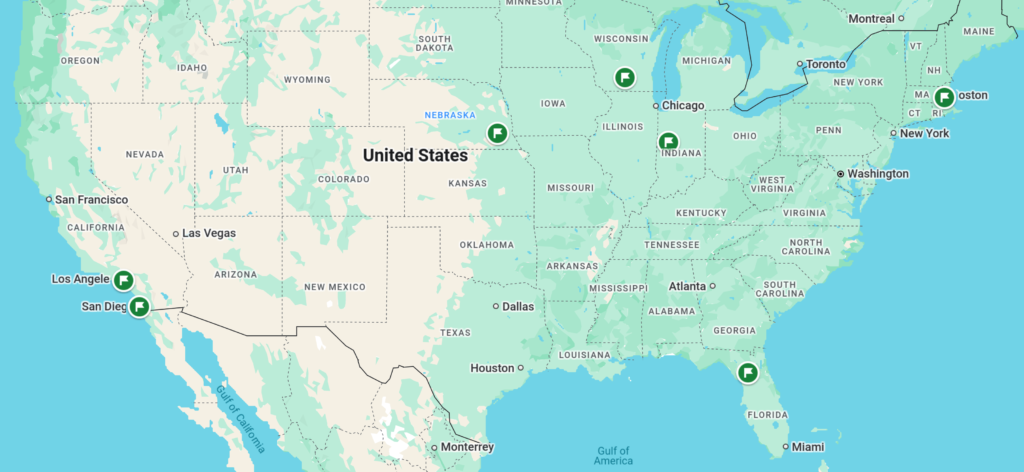
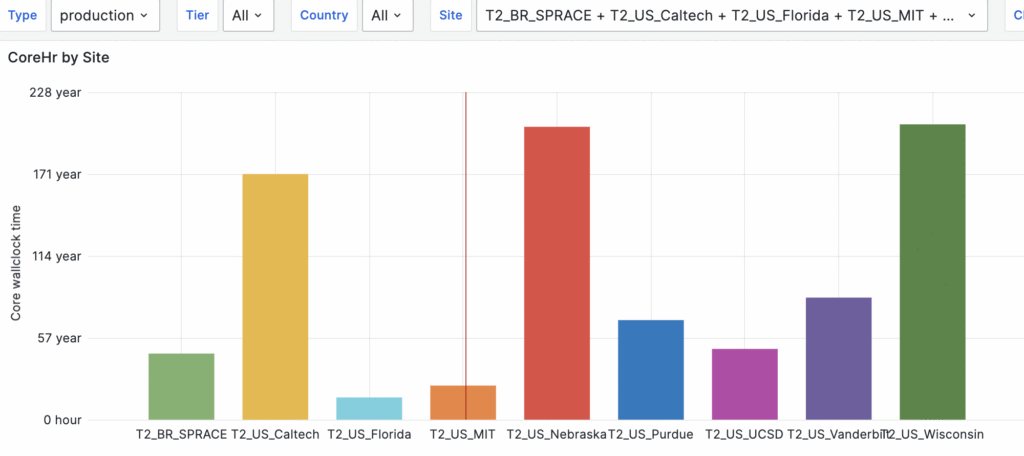
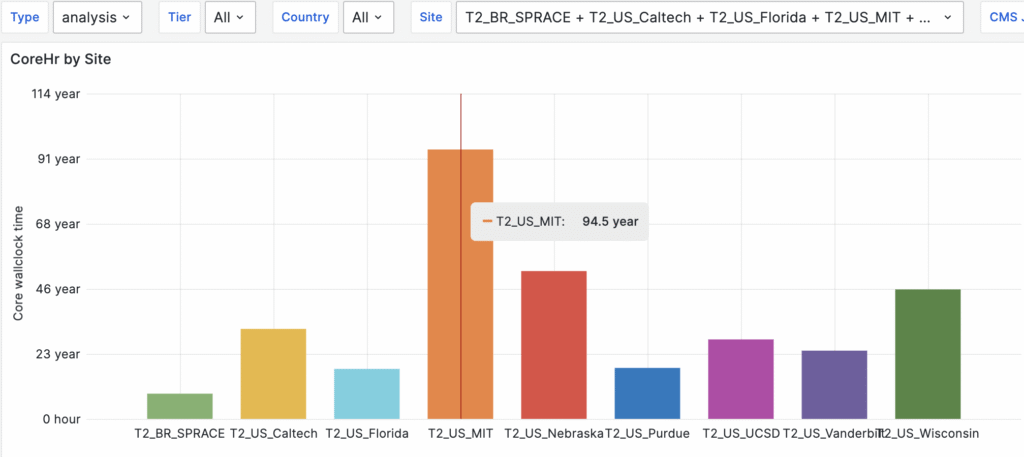
This is a map of all US Tier-2 centers.